Short answer. High Bandwidth Memory, or HBM, is the fast working memory placed beside an AI accelerator. The accelerator repeatedly needs model weights and temporary working data. HBM stacks DRAM dies vertically and connects them through dense vertical wires, base-die logic, and a very wide package interface, so many bytes can move in parallel over a short physical path. HBM is excellent for data that must stay close and arrive quickly. It does not make every data access fast, remove capacity limits, or replace software decisions. The system still has to decide what belongs in HBM, what can live elsewhere, when data should move, and whether that movement helped a real task finish correctly.
July 23, 2026 update: AMD Helios is now part of the production memory story. At Advancing AI 2026, Lisa Su said the Helios reference design is in full production. AMD says shipments are scheduled to start at the end of Q3 and ramp through Q4. One Helios rack combines 72 launched MI455X accelerators across 18 four-GPU trays, with 432 GB of HBM4 and 23.3 TB/s of published peak HBM bandwidth per accelerator, or 31 TB and 1.7 PB/s of published aggregate peak HBM bandwidth at rack scope. That gives an operator more room for hot weights, KV state, activations, and communication buffers, but it does not end the memory problem. Useful performance still depends on placement, kernels, ROCm qualification, fabric behavior, power, cooling, packaging, supply, and a workload receipt. Read the complete Helios and MI455X system path, including what AMD proved, what remains vendor-rated, and what has not been observed on a Touchdown run. Primary sources: AMD's Helios launch update, AMD's MI400 launch update, and the official Advancing AI keynote.
July 25, 2026 update: MI350P and the RTX 6000 family now have a workload comparison. The name
RTX 6000can mean four different cards. The new comparison and input-driven calculator keeps RTX 6000 Ada, RTX PRO 6000 Blackwell Workstation, Max-Q, and Server Edition separate. It follows one agent workload through model weights, KV state, HBM3E or GDDR7, host DDR or LPDDR5X, PCIe movement, measured throughput, power, energy, and cost. Vendor specifications are prefilled. Tokens per second, tokens per watt, price, and cost per accepted task stay unknown until the reader supplies a matching receipt.
If you remember one idea, remember this: HBM is the GPU's fast working area, not the entire storage system. The whole point is not the largest bandwidth number on a specification sheet. It is more accepted AI work per dollar, watt, server, and minute without breaking quality or reliability.
Three ways to read this article
| Path | Who it is for | Start with | Decision to leave with |
|---|---|---|---|
| New to HBM | Anyone who wants the complete mental model without assuming a hardware background | Read this opening, then follow the nine-question map in order | Explain what HBM is, why AI needs it, and why the workload still decides whether it helps |
| Business and investment | CEO, CFO, investor, product leader, or operator | Start with the investor concept map, follow one coding-agent task, then read energy and economics and the proof gate | Identify which memory problem a product solves, where its limit moves next, and what receipt separates a real advantage from a specification-sheet claim |
| Engineering | CTO, software, inference, kernel, GPU, memory, package, or facility engineer | Start with useful bandwidth, choose a coding-agent or video trace, then use the technical appendix | Name the exact software object, code path, hardware boundary, measurement, and missing proof |
Every path ends with the same question: what receipt proves that this memory decision improved the accepted result?
The non-technical investor map: why each layer exists
Read this table from left to right. Each new layer solves one part of the memory problem and creates another boundary that still has to be measured. The point is not to memorize product names. The point is to understand why the products exist, what they actually own, and where an attractive claim can outrun its evidence.
| Concept | The problem that creates it | What it actually does | What it does not solve | Follow the exact path |
|---|---|---|---|---|
| Memory wall | Compute can request weights and working state faster than the complete memory system can deliver useful bytes | Names the growing gap among arithmetic, capacity, latency, bandwidth, movement energy, and software locality | It is not one bandwidth number and it is not fixed by buying one faster chip | Start with the accepted task |
| HBM3E and HBM4 | The hottest GPU state needs a wide, short, highly parallel path | Stack DRAM beside the accelerator and connect it through vertical conductors, base-die interfaces, and dense package wiring | HBM does not make capacity unlimited, make every access local, or turn peak bandwidth into application throughput | Build one HBM stack |
| CPU and host memory | Agent control flow, tokenization, retrieval, tools, files, networking, and operating-system work do not disappear when the GPU starts computing | Hold control-heavy code and a larger system-memory tier, then coordinate work with the accelerator | CPU memory is not local GPU HBM. Moving state between them has a topology, latency, bandwidth, energy, and software contract | Follow the CPU tool loop |
| GPU, caches, memory controllers, and HBM | A tensor must travel from a software allocation to the execution units and return as a useful result | Turn operations into loads, stores, cache transactions, HBM commands, arithmetic, and synchronization | A GPU label does not identify the selected kernel, physical traffic, sustained throughput, or accepted-task result | Trace source code to useful bandwidth |
| Scale-up links and switches | One accelerator may not hold all hot weights and state, so nearby accelerators must exchange data | NVLink and NVSwitch, Infinity Fabric, or UALink-class paths connect defined accelerator domains | Link bandwidth is not HBM bandwidth, collective latency, or one flat shared memory pool | Separate the fabric levels |
| NCCL and RCCL | Software needs collective operations such as all-reduce, all-gather, reduce-scatter, and all-to-all across accelerators | Choose and execute communication algorithms over available transports and topologies | They are software libraries, not physical wires, NICs, or proof that a named link carried the bytes | Trace the collective layer |
| NIXL and movement policy | Disaggregated inference needs to identify and move tensors or KV state across different storage and transport backends | Provides a transfer abstraction that can orchestrate a selected backend | NIXL is not NVLink, not a cache policy, and not the physical network | Follow an offload path hop by hop |
| NICs and DPUs such as BlueField or Salina | Network, storage, security, virtualization, and data-movement work can consume CPU time and complicate the accelerator path | Terminate and process named infrastructure functions at the network or storage boundary | A DPU does not add local HBM capacity, become an AI NIC by default, or prove lower task cost | Place the DPU in the hierarchy |
| CMX, VAST, CXL, host DRAM, and NVMe tiers | Reusable context can be too large or too cold to justify permanent HBM residency | Hold state farther from the GPU and restore it before its reuse deadline when that is cheaper than recomputation | A lower tier never becomes HBM. Capacity helps only when identity, transfer, restore, quality, p99 latency, energy, and failure behavior close | Compare placement choices |
| eDRAM, custom HBM, XBM, memory-on-logic, near-memory compute, NAND, and HBF | Standard HBM may still lose on capacity, energy, logic flexibility, package area, cost, or workload-specific movement | Change the distance, interface, logic boundary, media, or granularity for a particular state role | None is a universal HBM replacement. Each changes thermal, yield, repair, software, qualification, supply, and economic obligations | Compare memory roles |
| The joined receipt | Specifications, source code, demos, and vendor benchmarks can describe different systems and different proof levels | Joins one workload, input, software path, hardware topology, counters, time interval, power boundary, output verifier, and cost denominator | It does not generalize beyond the named run without further evidence | Read the proof gate |
Place the current product generations on that map
| System boundary | Memory role | Why it belongs in this article | Evidence boundary |
|---|---|---|---|
| Grace plus Blackwell B200 or GB200 | Grace LPDDR5X holds CPU-side state; Blackwell HBM3E holds the hot GPU working set; NVLink-C2C and the rack fabric connect declared scopes | This is the active NVIDIA teaching baseline for the current coding-agent path | Product and architecture facts are source-backed. The public C-001 GPU run remains uncaptured |
| Vera plus Rubin | Vera expands the control and CPU-memory side; Rubin moves the hot tier to HBM4; BlueField, CMX, NIXL, NVLink, and networking occupy separate movement and persistence roles | This shows why an accelerator roadmap becomes a memory, fabric, CPU, storage, power, and cooling roadmap | Preliminary or roadmap claims remain vendor-scoped until delivered systems and matched workload receipts exist |
| AMD MI455X plus Helios | MI455X uses HBM4; Helios combines 72 accelerators with Venice CPUs and named scale-up and scale-out boundaries | This is the current AMD production-reference comparison and keeps AMD first class instead of treating CUDA as the whole market | AMD's product and rack ceilings are vendor-published. A joined C-001 or V-001 MI455X run remains uncaptured |
| Alternative and custom memory paths | eDRAM, custom HBM, XBM, CXL, NAND, HBF, near-memory compute, and memory-on-logic target different state lifetimes and movement costs | These paths test where the memory wall might move after standard HBM and software optimization | Patent, paper, roadmap, fixture, and proposed states remain separate from shipping and measured evidence |
Start here if this stack is new
Imagine asking an AI coding agent to fix a bug. Before it can return a useful patch, the system has to collect your instructions, read files, turn text and code into model inputs, load learned numbers called weights, create temporary working data, run GPU operations, call tools on the CPU, and check the final change. A video generator follows a different sequence, but it also carries large amounts of working data through repeated GPU operations before anyone can accept the result.
Modern GPUs can perform arithmetic faster than a slow memory path can supply the required numbers. When the next weight, token state, image tile, or temporary result arrives late, compute units wait. HBM exists to make the hottest part of that path wider, shorter, and more parallel.
This article uses two real open-source workload shapes so the hardware never floats away from the user:
C-001is the primary example. A developer asks Hermes Agent, backed by GLM-5.2, to inspect a repository, change code, run tests, repair failures, and return a verified patch. Hermes is the agent system that connects the language model to files, tools, terminal commands, memory, skills, and subagents. GLM-5.2 is a sparse Mixture-of-Experts model. That means it contains many expert parameter blocks, while a router selects only some of them for each token. Its official FP8 configuration records that architecture and numeric format.V-001is the contrast example. Wan2.2 starts with a noisy video representation and repeatedly changes it until a decoder produces a clip. Its A14B variants use different experts during different parts of that denoising process. Aquality gateis the named pass/fail check applied to the output. It is not a promise that every generated clip is useful.
By the end, you should be able to answer five questions without guessing:
- What data does the workload create, and how long must each object remain available?
- Which software layer requests the operation, and which kernel actually runs?
- Which bytes stay on the GPU, reach HBM, cross a fabric, or fall to a lower tier?
- Where do power, heat, cooling, water, supply, and money enter the same task?
- Which facts came from a vendor, which came from source code, which were measured, and which remain unknown?
You only need three technical nouns to start. A tensor is a typed multidimensional array, which is how software represents model weights and working data. A kernel is a device function launched on a GPU so many threads can perform one bounded operation in parallel. A verifier is the rule or program that checks the real output and returns accept or reject. The tensor definition follows PyTorch's tensor contract; the kernel definition follows the CUDA programming model. Verifier is this article's accepted-task contract, not a GPU component.
user asks for useful work
-> software turns the request into model-readable state
-> a serving system schedules operations
-> kernels move and transform tensors
-> GPU compute and memory hardware do electrical work
-> the system may call tools, move state, retry, or wait
-> a verifier accepts or rejects the result
The article keeps that one chain intact. When the left side highlights a code line, an HBM stack, a fabric link, a cooling loop, or a cost field, it is showing another boundary of the same accepted task. It is not changing to an unrelated example.
The whole article in nine questions
| Question | Plain answer | Go deeper |
|---|---|---|
| 1. What does the user need? | A patch or clip that passes a named acceptance check | Start with the user |
| 2. What must the machine remember? | Weights, instructions, active working data, reusable state, tool results, and outputs | Classify the state |
| 3. What is memory physically? | Electrical state stored, sensed, restored, moved, and refreshed by circuits | Follow one DRAM bit |
| 4. What makes HBM different? | Stacked DRAM, dense vertical connections, many parallel channels, and a short package path beside the accelerator | Build the HBM stack |
| 5. What does software control? | Allocation, layout, batching, reuse, kernels, caching, and movement policy determine useful bandwidth | Trace useful bandwidth |
| 6. How do real workloads differ? | A coding agent grows reusable language-model state; video diffusion repeatedly transforms large temporary state | Coding agent · Wan2.2 video |
| 7. When should data move? | Only when the capacity saved is worth the transfer time, energy, risk, and restore deadline | Compare memory tiers |
| 8. Where does the business cost appear? | In hardware capacity, waiting, retries, energy, cooling, failed output, and human review | Trace energy and economics |
| 9. What proves the decision? | One joined record of the workload, software, hardware, measurements, outcome, and caveats | Read the proof gate |
The smallest complete inference loop
Inference means running a trained model to produce an output. It is different from training, where the system changes model parameters. A real inference product contains more than a model call:
| What the person sees | What the machine does |
|---|---|
| The user submits a request | The application gathers instructions, permissions, tools, files, retrieved material, and prior state |
| The system appears to think and act | The tokenizer, serving engine, model, GPU kernels, memory system, CPU tools, storage, and network take turns doing work |
| The user receives a patch or clip | A verifier checks the real output, records accept or reject, and decides whether another paid attempt is needed |
The detailed engineering loop expands those three visible moments:
- The application collects the user request, system policy, tool definitions, retrieved documents, repository state, and prior conversation.
- A tokenizer maps text or code into integer token IDs. A token is a model unit, not necessarily a whole word.
- A serving engine admits the request, chooses a batch and placement, and schedules model work on one or more accelerators. The vLLM architecture overview is one concrete example of how an engine separates the API server, engine core, scheduler, KV-cache manager, and model executor.
- The model reads learned weights and transforms tensors. A tensor is a multidimensional array with a shape, data type, layout, and physical allocation.
Prefillprocesses the supplied input tokens and creates reusable attention state.Decodeproduces later tokens incrementally, usually one generation position per sequence at a time even when many sequences are batched.- The runtime may call a tool on CPUs, storage, a network, or a sandbox. The tool result returns as new context and may create another prefill and decode cycle.
- A verifier checks the actual outcome: tests pass, a patch is reviewable, or a clip passes the named quality gate.
Use this physical-location key before following the hardware path:
| Term | Physical meaning in this article |
|---|---|
| Host memory | CPU-side system memory, normally DRAM. CUDA defines host memory as memory directly connected to the CPU. Unified-memory and system-on-chip designs can blur residency, so a receipt must still name where the bytes physically lived. |
| HBM | Stacked DRAM connected close to the accelerator through dense package wiring. It is the hot device-memory tier in the accelerator examples, not an on-chip cache. |
| SM or CU | A repeated GPU execution block. NVIDIA calls it a streaming multiprocessor, or SM. AMD calls its fundamental execution block a compute unit, or CU. These blocks contain schedulers, registers, execution pipelines, and local memory structures that execute kernel work. |
| Workspace | An operation-specific temporary read/write buffer allocated by a runtime or library. In the GPU examples it commonly consumes device memory even though it is not a model weight, persistent KV block, or accepted output. |
Primary definitions come from the CUDA programming model, AMD's GPU hardware model, Samsung's HBM overview, and the current NVIDIA cuDNN Backend API, whose operation-graph and execution-plan interfaces expose operation-specific workspace sizes.
The hardware path runs underneath those steps at the same time:
token IDs and metadata in host memory
-> model scheduler and device commands
-> weights, KV cache, activations, and workspaces in GPU memory
-> kernels on NVIDIA streaming multiprocessors or AMD compute units
-> cache, memory-controller, HBM-channel, bank, row, and cell activity
-> links to another GPU, host, storage tier, or network when state is not local
-> electrical energy, heat, cooling work, and facility allocation
A GPU is not one large arithmetic box, and HBM is not a bucket inside it. The accelerator package contains compute blocks, registers, caches, schedulers, memory controllers, and link endpoints. HBM packages sit beside the accelerator on a dense package fabric. The controller turns requests into commands across channels, banks, rows, and columns. The physical details vary by vendor and generation, so diagrams in this article show functional boundaries unless a source says more.
Six words you need now, then a complete reference
You do not need to memorize the full stack before continuing. Keep these six words in view:
- A GPU is a parallel processor with many compute blocks.
- HBM is the GPU's nearby high-bandwidth working memory.
- A tensor is an array of numbers with a declared shape and data type.
- A weight is a learned number the model reads while producing an output.
- An activation is temporary working data created while the model runs.
- A KV cache is saved attention state that lets a language model reuse work from earlier tokens.
The full glossary below is a reference. Return to it when a term appears in a code, platform, or measurement section.
| Term | Plain-language meaning | Where it lives in the path |
|---|---|---|
| AI inference | Running a trained model to produce an answer, action, patch, image, or video | The complete request-to-output process, not one chip operation |
| Model | A structured program whose learned numeric parameters transform inputs into outputs | Model code plus weight artifacts loaded by the runtime |
| Parameter or weight | A learned number used by the model | Stored in a model file, then placed in HBM or another memory tier for execution |
| Tensor | A typed multidimensional array | The software object that becomes physical allocations, loads, stores, and transfers |
| Shape | The size of every tensor dimension | Used by model code, compilers, kernels, and memory planners |
| Data type or precision | The numeric encoding and number of bits used for a value | BF16, FP8, FP4, integers, scales, and metadata affect capacity, traffic, math, and error |
| Token | An integer unit consumed or produced by a language model | Created by a tokenizer, stored in request state, and processed by model layers |
| Prompt and context | The instructions and state supplied to the model | System policy, user text, tools, retrieved data, repository files, and prior turns |
| Context window | The model's configured limit or supported span of token positions | A model/runtime contract; it is not a promise that every large request fits useful HBM capacity or latency |
| Layer | A repeated model stage that applies attention, routing, normalization, or feed-forward work | Model architecture and the sequence of operations executed by kernels |
| Attention | A mechanism that lets token positions use information from other positions | Q, K, V tensors, attention scores or equivalent algorithms, KV state, and attention kernels |
| Dense model | Most or all parameters in a layer participate for each token | Weight and compute demand is broadly active on each pass |
| Mixture of Experts, or MoE | A router selects a subset of expert parameter blocks for each token | Adds routing state, expert placement, grouped computation, imbalance, and communication decisions |
| Prefill | Processing the input sequence to establish model state before incremental generation | Often parallel across prompt positions; creates KV cache and can be compute intensive |
| Decode | Producing subsequent token positions using prior state | Often memory and latency sensitive; appends KV state and repeats many small steps |
| KV cache | Saved attention key/value state from earlier token positions | A mutable runtime allocation, commonly in HBM and sometimes restored or offloaded to lower tiers |
| Activation | A temporary intermediate value produced while the model runs | Registers, on-chip memory, HBM, or recomputed state depending on operation and schedule |
| GPU or accelerator | A parallel processor built from many compute and data-movement resources | The package containing compute blocks, caches, controllers, and high-speed link endpoints |
| Kernel | A compiled device function that performs a bounded parallel operation | Launched by the runtime and executed across GPU work groups, warps, or wavefronts |
| Cache | A faster structure that keeps recently or strategically useful state near compute | GPU registers, shared memory, L1/L2, software prefix caches, and KV tiers are different mechanisms |
| HBM | Stacked DRAM beside an accelerator with a very wide local interface | The hot external-memory tier on the accelerator package |
| Memory controller | Logic that schedules and translates memory requests into device service | Between GPU requesters and HBM channels, banks, rows, and timing rules |
| Interconnect or fabric | Hardware and protocol that move data between components | NVLink/NVSwitch, Infinity Fabric, PCIe, CXL, NICs, and scale-out networks have different scopes |
| Bandwidth | Bytes that can be moved per unit time under a declared boundary | A rate, not a latency or accepted-task result |
| Latency, p95, and p99 | Latency is elapsed time between two named events. If 100 comparable requests are ordered from fastest to slowest, p95 is roughly where the 95th request finishes and p99 exposes the rarer slow tail. Formally, both are quantile estimates from a finite sample. | Can describe a load, transfer, first token, token gap, tool call, or whole task, so the endpoints, sample population, sample count, interval, and percentile estimator must be named |
| Throughput | Useful work completed per unit time | Tokens, requests, clips, or verified tasks per second or hour |
| Concurrency and batch | How many requests are active and which work is grouped together | A scheduler decision that changes HBM occupancy, queueing, kernel shape, and tail latency |
| Offload and prefetch | Moving state to a lower tier and bringing it back before it is needed | HBM to host DRAM, CXL-attached memory, device memory, NVMe, or another node through a named path |
| Verifier and accepted task | The rule that decides whether an output is actually useful | Tests, review, quality checks, policy gates, and the denominator for cost and energy |
| Receipt | A joined record of what ran, where, with which inputs, measurements, and outcome | The evidence object connecting software, hardware, facility, and business claims |
The terms are related but not interchangeable. A model is not a serving engine. A serving engine is not a kernel. A kernel is not an instruction. HBM capacity is not KV capacity. Link bandwidth is not memory bandwidth. A generated token is not a verified task.
Follow one line of code into the machine
Consider one PyTorch scaled dot-product attention operation:
out = torch.nn.functional.scaled_dot_product_attention(
q,
k,
v,
is_causal=True,
)
The line expresses a mathematical operation. It does not uniquely name the kernel, instruction sequence, cache behavior, or HBM command stream. The actual path depends on tensor shapes, dtype, layout, device, framework revision, serving engine, compiler state, backend selection, batching, and hardware.
| Boundary | What happens | Evidence needed before making a physical claim |
|---|---|---|
| Python/model code | The model requests scaled dot-product attention over q, k, and v |
Pinned source, input shapes, dtype, layout, and model revision |
| Serving engine | vLLM, SGLang, or another engine chooses request grouping, pages, cache state, and model-runner inputs | Engine config, scheduler trace, cache events, and request identity |
| Framework dispatch | PyTorch and the selected backend choose an implementation compatible with the inputs and hardware | Framework/backend versions and dispatch or profiler evidence |
| Compiler and executable | A selected backend lowers the operation through one or more intermediate forms into a target-specific device executable | Saved source, IR, binary, compile flags, target architecture, and disassembly where permitted |
| Kernel execution | Threads cooperate to load tiles, compute attention work, synchronize, and store results | Kernel name, launch geometry, device timeline, counters, and correctness result |
| On-chip data path | Registers, shared memory or local data share, and caches serve some accesses | Profiler counters or a bounded architecture model; not source-code inference alone |
| HBM path | Misses and explicit transfers reach controllers, channels, banks, rows, and I/O | Named hardware counters, simulator events, or vendor-scoped evidence |
| Fabric path | Sharded state may cross a scale-up or scale-out link | Topology, collective/transfer trace, endpoints, bytes, and timing |
| Product outcome | The operation contributes to a token, tool step, patch, or clip | Joined task trace and verifier result |
Do not read compiler terms as peers. They occupy different levels:
model operation
-> framework dispatch
-> backend or compiler
-> intermediate representation
-> device executable
-> hardware instruction
| Term | Category | Exact role |
|---|---|---|
| CUDA | NVIDIA platform, programming model, and toolkit | CUDA includes runtime APIs, compilers, libraries, debugging tools, and optimization tools. It is not one instruction set or one binary format. |
| PTX | NVIDIA virtual ISA and compiler intermediate form | PTX is a low-level virtual instruction set that is translated offline or just in time into instructions for a target NVIDIA GPU. PTX is not the final target-specific machine binary. |
| cubin and SASS | NVIDIA target binary and architecture-specific assembly | A cubin is a binary file for a specific SM target. cuobjdump -sass disassembles cubin code into the architecture-specific CUDA assembly instruction stream commonly called SASS. The cubin file and its disassembled instructions are related but are not the same artifact. |
| HIP | C++ runtime API and kernel language | HIP is a source and runtime programming surface. On AMD ROCm, HIP-Clang or amdclang++ compiles device code through the AMDGPU backend. HIP is not an ISA. |
| LLVM IR and AMDGPU backend | Compiler representation and target backend | LLVM IR carries compiler-visible operations. The AMDGPU backend lowers compatible IR into AMDGPU ISA and packages executable machine code and metadata into an AMD GPU code object. |
| Triton | Kernel language and compiler | Triton is a language and compiler for custom GPU primitives. Its compiler uses MLIR and LLVM-based backend stages to produce target artifacts such as PTX or AMDGPU code. Triton is not CUDA, HIP, PTX, or a hardware ISA. |
Primary references: CUDA Toolkit, PTX ISA, CUDA platform compilation, CUDA binary utilities, AMD HIP, AMD HIP compilers, LLVM AMDGPU backend, and the Triton compiler repository.
One source line can trigger many kernels. One kernel can execute the same instruction across many threads. One tensor read can hit a cache or reach HBM. A controller can reorder physical requests while preserving the programming contract. That is why the left visual uses color to show the active boundary but keeps unknown values marked unknown.
How to read the colors and diagrams
- Blue active marks show the boundary currently being explained. They do not claim that every byte followed that path in a measured run.
- Yellow text marks the accepted-task or executive decision boundary.
- Gray text or panels expose engineering conditions, assumptions, and lower-level mechanisms.
- Dashed marks and
?labels mean unknown, unmeasured, configuration-dependent, not public, or not applicable until a receipt resolves the field. - Side-by-side NVIDIA and AMD slots compare the same functional question. They remain blank or qualified when the public evidence scopes differ.
- Animated particles, fills, or heat paths are schematic state transitions. A visual becomes a measured trace only when it is bound to a named replay receipt, counter source, clock interval, and topology.
The visual can simplify geometry. It cannot simplify evidence. If a diagram shows a GPU block lighting up, read it as this is the functional area under discussion, not we measured these exact transistors switching.
How to read the evidence labels
These labels stop a product announcement, a source-code path, a model, and a measured run from being treated as the same proof.
- Measured or captured evidence includes
[PAPER, MEASURED]and a joined workload receipt when one exists. - Shipping or vendor-reported evidence includes
[SHIPPING VENDOR ARTIFACT]and[VENDOR TARGET / BENCHMARK]; the vendor and setup remain part of the claim. - Modeled or derived evidence includes
[PAPER, MODELED]and[TOUCHDOWN DERIVATION]; the assumptions remain visible. - Proposed evidence includes
[PATENT APPLICATION],[FIXTURE BACKED], and[PROPOSED]; these show a design, code path, or testable hypothesis without proving live workload execution. - Unknown evidence includes
[NOT FOUND]; a missing receipt stays missing.
The exact definitions used throughout the article are:
- [STANDARD] means an unrestricted public standards-body page or announcement defines a capability or term. It does not prove a product or workload result.
- [SHIPPING VENDOR ARTIFACT] means a vendor says a named commercial artifact ships or is in production. Its performance claims remain vendor-reported unless independently measured.
- [VENDOR TARGET / BENCHMARK] means a roadmap, internal test, or vendor benchmark. It applies only to the named setup.
- [PATENT APPLICATION] means an architecture appears in a published application. It does not prove working silicon, a product, yield, cost, performance, or schedule.
- [PAPER, MEASURED] and [PAPER, MODELED] retain the paper's exact apparatus. A modeled chip is not fabricated silicon.
- [AUTHOR WORKLOG] is a public engineering report without independent reproduction.
- [TOUCHDOWN DERIVATION] is transparent arithmetic from cited inputs, not a measurement.
- [FIXTURE BACKED] means code or a schema passes saved tests. It is not live hardware proof.
- [PROPOSED] means a hypothesis or experiment that still needs evidence.
- [NOT FOUND] means a required public receipt was not located.
That distinction matters because HBM is shipping technology, Intel XBM is a patent application, Sandisk HBF is a proposed direction with vendor simulation, and a Touchdown state contract is a research hypothesis. Putting all four in one table without those labels would manufacture certainty that does not exist.
What breaks when an AI system cannot keep the right state close to compute?
In plain English. An AI system can own a fast GPU and still feel slow or expensive because the GPU keeps waiting for data, recreating data it already had, or moving data through the wrong tier. We begin with the result a person will accept, then work backward to the exact state that missed its deadline.
Start with the user.
A designer requests an 81-frame video. The clip is useful only if it follows the prompt, looks coherent, arrives before the product deadline, has the expected format, and costs an amount the product can support.
A developer asks a coding agent to inspect a repository, change a function, run the tests, repair a failed patch, and return a reviewable diff. The answer is useful only if the change is correct, the tests pass, the patch does not quietly break another path, and the developer does not spend the saved time debugging the agent.
Neither user buys terabytes per second. Neither user buys FLOPs. They buy an accepted clip or an accepted code change.
Memory enters because both workflows create state that has to remain available across time. The video request has prompt embeddings, model weights, a noisy latent, Q/K/V tensors, normalization and feed-forward intermediates, attention metadata, communication buffers, and decoded frames. The coding request has system instructions, tool schemas, a repository map, selected files, model weights, active KV cache, reusable prefixes, tool results, patches, test logs, and prior decisions.
Some of that state is tiny and hot. Some is large and read-only. Some is append-only. Some changes every step. Some can be regenerated. Some must survive a process crash. Some needs to arrive within microseconds or milliseconds. Some can wait for a storage read. The memory decision begins there, not with a product name.
The state object comes before the tier
Start with one concrete object: the KV cache is the language model's working record of earlier tokens. Before deciding where it belongs, the system needs to know whose request it belongs to, how large it is, whether it will grow, when it will be read again, how quickly it must arrive, and whether it can be rebuilt. The same questions apply to a video latent, a model-weight tile, a tool result, or a checkpoint.
Before saying HBM, CXL, host memory, or NVMe, write down the object:
| Field | Actual question |
|---|---|
| Identity | Is this a weight tile, latent, Q/K/V tile, KV block, stable prefix, tool result, repository map, checkpoint, or output? |
| Shape and bytes | What is its real shape, dtype, layout, padding, allocation size, and replication? |
| Access | Is access sequential, strided, gathered, sparse, random, or broadcast? |
| Mutability | Is it read-only, append-only, read-write, disposable, or durable? |
| Reuse | How soon will it be read again, how often, and by how many consumers? |
| Deadline | What first-byte and full-object p95/p99 deadline applies? |
| Correctness | Must it be exact, can it be reconstructed, or is bounded approximation allowed? |
| Movement | What source, target, interconnect, granularity, and fallback are permitted? |
That table prevents three common errors.
First, model memory is not one thing. Read-only weights, mutable KV, temporary attention tiles, optimizer state, and checkpoints have different contracts.
Second, more capacity is not automatically useful. A lower tier can hold an object and still lose if the object arrives after the compute window, if page overfetch dominates, or if the miss path creates a p99 spike.
Third, faster memory is not automatically more valuable. HBM space occupied by cold repository artifacts can reduce concurrency for active inference state. A carefully selected lower tier can free the hot tier, but only if transfer and reuse are measured.
Where the leak appears
For video diffusion, the failure can appear as a model offload between steps, a latent spill, repeated materialization of intermediates, a gather pattern that does not use the memory channels well, or a collective that leaves compute waiting. The result is a longer denoising loop, less concurrency, more GPU-seconds, or a quality-losing optimization.
For a coding agent, the failure can appear as repeated prefill over the same repository prefix, evicted KV blocks, cold tool results, a blocked CPU sandbox, a failed patch, or another model call needed to recover state that was already known. The result is longer time to first useful token, more tool-loop latency, more retries, and more human review.
The accounting boundary is the accepted task:
total_cost_per_accepted_task_USD =
(accelerator_cost_USD
+ CPU_and_tool_cost_USD
+ memory_storage_network_cost_USD
+ facility_energy_and_water_cost_USD
+ retry_and_failure_cost_USD
+ human_rework_cost_USD)
/ accepted_tasks
[PROPOSED LEDGER] This is a cost-allocation shape, not a claim that every term is easy to observe. Every numerator field is denominated in USD before addition. The raw receipt must separately preserve accelerator and CPU/tool seconds; allocated and transferred bytes by tier and link; joules or kWh; water liters by declared boundary; retry and failure counts; accepted-output count; and verifier result. Named prices and allocation rules convert those physical quantities into cost. Seconds, bytes, joules, liters, and counts must not be added directly. If accepted_tasks is zero, the ratio is undefined and that state must be reported explicitly.
The technical path in this article will fill in that ledger one boundary at a time:
user request
-> software state
-> runtime and kernel
-> cache and controller
-> HBM channel, bank, row, and cell
-> package power and heat
-> server and facility
-> accepted output
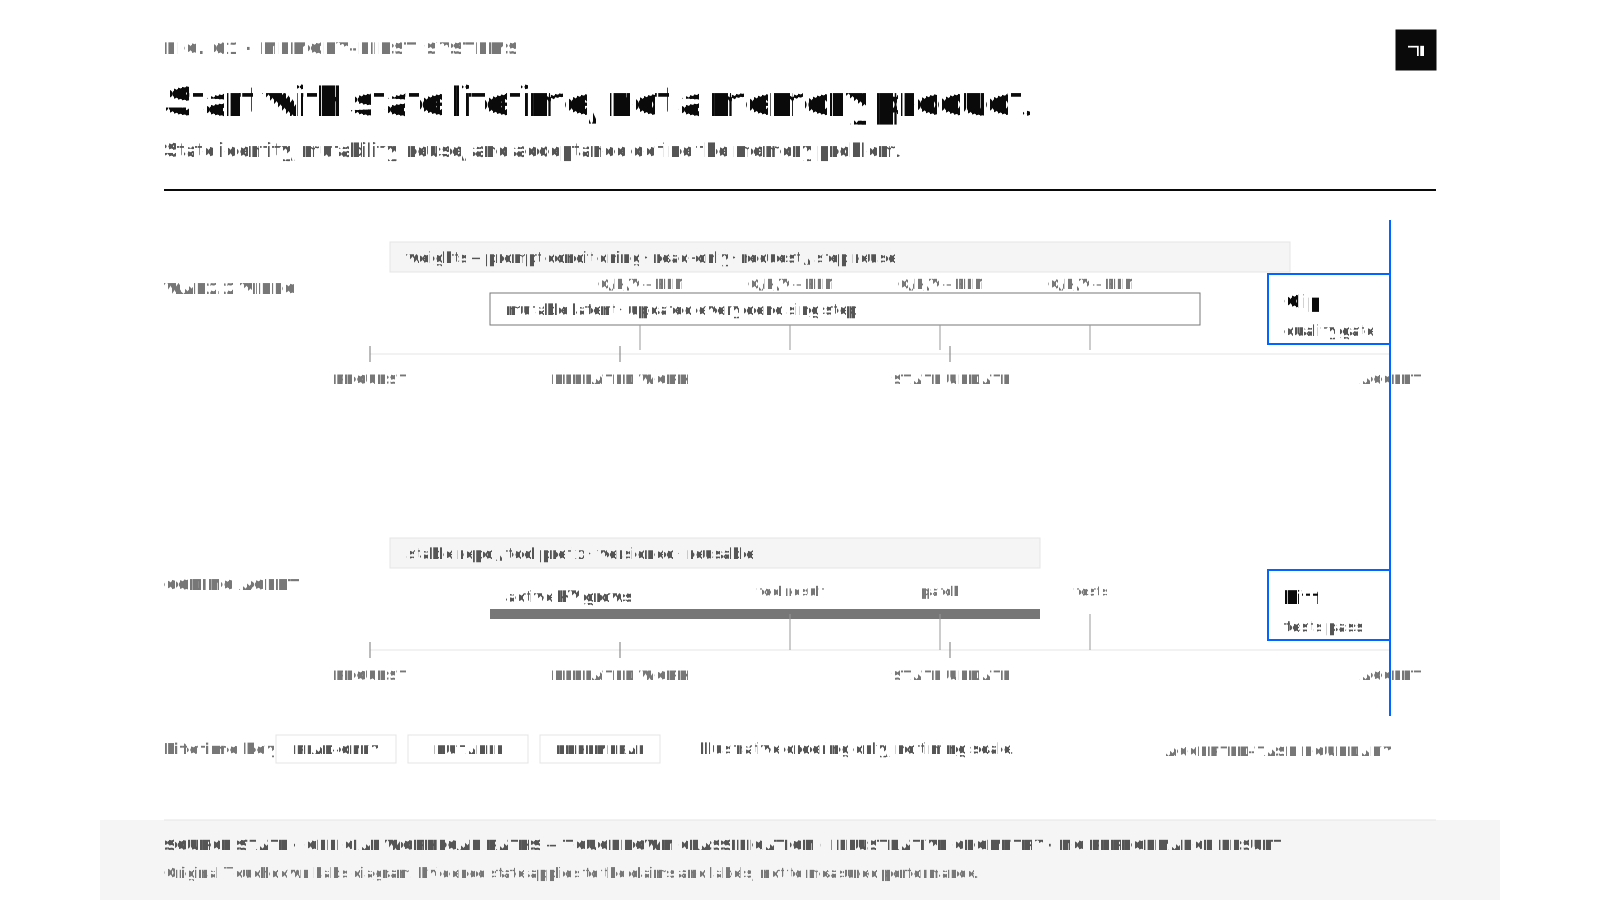
What this means by role. The CEO defines accepted output. The CFO asks where repeated work is paid twice. The CTO identifies which state limits concurrency and p99. The software engineer traces the object through allocation and movement APIs. The kernel engineer identifies the load, store, gather, or synchronization that creates the bytes. The hardware engineer asks what address distribution and service deadline reach the controller.
Now we can descend the stack. What does it mean to store one bit in the first place?
What is one bit of memory, physically?
In plain English. A DRAM bit begins as a tiny amount of electrical charge. A useful bounded analogy is a leaky cup connected to a shared measuring wire by a switch. The capacitor is the cup, the access transistor is the switch, the bitline is the measuring wire, and the sense amplifier reads the weak signal and restores what the read disturbed. The analogy stops there: the real device is an electrical circuit governed by voltage, capacitance, noise, timing, temperature, and fabrication variation.
A bit is not a microscopic printed 0 or 1. It is a physical state that a circuit agrees to interpret as one of two logical values.
In a dynamic random-access memory cell, that state is charge associated with a tiny capacitor. In a static random-access memory cell, it is the stable state of a feedback circuit. In NAND flash, it is related to the threshold behavior of a storage device. The software abstraction is the same bit. The physical promises are different.
Micron's Introduction to Memory is the foundational public teaching source for the DRAM cell, sensing, row and bank organization, read and restore, and refresh path summarized here. [OFFICIAL VENDOR EDUCATION]
Charge, voltage, and a DRAM cell
The first useful relation is:
Q = C * V
Q is stored charge, C is capacitance, and V is voltage. The equation does not describe an entire memory system. It explains why a very small capacitance and small stored charge produce a small signal that must be sensed carefully.
A conventional DRAM cell is often described as 1T1C: one access transistor and one capacitor. The access transistor behaves like a controlled switch. Its gate connects to a wordline. One side of its channel connects the cell capacitor to a bitline.
Before a read, the bitline is prepared to a reference condition. The controller selects a row. A row decoder raises the corresponding wordline, turning on many access transistors along that row. Each selected cell shares a small amount of charge with its bitline. The bitline voltage moves slightly above or below its prepared level depending on the stored state.
That tiny movement is not yet a robust digital value. A sense amplifier compares and amplifies it to a full logic level. The row's resolved values become available in the row buffer, which is built from the active sense-amplifier state.
The read is destructive in the practical sense that charge sharing disturbs the cell. The sense amplifier therefore also restores the value into the capacitor while the row remains active. Later, the array precharges its bitlines so another row can be opened safely.
The complete local path looks more like this than a software load:
precharge bitline
-> raise wordline
-> cell and bitline share charge
-> sense amplifier resolves small delta
-> row buffer holds full logic state
-> column path selects requested data
-> sense amplifier restores cell
-> close row and precharge for later access
A write reverses part of the intent. The write circuitry drives the desired bitline state, opens the access device, and charges or discharges the cell toward the new value. The array still has timing requirements for activation, write recovery, precharge, and interference control.
Why DRAM needs refresh
The cell is not a perfect bucket. Charge leaks through device and dielectric paths. Temperature, process variation, cell history, coupling, and disturbance affect how quickly a usable sensing margin shrinks.
DRAM therefore refreshes stored rows. A refresh operation restores charge even if software did not request the data. Refresh consumes command opportunities, internal activity, and energy. It can interact with tail latency because a demand request may arrive while some internal resource is unavailable.
It is still misleading to say refresh makes DRAM slow as if one number explains the system. Modern devices organize refresh and parallelism in implementation-specific ways. The observed penalty depends on generation, temperature, bank activity, controller policy, workload, and measurement boundary. The safe statement is narrower: refresh is mandatory work that a useful-bandwidth and energy model must include.
SRAM, eDRAM, and NAND make different bargains
SRAM usually stores a bit in a multi-transistor bistable circuit. As long as power remains and operating conditions hold, feedback maintains the state without periodic DRAM-style refresh. SRAM can provide fast, fine-grained access and sits close to compute in registers, caches, and scratchpads.
The cost is area and leakage. A multi-transistor cell takes much more silicon per bit than a dense DRAM cell. That is why an accelerator can have a valuable on-chip cache but not replace all HBM capacity with the same kind of SRAM at the same die size and cost.
Embedded DRAM, or eDRAM, puts dynamic cells closer to logic in a process designed to support them. It can offer more capacity than an SRAM structure in a given role while retaining dynamic-memory behavior such as refresh. It is not SRAM but denser, and it is not HBM on the logic die. Process integration, capacitor construction, thermal behavior, peripheral circuits, refresh policy, test, and yield all change.
NAND flash makes a different trade. It stores nonvolatile state and reaches very high density, but its useful access and update units are much coarser. Reads are page-oriented. Programming and erasing have their own granularity, latency, endurance, and controller requirements. A fast sequential flash stream is not a fine-grained DRAM load. That distinction will matter when we reach HBF and Carmack's deterministic-page argument.
| Cell or medium | Retention behavior | Read/write character | Density direction | Typical role here |
|---|---|---|---|---|
| SRAM | Volatile while powered, no periodic DRAM refresh | Fast, fine-grained read and write | Lowest density in this comparison | Registers, caches, scratchpads |
| DRAM family | Volatile, refresh required | Fine-grained external interface backed by row operations | High | Working memory: HBM, DDR, LPDDR, GDDR |
| eDRAM | Volatile, refresh required | Near-compute dynamic working memory | Between SRAM and external DRAM in role, process-dependent | Workload-specific integrated memory |
| NAND | Nonvolatile | Page reads, programmed pages, erased blocks | Very high | Deep capacity, storage, read-mostly streams |
Energy is a chain of events, not one formula
Two physical approximations are useful:
dynamic_switching_energy scales with alpha * C * V^2
wire_delay scales with R * C
alpha is activity, C is switched capacitance, V is voltage, R is resistance, and RC is a first-order way to understand why longer, narrower, or more heavily loaded wires are harder to drive quickly.
Lower voltage can reduce switching energy, but it also changes noise margin, sensing, timing, and circuit design. Shorter wires can reduce capacitance and delay, but dense packaging adds routing, coupling, thermal, mechanical, and manufacturing constraints. Narrow interconnects can raise resistance. High simultaneous current can create voltage droop and I^2R conduction loss.
Real memory energy includes wordline drivers, sense amplifiers, row activation, restore, precharge, refresh, local and global buses, clocks, I/O, PHYs, controller work, error correction, and leakage. At the system level, it also includes link endpoints, voltage conversion, fans or pumps, and facility overhead. A C V^2 estimate is physical intuition. It is not a measured joule-per-token result.
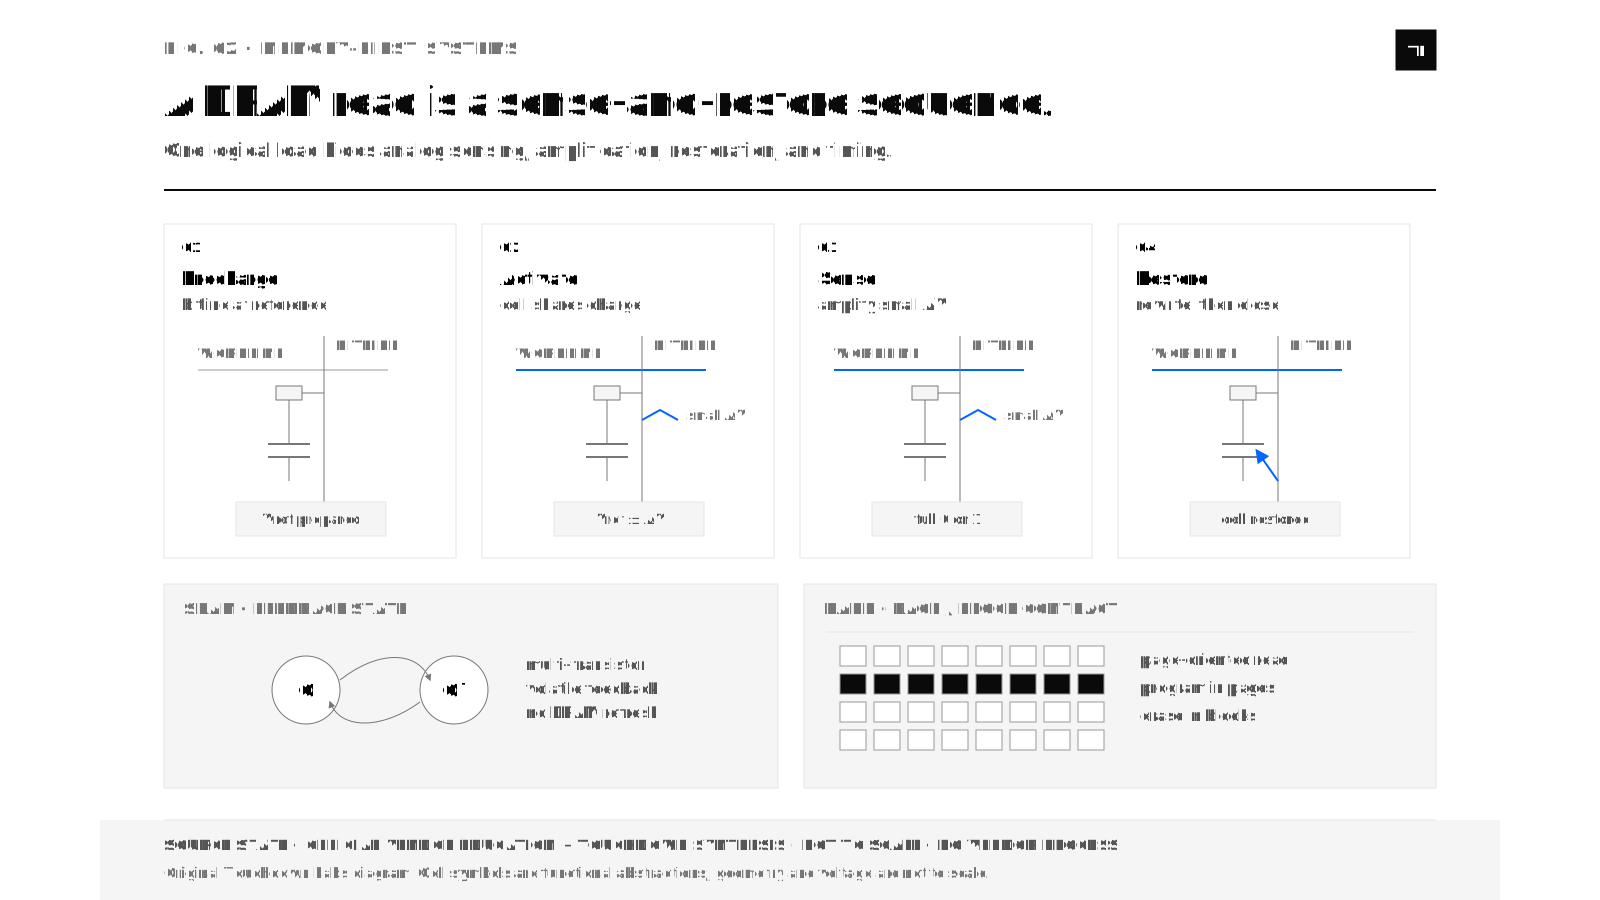
What this means by role. For software, one load hides an array-level sequence. For a memory engineer, sensing margin, refresh, timing, and variation are first-order constraints. For a CFO or investor, cell area, retention work, yield, and process complexity determine how much usable capacity can be built and powered. The logical bit is the beginning, not the product.
How does a DRAM bit become an HBM stack beside a GPU?
In plain English. HBM does not use a magical new kind of bit. It makes ordinary DRAM more useful to an accelerator by stacking dies, dividing work across many banks and channels, connecting the stack vertically, and placing it beside the accelerator on dense package wiring. The result is a much wider local path. The cost is harder packaging, power delivery, cooling, testing, repair, and yield.
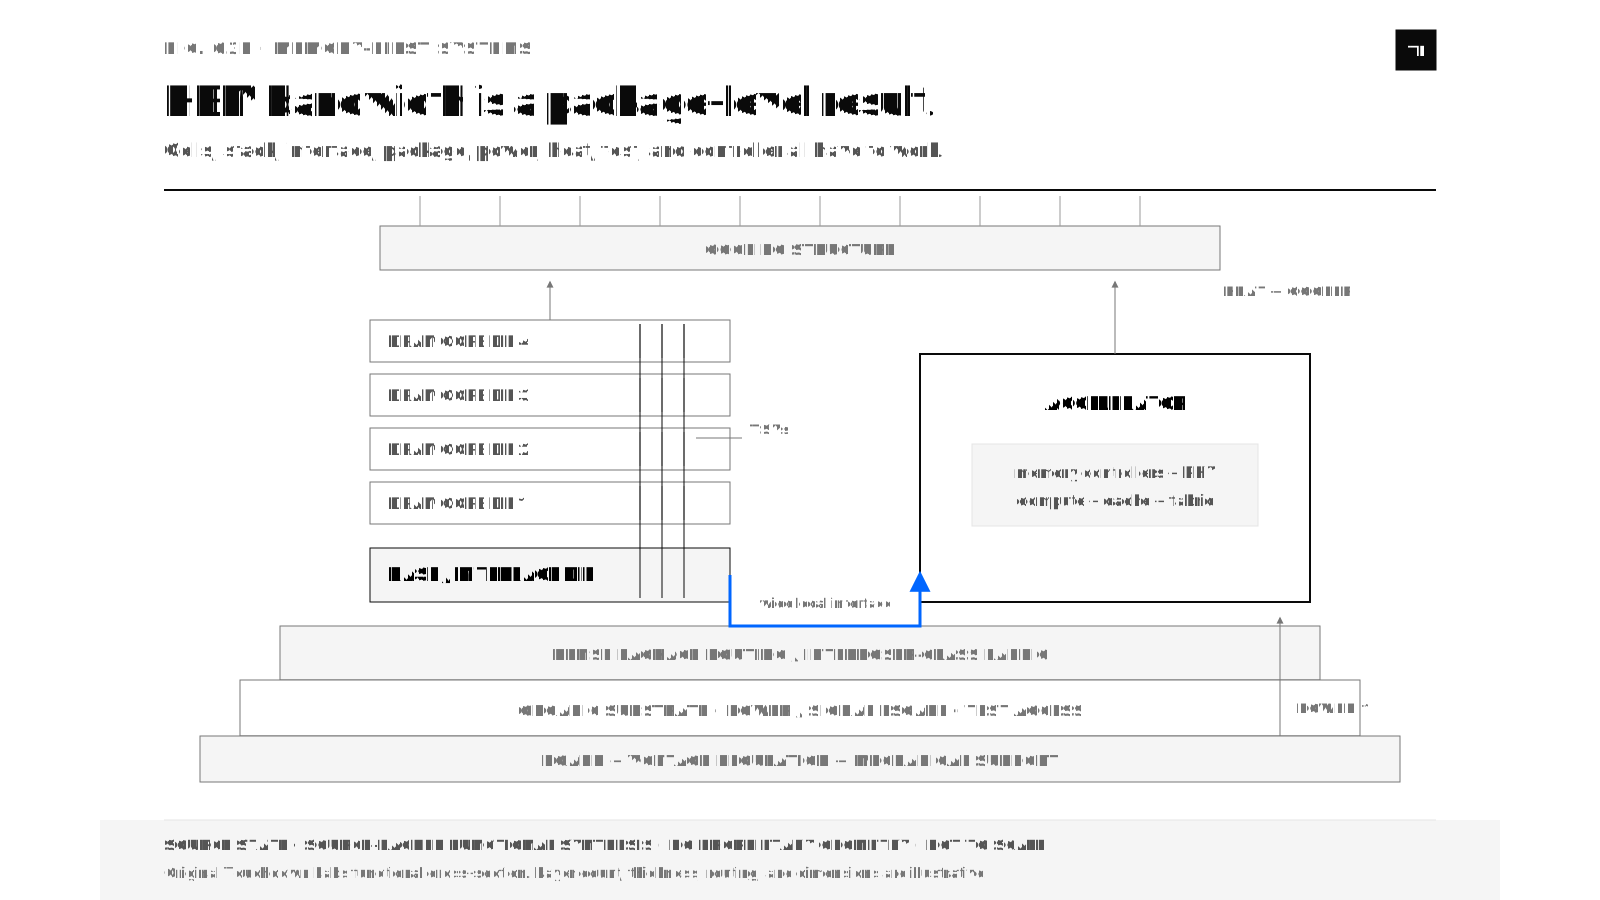
High Bandwidth Memory is not a different logical kind of memory. It is a tightly organized and packaged form of DRAM designed to expose a very wide aggregate interface near compute.
That sentence contains the main engineering idea. HBM does not get its value from one magical fast cell. It gets value from hierarchy, parallelism, proximity, a wide interface, vertical die connections, a logic/interface layer, and a package that connects memory to an accelerator at high density.
Samsung's public HBM overview illustrates the stacked-DRAM and TSV direction. SK hynix and TSMC's base-die announcement establishes the public logic-base-die design surface for named HBM development. [OFFICIAL VENDOR EDUCATION / ROADMAP]
From one cell to many banks and channels
Cells sit in arrays. Arrays are divided into structures that let the device activate some storage while other storage can serve or prepare different work. Terms vary by generation, but the useful hierarchy is:
cell
-> local bitline and sense amplifier
-> row buffer
-> subarray
-> bank
-> bank group and pseudo-channel organization
-> channel
-> die interface
-> vertical stack connection
-> base or interface logic
-> package route
-> accelerator memory controller
A bank is an independently managed array region with local sensing and row state. When a row is activated, the bank's row buffer holds the sensed row. A read or write command then selects columns from that open row.
If the next access targets the same open row, the device can use the row-buffer state. That is a row hit. If it targets a different row in the same bank, the current row may need to close and the new row to activate. That is a row conflict. If independent requests map across different banks or channels, the controller may overlap more of their work.
This is why an address is also a scheduling decision. The physical address bits, memory-controller mapping, tensor layout, stride, alignment, and request order influence which channels, banks, rows, and columns receive traffic. A large contiguous tensor can still use the hardware badly if its stride or mapping concentrates requests. An irregular gather can expose latency even when the device's headline bandwidth is enormous.
The command path includes operations commonly abbreviated as:
ACT: activate a row into sensing/row-buffer state.RD: select and return data from an active row.WR: select and update data in an active row.PRE: precharge or prepare the bank to open another row.REF: perform required refresh work.
Each has timing relationships. Commands cannot be issued arbitrarily close together. Power limits can also constrain how many activations occur in a window. Read-to-write and write-to-read direction changes consume bus and device time. Error correction, repair, and reliability mechanisms add logic and sometimes traffic.
The important result is not that one operation is always expensive. It is that useful service depends on the distribution and scheduling of many operations.
HBM makes the path wide and local
Conventional host DRAM modules favor capacity, serviceability, and a CPU-oriented memory system. Graphics memory favors high per-pin rate across discrete memory devices. HBM takes a different physical route: stack multiple DRAM dies, create vertical connections through the stack, expose many narrower channels or pseudo-channels, and place the stacks beside the accelerator on a dense package fabric.
A wide local interface can move many bits per transfer without requiring every pin to run at the highest possible signaling rate. More independent channels also give the controller more places to schedule outstanding work. The short package route reduces the electrical distance relative to board-level memory interfaces.
The theoretical interface calculation is simple:
peak_payload_bandwidth =
transfers_per_second * interface_width_bits / 8
The word payload matters. A vendor may report an interface data rate, a per-stack bandwidth, a device bandwidth, or a whole-accelerator aggregate. The number may be based on a maximum rate rather than a sustained workload. The comparison is valid only when the scope, encoding, direction, and count of stacks match.
Useful bandwidth is a different quantity:
useful_bandwidth = useful_bytes_completed / wall_clock_time
utilization_of_peak = useful_bandwidth / peak_payload_bandwidth
Useful bytes must also be defined. If a kernel reads the same weight three times because tiling is poor, physical traffic can rise while useful tensor bytes stay unchanged. If a cache serves a request, HBM traffic can fall while the kernel still completes. If compression reduces link bytes but adds computation, the user may win or lose depending on the deadline.
Through-silicon vias are vertical wires, not free bandwidth
A through-silicon via, or TSV, is a conductor that passes vertically through thinned silicon. At a functional level, the structure needs a conductive path, electrical isolation from the silicon where required, reliable contacts to routing layers, and a geometry that can survive fabrication, thinning, bonding, thermal cycling, and current stress.
TSVs let signals and power travel through a stack rather than escaping every die to a wide board perimeter. They also consume area, create keep-out and stress concerns, add capacitance and resistance, and require testable connections. The exact formation sequence, metal system, dimensions, liner, barrier, and reveal process depend on vendor and generation. A research result for one narrow interconnect material is not evidence that an HBM vendor uses it throughout a stack.
The stacked dies need electrical and mechanical bonds. Shipping generations may use microbump-based connections, and industry development is moving toward finer-pitch direct or hybrid-bonding directions in advanced packages. It is unsafe to write that every HBM4 product uses one specific bond flow. The article therefore names the function and cites a named product when discussing its implementation.
The base die is where memory and logic meet
At the bottom of an HBM stack sits a base or interface die. Its job is not identical in every design. Broadly, it connects the vertical stack to the package interface and hosts interface, control, test, repair, RAS, and physical-layer functions according to the generation and vendor partition.
This is becoming technically important because advanced logic on the base die can do more than terminate wires. [VENDOR DESIGN SURFACE / PROPOSED] In a named custom design, it could host selected address translation, movement control, security, telemetry, reliability, or carefully bounded near-memory operations. Those functions do not exist in every HBM4 base die. That is the reason custom HBM and SPHBM4 matter later in this article.
The opportunity has a physical cost. Logic consumes power and area. It creates heat below a stack of temperature-sensitive DRAM. It needs a qualified process, known-good-die strategy, clock and power delivery, test access, repair behavior, and software contract. Moving a function to the base die is not automatically better than running it in the accelerator, controller, or software.
[SHIPPING VENDOR ARTIFACT] Samsung says its commercial HBM4 uses a logic base die manufactured on its 4 nm process, and Micron says it has begun volume production of a named HBM4 product for a named customer program. Those statements establish vendor-reported commercial artifacts as of their announcements. They do not make every performance or power number independent, and they do not establish a standard partition for all HBM4.
The interposer or package fabric closes the path
The accelerator and HBM stacks need dense horizontal wiring. A silicon interposer is one established way to provide that routing. Bridge and redistribution-layer package approaches create other topologies. The dense layer connects to an organic substrate, which connects the package to the board and the rest of the system.
The package therefore carries more than data:
- Power arrives from board-level voltage regulation through planes, vias, package structures, bumps, and on-die grids.
- Return current needs controlled paths.
- Clocks and commands need timing margin.
- Simultaneous switching creates noise and voltage droop.
- Dense neighboring wires create crosstalk.
- Logic and memory heat must cross thermal interfaces into a heat spreader, cold plate, air path, or liquid path.
- Mechanical expansion, stack height, die thickness, underfill or mold, and warpage affect assembly and reliability.
HBM puts memory near compute electrically, but also thermally and mechanically. That coupling is part of the value and part of the constraint.
Test, repair, and yield decide whether the stack is usable
A stacked package multiplies dependencies. Each memory die must work well enough. Vertical connections must work. Bonds must work. The base die must work. The accelerator must work. The package must route and power the assembly. The complete unit must pass test and reliability screens.
A naive intuition is:
naive_stack_yield =
product(individual_die_yield) * assembly_yield
[TOUCHDOWN DERIVATION] That is not a vendor yield model. It simply shows why a multi-die assembly makes known-good-die screening, redundancy, repair, process correlation, and assembly control valuable.
Known-good-die testing tries to avoid stacking obvious failures. Built-in self-test can exercise internal paths. Error-correcting codes detect or correct some data errors. Redundant rows, columns, lanes, or other resources can replace defective structures at a design-specific granularity. Package test and burn-in or reliability screens can catch failures that wafer probing did not expose.
Repair is not free capacity. It consumes redundant resources, logic, fuses or state, test time, routing, validation, and diagnostic coverage. A repair scheme that fixes an array defect may not fix a TSV, bond, base-die, or package fault. Field RAS also asks whether errors are detected, isolated, logged, corrected, and recovered without corrupting the workload.
That is why more HBM supply is not only a wafer-capacity problem. It depends on qualified DRAM wafers, TSV and thinning steps, bonding, base dies, interposers or package fabrics, substrates, assembly capacity, test equipment, controller IP, firmware, cooling, and complete-system yield.
What this means by role. An investor should see a multi-stage supply chain, not one commodity number. A CFO pays for usable packaged capacity and spare/reliability policy, not gross wafer bits. A CTO cannot choose HBM independently from accelerator, package, controller, runtime, and workload. A memory or package engineer should reject any comparison that does not name the die, stack, package, and test boundary.
How does software turn peak HBM bandwidth into useful bandwidth?
In plain English. Peak bandwidth is the interface's advertised ceiling. Useful bandwidth is the part that delivers the right bytes to the right operation in time to help an accepted task. Layout, batching, tiling, caching, fusion, address patterns, controller scheduling, and heat can leave part of the advertised path unused.
The memory wall is the combined limit created by capacity, physical bandwidth, useful bandwidth, latency and queueing, movement energy, activation and refresh work, controller behavior, package wiring, power delivery, cooling, yield, repair, supply, and delivered cost. HBM attacks an important part of that wall by putting a wide DRAM interface close to accelerator compute. It does not remove every term. A larger HBM stack can relieve capacity while package yield becomes harder. A wider interface can raise peak bandwidth while a poor kernel still rereads the same bytes. A faster GPU can finish arithmetic sooner while the CPU tool loop, collective, network, or storage restore becomes the next delay.
That is the thought process used throughout this article:
name the accepted task
-> name the state object and its deadline
-> identify which term of the memory wall blocks it
-> choose the smallest software, memory, fabric, package, or system change
-> measure where the bottleneck moved
-> accept or reject the change using the same task
Keep this traffic ladder intact:
logical tensor bytes requested by the program
-> bytes allocated and resident in a memory tier
-> bytes served by cache or reaching the HBM controller
-> bytes carried across a fabric when the object moves
-> bytes that contribute to an output the verifier accepts
Each arrow can increase, decrease, or bypass bytes. A tensor can be padded in allocation, reread from HBM, served from cache, fused away, compressed in transit, retried, or computed for an output that is later rejected. That is why one byte count cannot stand in for the whole path.
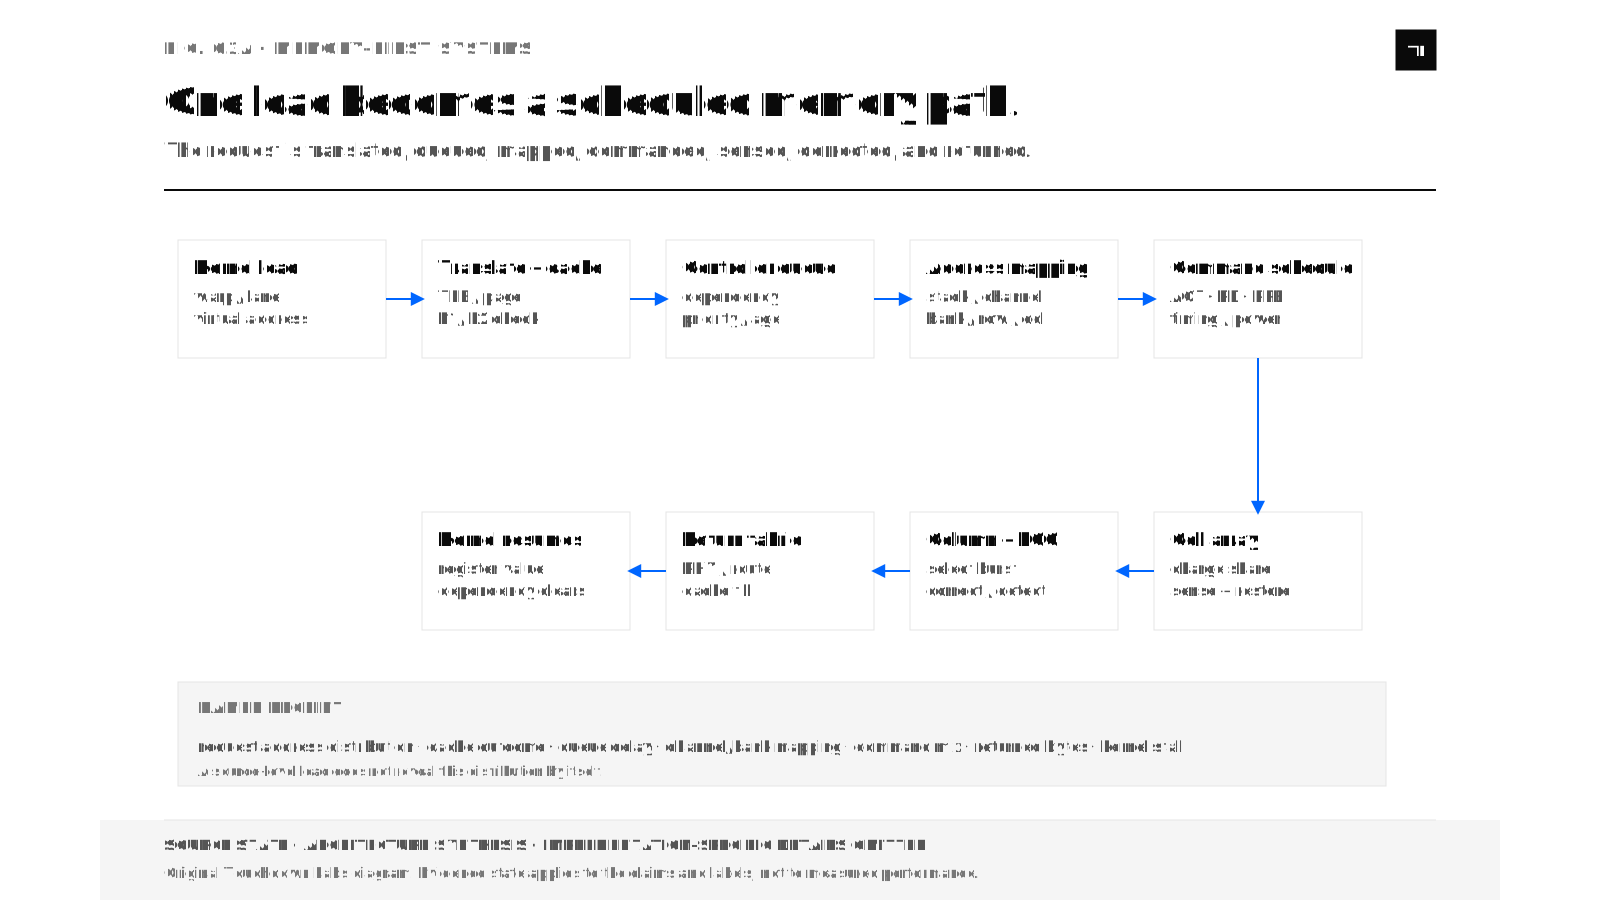
The software engineer usually sees an allocation and an address. The hardware sees requests, queues, cache lines, page translations, channels, banks, row state, commands, errors, and returned data.
That translation is where headline bandwidth becomes useful bandwidth or disappears into avoidable traffic and stalls.
The NVIDIA CUDA Programming Guide and CUDA Best Practices Guide are the primary public references for device/global memory, transactions, alignment, coalescing, and the programmed GPU memory hierarchy used here. PyTorch CUDA semantics supplies the allocation-versus-caching-allocator-reservation boundary. [OFFICIAL DOCUMENTATION]
From a tensor allocation to an HBM command
Consider a tensor created by PyTorch on a CUDA device. The exact implementation changes by framework and runtime, but the functional path is:
- The framework requests memory for a shape and dtype.
- The allocator may reuse a pooled region, round the request, split a block, or reserve a larger segment.
- The runtime maps device virtual addresses to physical memory resources.
- A kernel launches threads that issue loads and stores through the GPU memory hierarchy.
- Address translation and caches determine whether a request needs HBM.
- Threads' accesses are coalesced or split into memory transactions according to layout, alignment, and hardware rules.
- The memory controller maps transactions to HBM channels, pseudo-channels, banks, rows, and columns.
- The controller schedules demand reads, writes, refresh, turnarounds, and fairness under timing and power constraints.
- Returned data enters a cache, register, shared-memory tile, tensor operation, DMA path, or communication buffer.
CUDA global memory is a programming and address-space concept. On a GPU with HBM, much of the device-memory backing is physically HBM. Those terms are related, not interchangeable. A global-memory load can hit in cache and never reach HBM. A DMA or peer transfer can create HBM traffic without looking like an ordinary scalar load in source code.
The allocator adds another distinction. A tensor's logical bytes equal the product of its shape and element size. Resident bytes can be larger because of alignment, block rounding, fragmentation, caching, replication, workspace reservation, or padding. Reserved memory is not necessarily active traffic. Allocated memory is not necessarily useful data.
Why peak bandwidth stays on the box
Peak bandwidth assumes a favorable interface pattern. Real kernels lose utilization for several different reasons:
- Requests are too small, scattered, misaligned, strided, serialized, or dependent.
- Too few warps or independent requests exist to hide service latency.
- Address mapping concentrates traffic on too few channels or banks.
- Row conflicts require additional activate and precharge work.
- Read/write direction changes, refresh, timing constraints, or controller policy consume cycles.
- Cache or TLB misses create extra work.
- Temporary tensors are written to HBM and read again because operations were not fused.
- A poor tile rereads weights or activations that could have remained on chip.
- A collective, CPU stage, kernel launch, synchronization, or another GPU is actually the bottleneck.
- Thermal or power management reduces sustained clocks or interface behavior.
A memory copy can report high sustained bandwidth and still say little about a sparse gather. A dense GEMM can have high arithmetic intensity and still wait on communication. An HBM counter can look busy while the user receives a rejected output.
The roofline model remains useful when the boundary is named:
arithmetic_intensity = useful_operations / bytes_moved_at_named_boundary
bandwidth_ceiling =
sustained_bandwidth_at_same_boundary * arithmetic_intensity
The denominator can be HBM bytes, L2 bytes, on-chip scratchpad bytes, PCIe bytes, NVLink bytes, or network bytes. Changing the boundary changes the value. A credible roofline plot states the counter, operation definition, dtype, shape, system, and time interval.
Locality, coalescing, tiling, and fusion
Locality means that data used now is likely to be used again nearby in time or address. Caches exploit it. Tiling changes an operation so a small working set remains in registers or shared memory while many arithmetic operations reuse it. Coalescing combines neighboring thread accesses into fewer efficient transactions. Fusion keeps an intermediate inside a kernel rather than writing it to HBM and launching another kernel to read it.
These are not just software tricks. They change physical demand.
If three separate kernels write and read an approximately 320 MiB intermediate, fusion can avoid some external traffic. If a sparse-attention index causes uncoalesced gathers, fewer logical elements may still create inefficient transactions. If a KV allocator rounds small sequences to large blocks, unused capacity can lower concurrency even before any bytes move.
The cheapest byte is often the byte that does not cross a boundary. That can happen through reuse, aliasing, zero-copy handoff, fusion, compression, quantization, or recomputation. Every mechanism has a cost: extra compute, precision risk, implementation complexity, larger on-chip state, or a stricter schedule.
Movement APIs and what profilers can see
Pinned host memory can support efficient DMA because pages stay resident and can be addressed predictably by the transfer machinery. Page migration can move backing between host and device under a managed-memory policy. Peer access can move or access data across accelerators through supported fabrics. NIXL and similar software can orchestrate movement across heterogeneous memory and storage paths.
Those mechanisms do not collapse all tiers into one latency. The route can include cache coherence, page faults, DMA setup, PCIe or a proprietary accelerator fabric, switches, NUMA placement, CPU memory controllers, CXL devices, storage controllers, and filesystems.
Profilers also have boundaries:
- An allocation trace shows logical or reserved memory but not DRAM row commands.
- HBM throughput counters show activity at a hardware boundary but not whether bytes were useful.
- A kernel timeline shows duration and overlap but not automatically the customer acceptance result.
- CPU offload counters prove movement to host memory, not CXL, LMCache, or disk unless the specific path is instrumented.
- A cache-hit metric needs a defined key, block, version, and correctness rule.
This small calculator makes the distinction explicit:
# [TOUCHDOWN DERIVATION] No hardware result is embedded.
def bandwidth_receipt(
transfer_rate_per_second,
interface_width_bits,
elapsed_seconds,
useful_bytes,
measured_interface_bytes=None,
):
peak_bytes_per_second = (
transfer_rate_per_second * interface_width_bits / 8
)
useful_bytes_per_second = useful_bytes / elapsed_seconds
out = {
"peak_bytes_per_second": peak_bytes_per_second,
"useful_bytes_per_second": useful_bytes_per_second,
"useful_over_peak": useful_bytes_per_second / peak_bytes_per_second,
}
if measured_interface_bytes is not None:
achieved = measured_interface_bytes / elapsed_seconds
out["measured_interface_bytes_per_second"] = achieved
out["measured_over_peak"] = achieved / peak_bytes_per_second
out["useful_over_measured"] = useful_bytes / measured_interface_bytes
return out
The function contains no default rate, width, bytes, or time. A real receipt supplies them from a named device, direction, counter, kernel interval, and workload.
For the broader path from profiler evidence through compiler and kernel changes to useful GPU capacity, see Touchdown's Automated CUDA, Revenue per GPU, and Capability per GPU. That article supplies the optimization loop; this article supplies the memory-specific physical boundary.
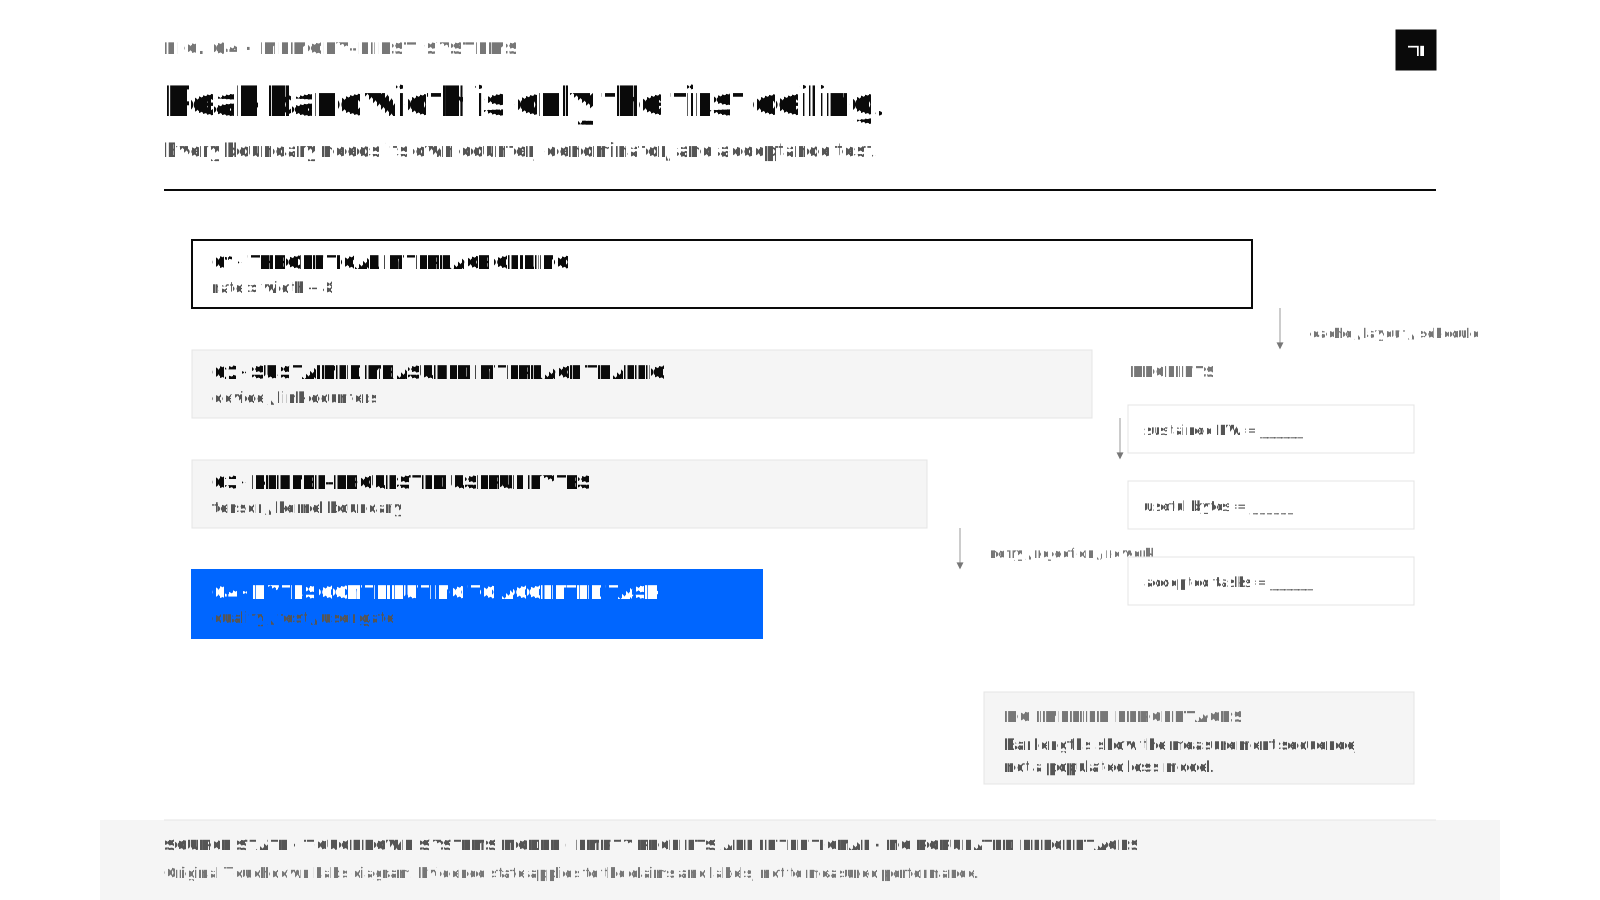
What this means by role. The CEO should not expect a higher box number to guarantee more output. The CFO should compare sustained accepted-task throughput and reliability. The software engineer controls layout, tiling, reuse, allocation, batching, and movement policy. The kernel engineer measures traffic at named boundaries. The controller engineer sees address distribution and scheduling pressure that source code alone cannot reveal.
What memory path does Wan2.2 video diffusion create?
In plain English. Video diffusion begins with noise and repeatedly edits a compressed video representation until it matches the prompt closely enough to decode. That compressed representation is called a latent. The model rereads weights and creates large temporary tensors during many denoising steps, so its memory path is repeated, state-heavy, and different from a language model's growing KV cache.
Now the physical path needs a real workload.
Wan2.2 is useful because video diffusion creates large multi-dimensional state, repeated denoising, dense projections, attention, normalization, feed-forward work, classifier-free guidance, communication, and output decoding. It is not just one matrix multiplication, and it is not the same memory path as autoregressive text generation.
The source boundary matters. This walkthrough uses the official Wan-Video/Wan2.2 repository pinned to commit 42bf4cfaa384bc21833865abc2f9e6c0e67233dc. The configuration and code path are source-backed. The tensor arithmetic below is Touchdown-derived. It is not a hardware trace.
From prompt to a video someone accepts
For text-to-video generation, the functional path is:
text prompt and negative prompt
-> text encoder creates conditioning tensors
-> runtime creates an initial noisy latent
-> scheduler selects a sequence of timesteps
-> one of the high-noise or low-noise denoisers runs for the current region
-> transformer blocks perform self-attention, cross-attention,
normalization, feed-forward work, residual updates, and modulation
-> conditional and unconditional predictions are combined by guidance
-> scheduler updates the latent
-> repeat for the requested number of sampling steps
-> VAE decodes the final latent into video frames
-> product checks quality, format, latency, and safety
The A14B configuration does not use token-level top-k MoE routing in the usual language-model sense. It names separate high-noise and low-noise checkpoints and switches the model used across the timestep boundary. That distinction matters because memory planning can load, retain, or offload two full model states differently from a token-routed expert layer.
The pinned configuration includes:
# [OFFICIAL REPOSITORY SOURCE]
# Wan2.2 commit 42bf4cfaa384bc21833865abc2f9e6c0e67233dc
t2v_A14B.vae_stride = (4, 8, 8)
t2v_A14B.patch_size = (1, 2, 2)
t2v_A14B.dim = 5120
t2v_A14B.ffn_dim = 13824
t2v_A14B.num_heads = 40
t2v_A14B.num_layers = 40
t2v_A14B.sample_steps = 40
t2v_A14B.boundary = 0.875
This block proves configuration values at the pinned commit. It does not prove allocated memory, physical HBM traffic, or runtime.
One concrete tensor shape
Take an illustrative request of 81 frames at 832 by 480 pixels. These dimensions are chosen because they are compatible with the pinned temporal and spatial strides. The generation code constructs a latent target shape using the VAE stride, then calculates the sequence length from the spatial patch.
The derived latent grid is:
temporal latent = (81 - 1) / 4 + 1 = 21
latent height = 480 / 8 = 60
latent width = 832 / 8 = 104
token grid = 21 * (60 / 2) * (104 / 2)
= 21 * 30 * 52
= 32,760 tokens
[TOUCHDOWN DERIVATION] That is a shape calculation from the pinned source, not an observed runtime tensor dump. A real distributed run may pad sequence length according to its sequence-parallel degree. The article therefore reports the unpadded logical grid and requires the runtime to report padding separately.
At model width 5,120, one BF16 activation of shape [32,760, 5,120] contains:
32,760 * 5,120 * 2 bytes
= 335,462,400 bytes
= 319.921875 MiB
approximately 320 MiB
LOGICAL TENSOR BYTES, NOT MEASURED HBM TRAFFIC. If Q, K, and V outputs at that logical shape were all fully materialized, their logical writes would total approximately 959.77 MiB for one block evaluation. Multiplying that value by 40 blocks, 40 default steps, and two classifier-free-guidance passes gives approximately 2,999.27 GiB, or 2.929 TiB, of shape-derived Q/K/V output bytes across a request.
That number is deliberately labeled an unfused logical boundary. It is not measured HBM traffic. It excludes reads, weights, feed-forward tensors, attention results, communication, VAE work, padding, allocator overhead, caching, and output. It can also overstate physical writes when fusion or kernel design keeps intermediates on chip. Its value is to show why materialization choices matter.
For a second production-shaped reference, use 81 frames at 1280 by 720. From the same VAE stride and patch size, the logical latent is 16 x 21 x 90 x 160, or 4,838,400 latent elements, and the transformer grid contains 75,600 visual tokens. One BF16 hidden-state tensor at width 5,120 is 774,144,000 logical bytes, about 738.28 MiB. This is again shape arithmetic, not peak allocation or measured HBM traffic.
The default 40-step loop performs one conditional and one unconditional DiT evaluation per step. That is 80 transformer forwards. With 40 blocks, the request crosses 3,200 block evaluations before the VAE decodes the final latent. Prompt expansion and the UMT5 text encoder are separate workload phases. The stock repository uses BF16 mixed precision for the model path while retaining selected numerically sensitive work in FP32. An FP8 or NVFP4 result therefore needs its own named artifact, kernel path, quality gate, and receipt.
This is also where LLM vocabulary can mislead. Wan2.2's per-block Q, K, and V are transient diffusion-attention intermediates. They are not an autoregressive LLM KV cache that grows once per generated token and can be restored for a later turn. Offloading DiT weights, moving a mutable latent, sharding attention state, and restoring a coding-agent prefix are four different movement problems.
What the attention code actually does
The official WanSelfAttention.forward path projects Q, K, and V, applies normalization to Q and K, reshapes by head, applies rotary position handling, calls a FlashAttention-style function, flattens the result, and runs an output projection:
# [OFFICIAL REPOSITORY SOURCE, SHORTENED]
def qkv_fn(x):
q = self.norm_q(self.q(x)).view(b, s, n, d)
k = self.norm_k(self.k(x)).view(b, s, n, d)
v = self.v(x).view(b, s, n, d)
return q, k, v
q, k, v = qkv_fn(x)
x = flash_attention(
q=rope_apply(q, grid_sizes, freqs),
k=rope_apply(k, grid_sizes, freqs),
v=v,
k_lens=seq_lens,
window_size=self.window_size)
x = self.o(x.flatten(2))
Source: wan/modules/model.py. Boilerplate is omitted. The excerpt is short enough to expose the operation boundary without copying the entire implementation.
For each block, ask three questions:
- What state is read or created? Input activations, projection weights, Q/K/V tensors, positional frequencies, sequence metadata, attention output, and output-projection weights.
- Which boundary is crossed? Depending on tiling and cache behavior: HBM to L2, L2 to on-chip storage and registers, on-chip accumulation, possible HBM materialization, and inter-GPU communication in a distributed layout.
- What receipt is missing? Kernel names, shapes, dtypes, HBM read/write counters, L2 traffic, duration, occupancy, synchronization, numerical parity, and clip-level acceptance.
The FlashAttention-style call is important. A naive attention explanation says attention creates an S by S matrix. A fused tiled implementation can avoid materializing that full score matrix in HBM. The algorithm still reads Q, K, and V and performs substantial work, but physical traffic differs from the naive graph.
The denoising loop shows another repeated path:
# [OFFICIAL REPOSITORY SOURCE, SHORTENED]
for _, t in enumerate(tqdm(timesteps)):
latent_model_input = latents
timestep = torch.stack([t])
model = self._prepare_model_for_timestep(t, boundary, offload_model)
sample_guide_scale = (
guide_scale[1] if t.item() >= boundary else guide_scale[0]
)
noise_pred_cond = model(latent_model_input, t=timestep, **arg_c)[0]
noise_pred_uncond = model(latent_model_input, t=timestep, **arg_null)[0]
noise_pred = noise_pred_uncond + sample_guide_scale * (
noise_pred_cond - noise_pred_uncond
)
temp_x0 = sample_scheduler.step(
noise_pred.unsqueeze(0), t, latents[0].unsqueeze(0),
return_dict=False, generator=seed_g)[0]
latents = [temp_x0.squeeze(0)]
Source: wan/text2video.py. The shortened excerpt preserves the decision and data dependencies while omitting scheduler setup and cleanup.
This loop proves that conditional and unconditional model evaluations feed a guidance combination and latent update at each timestep. It also proves that the implementation has a model-offload control path. It does not tell us whether offload was enabled in a given benchmark, how much state moved, or whether the transfer overlapped compute.
FSDP and Ulysses turn the video sequence into a fabric problem
The single-device path is only one execution shape. Wan2.2's official repository also documents an eight-GPU path that combines FSDP for the diffusion transformer and text encoder with DeepSpeed Ulysses sequence parallelism:
# [OFFICIAL REPOSITORY COMMAND SHAPE]
# Pin the repository, weights, image, prompt, runtime, and seed before replay.
torchrun --nproc_per_node=8 generate.py \
--task ti2v-5B \
--size 1280*704 \
--ckpt_dir ./Wan2.2-TI2V-5B \
--dit_fsdp \
--t5_fsdp \
--ulysses_size 8 \
--image examples/i2v_input.JPG \
--prompt "Summer beach vacation style, a white cat wearing sunglasses sits on a surfboard."
Source: Wan2.2 generation instructions. The command proves that the project exposes the distributed path. It does not prove that eight GPUs beat one GPU at the same resolution, frame count, denoising steps, dtype, quality gate, latency target, or cost.
DeepSpeed-Ulysses partitions the sequence dimension across workers. At the attention boundary, an all-to-all redistributes Q, K, and V so each worker can compute attention for a subset of heads over the full sequence. Another all-to-all returns the output to the sequence-partitioned layout. [OFFICIAL PROJECT DESIGN / PAPER] The mechanism is also described in the DeepSpeed-Ulysses paper.
local projection
-> Q/K/V all-to-all
-> local attention over assigned heads
-> output all-to-all
-> local output projection and feed-forward work
-> next transformer block
-> next denoising step
That repeated collective can matter because the video token sequence spans time, height, and width, and the cost recurs across transformer blocks and denoising steps. But a larger scale-up domain creates value only when the trace shows exposed collective wait on the critical path. The required receipt includes collective type, message bytes, rank map, topology, algorithm, overlap, p50/p95/p99 wait, DiT time, VAE time, peak allocated HBM, GPU-hours, retries, and accepted-clip rate.
The current A14B configuration has 40 attention heads. The official Ulysses implementation requires the sequence-parallel group size to divide the head count and, in the documented Wan path, match the participating world size. An unmodified 144-way Ulysses group on a Kyber NVL144 rack is therefore not a valid configuration. A future rack could host multiple bounded groups or combine other parallel dimensions, but that is an experiment to design, not a performance claim.
The product metric also continues after denoising. VAE decode, safety and format checks, quality rejection, and retries consume time and energy. The financial denominator is an accepted clip. A faster 40-step kernel path can still lose if quality forces more retries or if VAE and output handling dominate the job.
[NOT FOUND] No public Wan2.2-on-Kyber benchmark was verified as of July 10, 2026. NVIDIA platform bandwidth and topology specifications cannot be converted into a Wan2.2 latency, quality, energy, or cost result without a controlled replay.
The state-lifetime map
| State | Access shape | Mutability | Reuse horizon | First placement question |
|---|---|---|---|---|
| High/low-noise weights | Repeated layer-ordered reads | Read-only in inference | Across relevant denoising steps | Keep resident, switch/offload by region, shard, or stream predictable groups? |
| Text conditioning | Reused cross-attention input | Read-only | Request lifetime | Replicate, cache, or recompute? |
| Latent | Dense iterative update | Read-write | Every step | Keep in hot writable memory by default |
| Q/K/V and FFN intermediates | Dense or tile-local | Ephemeral | Inside block/kernel | Fuse, tile, spill, or rematerialize? |
| Positional and sparse metadata | Read-mostly indexes/frequencies | Mostly read-only | Blocks or steps | Can gathers use memory efficiently? |
| Communication buffers | Collective-dependent | Read-write | Per block or step | Does sharding reduce compute but add movement stalls? |
| Decoded frames | Sequential output | Write-mostly then read | End of request | Move to host/storage without blocking the next request? |
The table explains why one memory technology does not own the workload. Mutable latents and active intermediates need low-latency writable service. Read-only weights may offer prefetch or streaming opportunities if access order is predictable. Decoded frames can leave HBM. Sparse metadata can be small but latency-sensitive. Communication buffers couple memory placement to the accelerator fabric.
What the public optimization records do and do not prove
[VENDOR TARGET / BENCHMARK] Baseten's January 2026 article reports median Wan2.2 results for its named stack, with 40 sampling steps, 1280 by 720 output, and 81 frames. It reports 2.6 times speedup on H100 and 3.2 times on B200 relative to its stated reference. The article discusses GEMM, RoPE, LayerNorm, RMSNorm, communication overlap, and disabling CPU model offload. Those are workload-specific vendor results, not proof that one memory technology wins.
[AUTHOR WORKLOG] Ali's later public engineering record reports a broader composite improvement that includes reducing denoising steps, trained sparse attention, kernel work, fusion, scheduling, and NVFP4. The reported 54 times is an end-to-end composite claim, not Baseten's official result and not one kernel speedup. The worklog separately reports a VSA kernel change from 7.444 ms to 4.719 ms, about 1.58 times by arithmetic. Touchdown has not independently reproduced those numbers in this article.
[ACCEPTED PAPER, AUTHOR-REPORTED MEASUREMENTS] The Visual Sparse Attention paper, accepted by NeurIPS 2025 according to its current arXiv record, and the public FastVideo code provide a separate research boundary. Sparsity can reduce attention work, but indexes, gather patterns, load balance, communication, and quality tests become part of the system. Fewer selected tokens do not automatically mean proportional HBM or end-to-end savings.
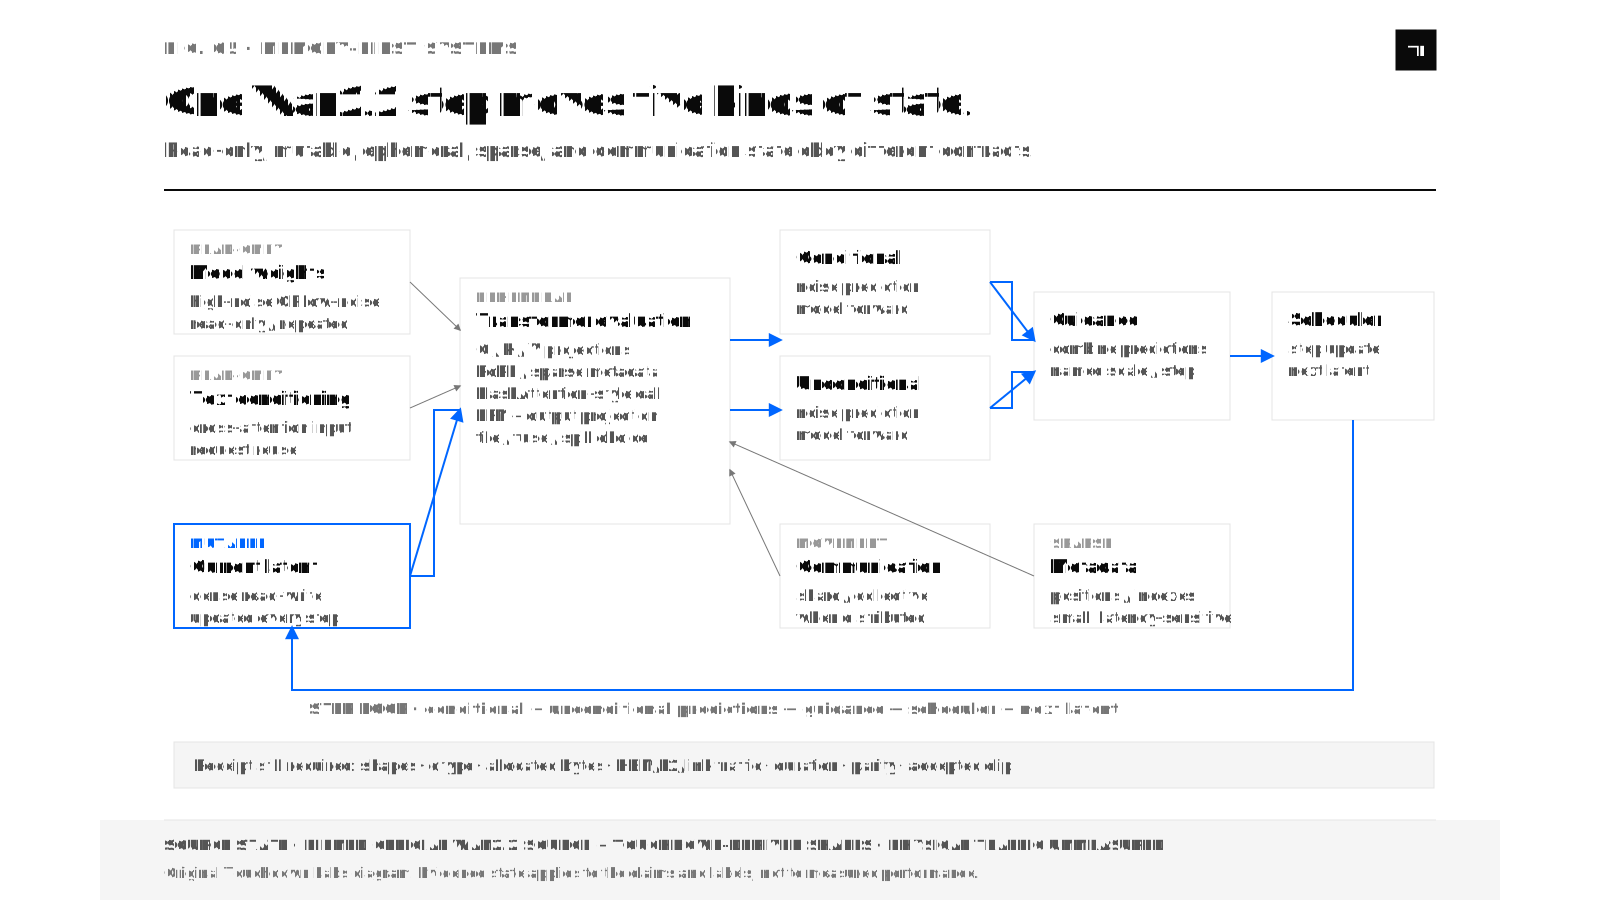
What this means by role. The product owner cares about an accepted clip. The CFO cares about GPU-seconds, retries, and concurrency. The software engineer needs allocated bytes and offload events. The kernel engineer needs HBM/L2/link traffic and quality parity. The hardware engineer needs the actual access distribution, not the phrase video is memory-bound.
What memory path does a coding agent create?
In plain English. A coding agent alternates between GPU model work and CPU-side tools. The model reads instructions and repository context, generates a proposed action, calls search, edit, test, or compilation tools, receives new evidence, and continues. Reusable prefixes and KV cache can avoid repeated model work, but tool delays, cache misses, retries, and failed patches can still dominate the cost of the accepted change.
A coding agent uses many of the same physical memories, but it creates a different state graph.
Its model still reads weights. Its transformer still performs prefill and decode. Its KV cache still occupies device memory. But the request repeatedly leaves the accelerator to search files, read code, edit text, run a compiler, execute tests, inspect failures, and return new context. The workflow branches. A tool result can invalidate a plan. A failed patch can trigger another prefill and decode cycle.
The accepted output is not a plausible paragraph. It is a correct, reviewable change with passing evidence.
From user request to accepted patch
user request
-> system instructions and tool schemas
-> repository map, selected files, prior turns, and current diff
-> model prefill
-> active KV cache
-> token-by-token decode
-> tool call
-> CPU-side search, file I/O, edit, test, or lint
-> tool result appended to context
-> reused prefix or another prefill
-> more decode
-> candidate patch
-> test and review gate
-> accepted change or retry
There are three distinct kinds of state.
Model state includes weights and runtime workspaces shared across requests. Inference state includes active KV, reusable prefix KV, scheduler metadata, logits/sampling state, and communication buffers. Workflow state includes files, repository indexes, tool results, patch attempts, logs, tests, user preferences, and durable receipts.
On an HBM accelerator, model weights, active KV, and hot runtime buffers commonly occupy HBM. That does not mean HBM should hold every repository file or old test log. CPU DRAM, optional CXL-attached capacity, NVMe, and object storage can hold larger or more durable state. They help only when software knows what to retrieve, when it will be reused, and how long movement takes.
KV cache, one term at a time
The KV cache is the language model's working notebook for tokens it has already read. Without it, the model would have to recompute the same attention history before producing each next token. The notebook grows as generation continues, and every concurrent request needs its own correctly identified state. The formula below explains the logical size of that notebook before allocator padding, paging, replication, fragmentation, and runtime overhead.
During autoregressive inference, each transformer layer produces key and value vectors for prior tokens. Retaining them lets a new token attend to prior context without recomputing the full prefix at every decode step.
For a conventional attention layout, a useful logical-size formula is:
logical_KV_bytes =
2
* layers
* kv_heads
* head_dim
* bytes_per_element
* sum(tokens_i for each live sequence i)
equal-length special case =
2
* layers
* tokens_per_sequence
* kv_heads
* head_dim
* bytes_per_element
* concurrent_sequences
One bounded public coding-model example
Use the official Qwen/Qwen2.5-Coder-32B-Instruct configuration pinned to revision 381fc969f78efac66bc87ff7ddeadb7e73c218a7. [OFFICIAL MODEL CONFIGURATION] It declares 64 hidden layers, 40 attention heads, 8 key/value heads, hidden width 5,120, BF16 dtype, and 32,768 maximum position embeddings. The head dimension is derived as 5,120 / 40 = 128.
For one illustrative 32,768-token coding-agent context, split as 24,576 stable system/repository-prefix tokens plus 8,192 current-turn and tool-result tokens, the logical BF16 KV size is:
2 for K and V
* 64 layers
* 32,768 tokens
* 8 KV heads
* 128 values per head
* 2 bytes per BF16 value
= 8,589,934,592 bytes
= 8 GiB per sequence
8 equal-length concurrent sequences
= 64 GiB of logical KV
[TOUCHDOWN DERIVATION] The token split and concurrency are an explicit experiment contract, not claims about typical Qwen usage. Eight GiB and 64 GiB are logical tensor capacities. A real serving receipt still needs a pinned engine and connector version, cache dtype, block size, allocation and fragmentation, sharding or replication, prefix sharing, device and lower-tier residency, transfer bytes, restore p50/p95/p99, prefill avoided, accepted patch, and failed-test or retry record.
The movement hypothesis is now concrete: the 24,576-token stable prefix might be worth preserving below HBM between turns if version-correct lookup and restore beat recomputing that prefix under the p99 budget. The active 8,192-token suffix remains the hotter mutable or append-only region. That is a hypothesis the receipt can reject.
The leading 2 is key plus value. kv_heads is not always the query-head count. Grouped-query attention and multi-query attention share K/V across more query heads, reducing KV state. head_dim and dtype come from the named model configuration.
Logical bytes are not resident allocator bytes. Paged KV systems divide state into blocks. The final block can be partly empty. Allocation can round, fragment, replicate, or attach metadata. Tensor or pipeline parallelism changes where blocks live. Prefix sharing can let multiple requests reference one physical block set. Quantization can reduce element size but adds compatibility and quality questions.
A complete KV receipt therefore reports:
logical bytes
allocated blocks and bytes
used tokens per block
fragmentation and metadata
replication / sharding
shared-prefix references
evictions
device-to-host and host-to-device bytes
hit rate with key/version semantics
restore p50/p95/p99
prefill avoided
accepted task result
Touchdown's KV Cache Is Becoming the Memory Hierarchy of Inference follows one repeated agent workflow through KV placement in more operational detail. The current section adds the cell, package, alternative-tier, and hardware-admission path.
This schema shows what an agent trace should capture:
# [PROPOSED] Touchdown illustration, not framework source.
StateObject(
name="repo_prefix_kv",
bytes=measured_allocated_bytes,
access="read_mostly",
reuse_distance_ms=observed_reuse_distribution,
deadline_ms=restore_p99_budget,
mutable=False,
recompute_ms=measured_prefill_time,
correctness="exact",
current_tier="gpu_hbm",
)
The crucial comparison is not HBM versus CPU memory in the abstract. It is measured restore plus miss cost versus measured prefill recomputation under the actual concurrency and p99 budget.
A real documented offload path
[OFFICIAL VENDOR DOCUMENTATION] NVIDIA Dynamo's KVBM guide, current v1.2.1 when reviewed, documents a write-through hierarchy and configuration for GPU, pinned CPU memory, and disk. The guide includes this cache-tier example:
# Official documentation example, not Touchdown defaults or a benchmark.
export DYN_KVBM_CPU_CACHE_GB=4
export DYN_KVBM_DISK_CACHE_GB=8
It also documents the vLLM connector shape:
vllm serve \
--kv-transfer-config \
'{"kv_connector":"DynamoConnector","kv_role":"kv_both","kv_connector_module_path":"kvbm.vllm_integration.connector"}' \
MODEL_ID
The placeholder MODEL_ID replaces the documentation's example model because this article is not prescribing a benchmark. The option names and connector path come from the current guide.
The vendor guide carries an important warning: capacities should increase down the write-through tiers. If the CPU cache is smaller than the device KV allocation, the system can churn by offloading after forward passes without creating useful retained capacity. The guide also says that insufficient prefix hits can eliminate time-to-first-token benefit or create degradation.
That is exactly the point of the state-first method. A lower tier is not valuable because it exists. It is valuable when retained state is reused enough to avoid more work than movement costs.
This source proves a documented software path. It does not prove that the path helps this coding-agent workload. It does not prove CXL, because CPU memory can be ordinary host DRAM. It does not prove LMCache, because a different connector can own that path. It does not prove disk is healthy for active KV, because SSD latency, endurance, filesystem, reuse, and tail behavior still need measurement.
One open coding-agent loop, followed into memory
Hermes Agent is a useful public code example because its run_agent.py exposes the tool-calling loop instead of hiding it behind a hosted product. [OFFICIAL PROJECT SOURCE, REVIEWED 2026-07-10] The repository describes automatic tool calling, conversation history, error recovery, tool-result handling, and repeated model calls. That lets us trace the mechanism without claiming that every coding agent uses the same implementation.
The physical and software path is:
- The client assembles system instructions, tool schemas, prior messages, repository context, and the current request in host memory.
- The serving engine tokenizes that context and schedules a prefill. Model weights and the hot working set are read through accelerator HBM.
- Each transformer layer writes K and V tensors for the prompt into paged device allocations. Those allocations are logical model state represented by physical HBM pages, allocator metadata, and engine block tables.
- Decode reads weights and prior KV, produces a token, and repeats. When the model emits a tool call, generation pauses at the application boundary.
- Hermes executes the search, file read, patch, compiler, test, or lint operation on the CPU and storage path. The GPU may serve another request or wait, depending on scheduling and concurrency.
- The tool result is appended to conversation state. If the unchanged prefix is recognized under the same model, tokenizer, prompt-template, repository revision, and cache-key contract, reusable KV can avoid part of another prefill. If any identity field changes, the safe outcome is a miss.
- The loop continues until the agent returns a candidate patch. Tests, review, and acceptance determine whether the occupied compute, memory, and tool time produced useful work.
The word cache hides several different mechanisms. A provider prompt cache can reduce billed or processed input. An engine prefix cache can share device KV blocks. LMCache or HiCache can retain KV below the device tier. A repository index can cache file retrieval. A tool-result cache can avoid another external action. None proves another, and each needs its own key, version, hit, latency, and correctness receipt.
One enterprise task across Claude Code, Codex, and self-hosted GLM-5.2
Here is the CEO and CTO example this article needs.
An engineer asks an agent to update an authentication dependency across a private repository, follow the company's internal security standard, migrate every affected call site, run the named tests, and return a reviewable patch with citations to the policy it followed.
That one sentence creates this path:
private repository and security documents
-> parse, version, permission, chunk, embed, and index
-> authenticate the engineer and retrieve permitted code and policy spans
-> rerank, deduplicate, and assemble the prompt
-> prefill the model and create active inference state
-> decode a search, read, edit, or test tool call
-> run CPU, filesystem, network, compiler, and sandbox work
-> append the tool result
-> reuse a valid prefix, restore KV, recompute prefill, or compact
-> repeat until a candidate patch exists
-> run tests, policy checks, citation checks, and human or CI review
-> accept the patch or pay for another attempt
The repository and security corpus normally live in object storage, databases, text indexes, vector indexes, CPU DRAM, and SSD. They do not all move into HBM. Retrieval selects a smaller set of spans. Those spans become prompt tokens. Prefill transforms the prompt into model state. Active KV or another architecture-specific cache then competes with model weights, workspaces, communication buffers, and concurrent requests for accelerator memory.
Microsoft's production RAG guidance describes query translation, parallel query execution, hybrid retrieval, reranking, and prompt assembly as separate operations. Its hybrid-search documentation combines text and vector search. [OFFICIAL PLATFORM DOCUMENTATION] These sources establish the retrieval path, not a Touchdown latency result.
Adding more chunks can improve recall and still make the product worse. More retrieved tokens increase prefill work, active cache state, time to first token, and possibly provider charges. Bad retrieval can therefore cost twice: first as wasted inference, then as a rejected patch.
The same task can enter three different agent paths:
| Path | What the public source exposes | What the company can measure | What remains unknown |
|---|---|---|---|
| Claude Code | Repository tools, CLAUDE.md, skills, MCP, hooks, subagents, context loading, and compaction behavior |
Input and output usage where exposed, tool calls, tool duration, wall time, retries, tests, accepted patch, provider bill | Exact serving GPU, weight precision, KV precision, HBM bytes, offload tier, NVLink topology, and per-task energy unless Anthropic discloses them |
| OpenAI Codex | Repository instructions, local tools, file changes, tests, thread events, and context-compaction events | Tool and terminal evidence, wall time, retries, accepted patch, usage or cost fields exposed by the selected product | Exact serving GPU, precision, KV geometry, offload tier, fabric, and HBM traffic unless OpenAI discloses them |
| Hermes or OpenClaw with self-hosted GLM-5.2 | Open harness loop plus a separately operated model endpoint | All application fields plus engine, model revision, hardware, topology, weight precision, KV precision, cache policy, profiler counters, and power telemetry | Nothing becomes measured automatically. The team still has to instrument and replay it. |
Claude Code's extension documentation says CLAUDE.md loads in full at session start, tool schemas can be deferred, skills load on demand, and subagents receive isolated context. Codex's app-server protocol exposes thread, turn, item, and contextCompaction events. OpenClaw's memory documentation separates injected long-term memory from indexed daily records and flushes durable state before compaction. [OFFICIAL PRODUCT OR PROJECT DOCUMENTATION] These are context-management facts. They do not reveal provider HBM behavior.
That separation is the first executive lesson: hosted coding tools expose the business task and client-visible state, while the provider owns the lower inference stack. Self-hosting exposes more control and more operational responsibility.
GLM-5.2 makes the precision and memory decision concrete
GLM-5.2 is useful as the self-hosted control case because official artifacts expose the model architecture and current serving commands.
Z.ai's official repository lists GLM-5.2 as a 744-billion-parameter, 40-billion-active-parameter MoE and publishes BF16 and FP8 artifacts. The current FP8 configuration declares 78 hidden layers, 256 routed experts, eight selected experts per token, a 1,048,576-token configured maximum, FP8 E4M3 block quantization for the checkpoint, and architecture-specific low-rank KV fields. OFFICIAL Z.AI REPOSITORY AND MODEL CONFIGURATION
NVIDIA separately publishes nvidia/GLM-5.2-NVFP4. Its model card calls the artifact 753 billion total parameters and 40 billion activated, targets Blackwell, and documents SGLang and vLLM paths. It says linear operators inside MoE experts use NVFP4 while the shared expert remains unquantized. [OFFICIAL NVIDIA MODEL CARD] The 744B and 753B totals belong to different official artifact descriptions. This article preserves that discrepancy instead of silently choosing one number.
The first-order weight-capacity floor for the 744B Z.ai artifact is:
ideal packed bytes = parameter count * bits per stored parameter / 8
BF16: 744B * 16 / 8 = 1.488 TB decimal
FP8: 744B * 8 / 8 = 0.744 TB decimal
4-bit ideal floor: 744B * 4 / 8 = 0.372 TB decimal
[TOUCHDOWN DERIVATION] These are arithmetic floors, not checkpoint sizes or runtime allocations. Quantization scales, unquantized modules, padding, duplicate tensors, expert placement, CUDA graphs, KV state, communication buffers, and allocator headroom all consume additional memory. Forty billion active parameters per token does not mean only forty billion parameters need to be resident. The runtime still has to place or fetch the experts that future tokens may select.
The precision decision is also not one switch:
| Field | BF16 baseline | FP8 artifact | NVIDIA NVFP4 artifact |
|---|---|---|---|
| Weight storage | Larger | Smaller, with FP8-specific scales and kernels | Smaller for the quantized MoE linear operators, not every module |
| Activation/accumulation | Runtime-specific mixed precision | Not implied solely by the weight filename | NVIDIA card states weight and activation quantization for selected operators; accumulation remains operator-specific |
| KV-cache dtype | Separate engine decision | Not automatically FP8 | NVIDIA's vLLM command explicitly requests fp8_e4m3 KV; that command is artifact-specific |
| Hardware path | Broad, but expensive at this size | Runtime and accelerator support required | NVIDIA card lists Blackwell compatibility |
| Quality evidence | Base artifact and workload eval required | Compare on the same agent harness | NVIDIA publishes selected benchmark comparisons against its FP8 baseline; customer patch acceptance still requires replay |
The official NVIDIA vLLM command shape is:
# [OFFICIAL NVIDIA MODEL-CARD COMMAND, VERSION-SENSITIVE]
vllm serve nvidia/GLM-5.2-NVFP4 \
--tensor-parallel-size 8 \
--enable-expert-parallel \
--trust-remote-code \
--reasoning-parser glm45 \
--tool-call-parser glm47 \
--enable-auto-tool-choice \
--kv-cache-dtype fp8_e4m3 \
--host 0.0.0.0 --port 8000
This proves that NVIDIA documents one Blackwell, vLLM, NVFP4, FP8-KV, TP8, expert-parallel serving shape. It does not prove a specific GPU count beyond the command's tensor-parallel requirement, a context length, concurrency, tokens per second, cache hit rate, accepted-patch rate, or cost.
[NOT FOUND] No public GLM-5.2-on-H200, GLM-5.2-on-B200, GLM-5.2-on-GB200, or GLM-5.2-on-Kyber serving row with context length, concurrency, tokens per second per user, tokens per second per GPU, accepted-patch rate, and cost was verified for this article as of July 11, 2026. Public GLM-5 benchmark rows are a different model version and must not be relabeled GLM-5.2.
That missing row is why the paid implementation starts from a run receipt, not a marketing comparison. Every run needs:
task and repository revision
harness and version
model and artifact revision
hosted or self-hosted boundary
engine, image, hardware, and topology when self-hosted
weight, activation, accumulation, and KV precision
input, retrieved, tool-schema, tool-result, cached-prefix, and output tokens
context window requested and actually admitted
queue, prefill, decode, KV restore, tool, test, and wall time
cache hit, bytes moved, eviction, miss, and recompute
tool calls, failed calls, retries, compactions, and test result
accepted patch, review result, cost, and measured energy when available
Tokens per second answers only one line. A coding agent that decodes twice as fast but spends most of its wall time compiling, retries more often, or produces fewer accepted patches can have worse economics.
The same enterprise task makes prefix reuse visible
Use an explicit context sweep instead of pretending every enterprise agent fills one million tokens:
| Run | Stable policy and repository prefix | Retrieved task-specific spans | Prior tool results | New tool result | Question answered |
|---|---|---|---|---|---|
| A | 30,000 tokens | 5,000 | 2,000 | 0 | Baseline prefill and first tool call |
| B | same 30,000 | same 5,000 | 2,000 | 4,000 | Does exact-prefix reuse avoid rebuilding A? |
| C | same 30,000 | same 5,000 | 6,000 | 4,000 | Does another appended result preserve the earlier prefix? |
| D | policy or repository revision changed | retrieval rerun | prior history | 4,000 | Does invalidation correctly force a miss? |
[ILLUSTRATIVE EXPERIMENT CONTRACT] These token counts are not production averages. They define a reproducible sweep. The important test is semantic validity: model revision, tokenizer, chat template, system policy, tool schema, tenant, repository commit, document ACL, and prefix hash must match before reuse.
For a conventional transformer, logical KV can be estimated from layers, KV heads, head dimension, tokens, dtype, and concurrency. Do not blindly apply that formula to GLM-5.2. Its sparse-attention and low-rank KV configuration changes the cached representation. The receipt must use the exact SGLang or vLLM cache geometry and measured allocation.
The break-even condition remains simple:
prefix or offload path wins when
lookup + transfer + restore + miss risk
<
recomputed prefill under the required p99
This is also where privacy becomes a memory-system property. KV is derived from private code, retrieved policy, tool output, and prior reasoning. Tenant isolation, ACL-aware cache keys, deletion, invalidation, encryption, TTL, and audit logs belong in the cache design. A fast cross-tenant hit is a security failure.
Where Kyber could matter, and where the example stops
GLM-5.2 is a large MoE. Expert parallelism can create token dispatch, combine, and all-to-all traffic. A larger fast scale-up domain could change expert placement and reduce how often that traffic crosses a slower scale-out boundary.
That is the legitimate Kyber thought experiment:
larger model and more experts
-> more pressure on weight placement and expert communication
-> larger fast-connected domain may keep more traffic inside scale-up fabric
-> runtime can test wider expert parallelism and different replica shapes
-> accepted-task replay decides whether the added domain helps
Kyber is NVIDIA's preliminary 144-GPU MGX NVL rack design for Rubin Ultra, not a current GLM-5.2 benchmark result. Exact Rubin Ultra Kyber HBM capacity, bandwidth, application topology, tokens per second, power, schedule, and accepted-agent economics remain not_public in the reviewed primary material.
There is a similar constraint on Wan2.2. Its current A14B reference uses 40 attention heads, and the official Ulysses path requires the group size to divide the head count. An unmodified 144-way Ulysses group is therefore not a valid conclusion. A future Kyber rack might run multiple bounded video groups or a different mixture of parallelism, but the stock repository does not prove it.
What this means by role. The CEO should compare accepted patches and accepted clips, not raw model calls. The CFO should count retrieval, provider or GPU cost, tool sandboxes, retries, review, energy, and failed outputs. The CTO should separate the hosted control boundary from the self-hosted engine, cache, precision, topology, and security decisions. The software engineer should stabilize prompt and repository identity. The kernel engineer should profile prefill, sparse attention, MoE dispatch, dequantization, KV copy, collectives, and the tool-idle gaps before claiming HBM is the bottleneck.
The serving libraries expose different memory-control surfaces
| Layer | What it controls | Documented control surface | What it does not prove |
|---|---|---|---|
| vLLM | Device KV allocation, PagedAttention, prefix reuse, scheduling | Engine flags and a versioned KV connector configuration | That a hit occurred, that lower-tier storage was used, or that the result passed |
| LMCache MP | Reusable KV outside the vLLM worker process | lmcache server plus LMCacheMPConnector and optional L2 adapter |
That MP, L2, GDS, CXL, or remote storage is healthy until that exact mode is observed |
| SGLang HiCache | Hierarchical cache policy inside the SGLang serving path | --enable-hierarchical-cache, capacity, write policy, I/O backend, layout, and storage backend flags |
That a configured backend moved bytes or improved accepted-task cost |
| Dynamo KVBM | GPU, pinned CPU, and disk KV hierarchy | DYN_KVBM_* capacities and DynamoConnector |
That host memory is CXL or that disk belongs on the latency-critical path |
| NIXL | Transfer orchestration across available memory and network transports | Connector or runtime configuration plus UCX/libfabric transport logs | A new physical link. NIXL selects and drives transports; it is not NVLink itself |
| NVLink and NVSwitch | High-bandwidth GPU scale-up fabric inside the supported topology | nvidia-smi topo, fabric-manager state, counters, and platform topology |
Cache identity, reuse, placement policy, or application correctness |
| BlueField DPU | Infrastructure processing for networking and storage paths | DOCA, RDMA, NVMe-oF, security, and storage services for the named system | That KV bypassed the CPU or reached a particular storage tier without a trace |
| CMX | NVIDIA's BlueField-4 STX context-memory storage direction | Vendor-described Spectrum-X, NIXL, DOCA Memos, and KV prestaging path | Shipping customer economics or the vendor's reported performance and power gains on this workload |
The current Dynamo LMCache documentation shows why version and role matter. In aggregated mode, a sidecar can be launched as:
# Official documentation shape. Capacity is illustrative, not a Touchdown default.
lmcache server --l1-size-gb 100 --eviction-policy LRU &
python -m dynamo.vllm \
--model MODEL_ID \
--disable-hybrid-kv-cache-manager \
--kv-transfer-config \
'{"kv_connector":"LMCacheMPConnector","kv_role":"kv_both"}'
[OFFICIAL DOCUMENTATION, VERSION-SENSITIVE] In the reviewed documentation, disaggregated decode uses a NIXL connector for the prefill-to-decode transfer, while prefill can use a MultiConnector that combines LMCache retention with NIXL movement. The documentation also carries a compatibility warning for the MP connector with the then-pinned vLLM release. Copying a command without pinning versions is not a reproducible experiment.
SGLang exposes a different policy surface:
# Official flag names. Backend availability and exact semantics are version-sensitive.
python -m sglang.launch_server \
--model-path MODEL_ID \
--enable-hierarchical-cache \
--hicache-ratio RATIO \
--hicache-write-policy write_through \
--hicache-io-backend BACKEND \
--hicache-storage-backend STORAGE_BACKEND
That command requests a hierarchy. The receipt must still identify which blocks were admitted, bytes written and restored, hit and miss counts, eviction cause, p99 restore time, and whether repository and prompt versions matched.
NIXL is not NVLink, and offload is not one hop
NIXL is a software data-movement layer. NVLink is a physical scale-up interconnect. UCX and libfabric are communication frameworks that can expose RDMA-capable transports. InfiniBand, RoCE, Spectrum-X Ethernet, AWS EFA, PCIe, and storage paths have different controllers, topologies, latencies, and failure modes. Saying NIXL transfer without the selected backend is like saying file copy without naming whether the bytes crossed DRAM, NVMe, Ethernet, or object storage.
NVIDIA Dynamo documents the disaggregated path as:
router selects prefill worker
-> prefill reads weights from HBM and creates KV in GPU memory
-> transfer metadata identifies blocks and endpoints
-> NIXL selects an available transport
-> same-domain transfer may use an applicable GPU path
-> cross-node transfer commonly uses RDMA through UCX or libfabric
-> decode worker installs the received KV blocks
-> decode reads local HBM KV and emits tokens
The minimum transfer proof is not a launch flag. It is the worker log showing the instantiated NIXL backend, topology capture, transferred bytes, first-byte and completion latency, overlap with compute, retry or fallback path, and a comparison against the same aggregated workload. A silent fallback to TCP can erase the reason for splitting prefill and decode.
BlueField and CMX add an infrastructure memory tier
BlueField is a DPU, not HBM. A DPU combines programmable processing with network and storage I/O so infrastructure work can be isolated from the host CPU. NVIDIA's BlueField-4 STX and CMX announcement describes a future context-memory storage tier built from Ethernet-attached flash, BlueField processing, Spectrum-X RDMA, NIXL, and DOCA Memos. [OFFICIAL VENDOR DIRECTION] The proposed read path is:
request or agent session identifies reusable context
-> metadata lookup resolves an exact KV object and version
-> CMX storage locates flash-resident KV pages
-> BlueField handles storage/network protocol and integrity work
-> Spectrum-X RDMA and NIXL move or pre-stage pages
-> host or GPU destination receives the blocks
-> serving engine validates layout and installs them
-> decode consumes the restored KV from local accelerator memory
NVIDIA reports up to 5 times tokens per second and up to 5 times power efficiency relative to traditional storage approaches for its named CMX context. Those remain [VENDOR CLAIMS], not Touchdown measurements and not a Hermes, Qwen, LMCache, SGLang, or Wan2.2 result. The engineering questions are still exact: Which bytes moved? From which flash and network path? At what granularity? Under what reuse distribution? What was the miss path? What failed? Did restore beat recompute at p99? Did the final patch pass?
The CPU tool loop is part of inference economics
Suppose the model emits a search command. The GPU can become idle while a CPU process searches the repository. The result returns as tokens. The model prefills or reuses a prefix and decodes the next action. A test command can run for seconds or minutes. A failed test returns a long log that expands context and KV state.
The cost can show up outside the model call:
- Repository indexing or retrieval returns too much low-value context.
- Tokenization and prompt construction run on the critical path.
- A stable prefix misses the cache because keys do not include the right version semantics.
- Tool results are appended repeatedly instead of summarized with a verifiable pointer.
- A CPU sandbox is underprovisioned, so the accelerator waits.
- The agent retries a patch because the test contract was vague.
- The cache restores stale state after the repository changed.
The unit is cost per accepted code change, not tokens per second alone.
What a complete coding-agent receipt contains
- Model ID, revision, attention configuration, dtype, serving engine, connector architecture, GPU, host, interconnect, and software versions.
- Input tokens split into stable prefix, repository context, current request, prior turns, and tool results.
- Prefill duration, verified prefix-cache key, hit/miss, tokens reused, and correctness policy.
- Active and reusable KV logical bytes, allocated bytes, block use, fragmentation, eviction, and transfer.
- Decode queue time, time to first token, inter-token latency, output tokens, and batching state.
- CPU search, file, edit, test, and lint time with accelerator overlap or idle time.
- Patch attempts, failed tests, retries, accepted diff, human corrections, and rollback.
- HBM, host, optional CXL, and disk residency by timestamp, including first-byte and full-restore p50/p95/p99.
If an LMCache/vLLM result is used, it also names the exact connector generation and mode. [OFFICIAL DOCUMENTATION, AS OF 2026-07-10] The LMCache quickstart recommends MP mode with a standalone lmcache server and LMCacheMPConnector, and documents connector-resolution differences below and above vLLM 0.20.0. The dynamic-connector documentation describes LMCacheConnectorV1 and LMCacheConnectorV1Dynamic while marking the in-process mode deprecated. These names are version-sensitive. Parser support is not live validation, and vLLM CPU-offload metrics are not automatically LMCache evidence.
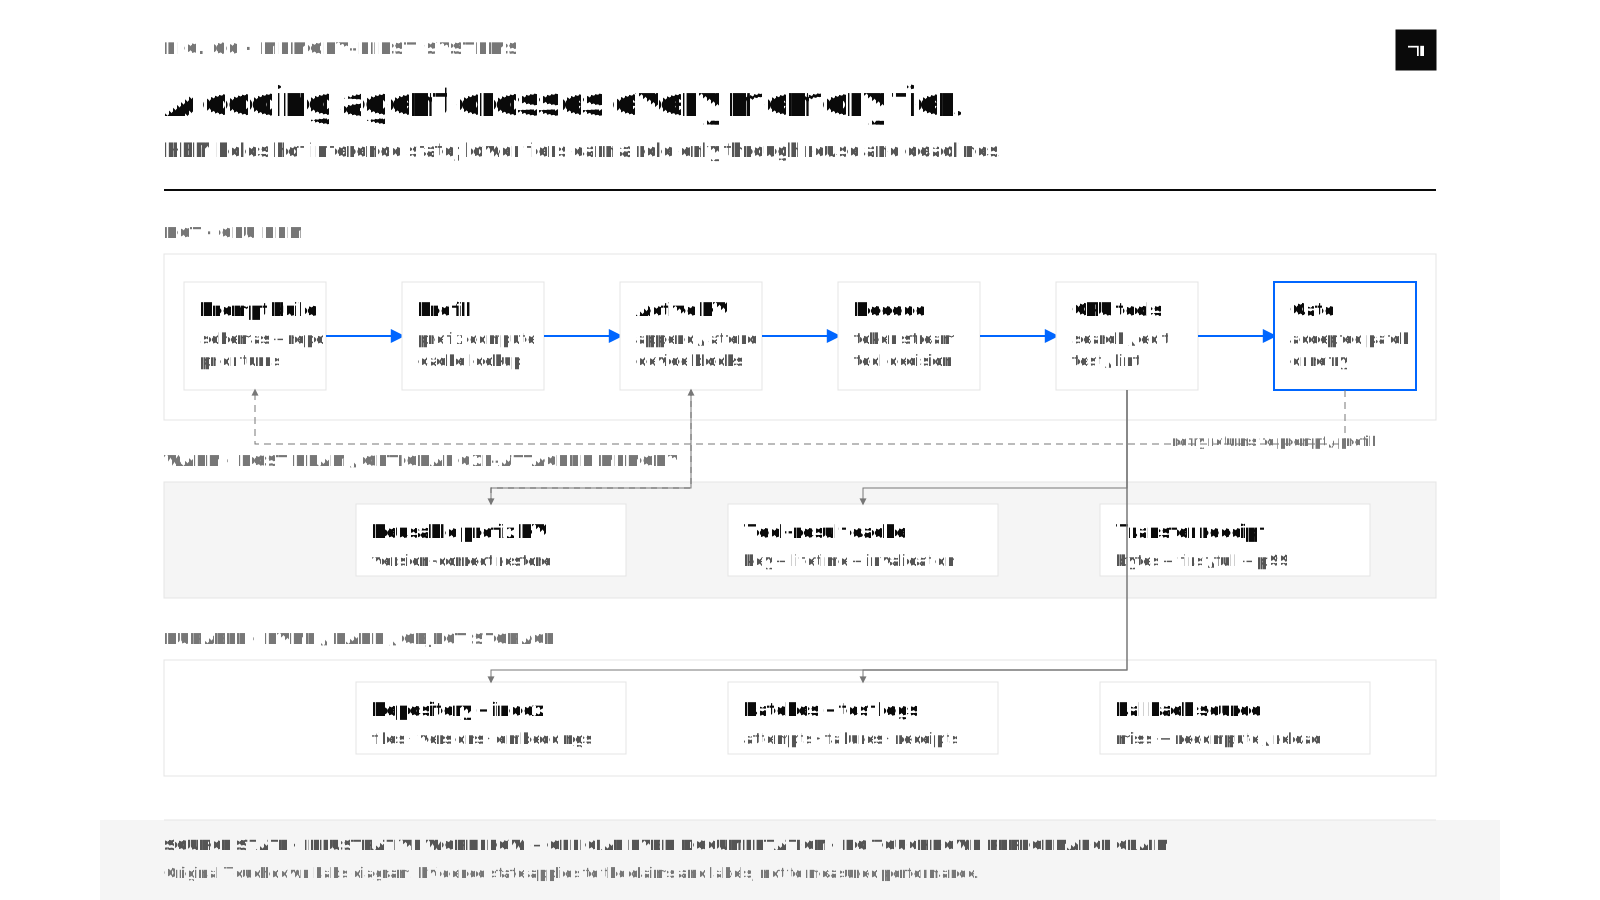
Same HBM, different workload
| Property | Wan2.2 video diffusion | Coding-agent inference |
|---|---|---|
| Repeated read state | Weights and conditioning across denoising steps | Weights, stable system/tool prefix, reusable prefix KV |
| Hot mutable state | Latent and current intermediates | Active KV, scheduler state, current token stream |
| Irregular state | Sparse-attention metadata and gathers | Repository retrieval, tool output, cache lookup |
| CPU path | Encoding, output, orchestration, possible offload | Search, file I/O, edits, tests, lint, prompt rebuild |
| Acceptance gate | Requested clip quality, format, latency | Correct patch, passing tests, reviewability |
| Failure cost | Wasted denoising run or rejected output | Repeated prefill/decode/tools, failed patch, human rework |
| Predictable stream opportunity | Layer/weight order can be predictable | Stable prefixes and read-mostly artifacts can repeat, but tools branch |
That symmetry is the reason to resist one universal memory slogan. Both workloads use HBM. They do not create the same state contract.
How does the NVIDIA software stack turn one GLM-5.2 coding task into HBM traffic?
In plain English. Hermes receives the coding task, a serving engine decides when and where model work runs, PyTorch expresses tensor operations, libraries or compilers choose implementations, CUDA launches GPU kernels, and the hardware reads and writes HBM. Those are different layers. A real receipt must name which branch was selected instead of listing every available library as if all of them ran.
The user does not buy CUDA, HBM bandwidth, or tokens per second. The user asks Hermes to inspect a repository, change code, run the tests, repair a failure, and return a patch that can be accepted. The unit that matters is one verified or accepted code change. Everything below that outcome is a path the system pays for: context construction, prefix lookup, prefill, MoE routing, matrix multiplication, attention, KV-cache writes, interconnect traffic, tool waits, retries, power, heat, cooling, and review.
This section follows that one task through NVIDIA's software and hardware path. It is a reference architecture, not a claim that every named component ran in one production request. A component is marked as observed only when a pinned run receipt contains its version, configuration, event, and artifact. Until then, the page says ARCHITECTURE ONLY / RUN NOT CAPTURED.
Code proof level: The companion examples are original Touchdown reference examples built against public APIs. They remain
fixture_backedornot_starteduntil the declared toolchain compiles them and a named GPU run produces correctness and profiler artifacts. The article never upgrades a documentation example into a measured GLM-5.2 result.
The same thirteen events stay visible from request to bill
The left learning journey and the article use the same event identity. Changing the audience view changes the explanation, not the workload, platform, precision, or event.
| Event | User and business boundary | Software and GPU boundary | Physics and economics boundary |
|---|---|---|---|
| 1. Request | One repository change with explicit tests and acceptance criteria | Hermes creates the tool-capable conversation | Admission starts the occupied-time boundary |
| 2. Context | Repository map, selected files, instructions, and tool schemas | Tokenizer and prompt builder create input IDs | Context bytes determine prefill work and initial KV demand |
| 3. Route | Quality, latency, and budget policy selects a path | Model, engine, precision, parallelism, and fallback are pinned | The route commits HBM capacity and infrastructure scope |
| 4. Prefix lookup | Reused context can avoid repeated work | vLLM prefix caching, SGLang RadixAttention/HiCache, or LMCache performs its own exact lookup | A hit has value only if restored state arrives before recomputation would finish |
| 5. Prefill | The model reads the complete admitted prompt | Batched matrix multiplications and attention create KV state | Weight reads, activation traffic, and KV writes pressure HBM bandwidth |
| 6. Attention and MoE | The model selects information and routed experts | Attention, top-k routing, permutation, grouped GEMM, and expert combine execute | Tensor Core work and irregular expert traffic compete for local and fabric bandwidth |
| 7. Lowering | No direct user-visible step | PyTorch eager, Inductor/Triton, FlashInfer, cuDNN, cuBLASLt, CUTLASS, CuTe, or custom CUDA selects executable work | Tile shape, data layout, registers, shared memory, TMEM, and launch shape decide useful traffic |
| 8. GPU and HBM | Work is still pending | CUDA Runtime/Driver launches kernels and manages streams, events, graphs, and allocations | SASS issues loads, stores, tensor operations, synchronization, and memory-controller requests |
| 9. KV placement | Conversation state must survive the next turn | Engine allocator appends KV or restores/offloads it through LMCache, HiCache, KVBM, or another declared path | HBM, pinned host memory, SSD, and remote memory have different latency and energy boundaries |
| 10. Decode | The next tool call or answer appears token by token | Repeated small decode steps reuse weights and growing KV state | Decode can become bandwidth and launch sensitive even when theoretical FLOPs are abundant |
| 11. Tool call | Search, edit, compiler, test, or lint leaves the model | CPU process, filesystem, sandbox, and storage execute the tool | GPU idle or overlap time still consumes reserved capacity and facility power |
| 12. Retry and verifier | Tests pass, fail, or force another turn | Logs re-enter context; the model may prefill, decode, and call tools again | Rejected work still consumed time, energy, cooling capacity, and money |
| 13. Outcome and bill | Patch is verified, accepted, rejected, or pending | Run artifacts join to the explicit verifier | Cost and energy per accepted patch are valid only when numerator and acceptance boundary align |
Precision is four decisions, not one label
FP8 does not mean every number in the system uses eight bits. Weights, temporary activations, arithmetic accumulation, and KV cache can use different formats in the same request. Each choice changes capacity, traffic, accuracy, and kernel support differently.
Saying a request "uses FP8" is incomplete. The receipt must separate weight storage, activation storage, accumulation, and KV-cache precision. They can differ within one layer.
| Path | Weight storage | Activations | Accumulation | KV cache | Evidence boundary |
|---|---|---|---|---|---|
| BF16 reference | BF16 | BF16 | FP32 or declared implementation | BF16 unless configured otherwise | Correctness reference, not automatically the cheapest path |
| FP8 path | FP8 or mixed by module | FP8/BF16 by operation | Higher precision declared by kernel/library | Independent setting | Requires scales, amax policy, excluded modules, and parity results |
| NVFP4 preparation | Block-scaled FP4 where supported | Mixed FP4/FP8/BF16 | Higher precision declared by kernel | Independent setting | A B200/GB200 reference experiment until export, compile, parity, and accepted-task replay pass |
| H200 comparison | BF16 or FP8 | BF16 or FP8 | Declared implementation | Independent setting | HBM3E/Hopper path; do not imply Blackwell NVFP4 execution |
| MI355X comparison | ROCm-supported BF16/FP8/FP4 path | Declared by AMD runtime/kernel | Declared implementation | Independent setting | Separate AMD receipt; never inferred from an NVIDIA result |
The GLM-5.2 model revision, tokenizer, configuration digest, quantization artifact, calibration data hash, excluded modules, scale granularity, and output-quality result belong in the same receipt. A smaller weight file is not a deployment win if quality falls, KV pressure forces a smaller batch, or the runtime cannot execute the artifact.
PyTorch starts the operation, but it does not name the final kernel
At the Python level, a transformer layer expresses tensor operations. The same operation can remain in eager ATen, enter torch.compile, lower through TorchInductor and Triton, call a library backend, or hit a graph break and return to eager execution.
# TOUCHDOWN REFERENCE SHAPE. Not a captured GLM-5.2 production layer.
import torch
@torch.compile(dynamic=True)
def attention_slice(q, k, v):
return torch.nn.functional.scaled_dot_product_attention(
q, k, v, is_causal=True
)
The code receipt must record the active source line, graph-break report, generated graph, selected backend, input shapes, strides, dtypes, and output parity. A Python function name is not proof that FlashInfer, cuDNN, or a particular fused kernel executed.
For the routed expert path, the useful symbolic shape is:
X_e [tokens_for_expert, hidden]
x W_up,e [hidden, intermediate]
-> U_e [tokens_for_expert, intermediate]
-> activation and gate
x W_down,e [intermediate, hidden]
-> Y_e [tokens_for_expert, hidden]
Before the grouped GEMM, routing selects experts and permutes tokens into expert-local groups. After it, outputs are combined into original token order. If expert parallelism crosses GPUs, token dispatch and combine add all-to-all traffic around the local matrix multiply. That is why a fast standalone GEMM does not prove a faster coding-agent turn.
The serving engine owns scheduling and KV allocation
Use four questions to keep the names straight:
- Who owns the state? The model server and its KV or prefix-cache manager identify and allocate it.
- Who decides placement? The scheduler and cache policy choose GPU, host, disk, or another declared tier.
- Who moves the bytes? A runtime, movement layer, or storage backend issues and tracks the transfer.
- What physical path carries them? NVLink, PCIe, RDMA, Ethernet, storage, or another named link supplies the actual route.
vLLM and SGLang are independent serving projects. LMCache is an independent KV-cache layer. NVIDIA Dynamo can orchestrate engines and separate prefill from decode. TensorRT-LLM is NVIDIA's optimized LLM runtime path. These are alternatives and integrations, not evidence that all of them executed together.
The reference packet contains separate recipes:
Recipe A: Hermes -> GLM-5.2 -> vLLM -> engine-native prefix cache -> optional LMCache
Recipe B: Hermes -> GLM-5.2 -> SGLang -> RadixAttention -> optional HiCache/NIXL
Recipe C: supported model artifact -> TensorRT-LLM -> NVIDIA-native comparison
Recipe D: Dynamo router -> prefill worker -> NIXL KV transfer -> decode worker
Only one recipe can be the observed primary path for a single run. A prefix hit also needs the engine's real identity rule, requested block count, found block count, hit tokens, restore bytes, restore time, and fallback. A conceptual similarity score is not an engine-level hit.
The integrated C-001 harness joins the whole path without inventing a run.
The public code packet includes one integrated C-001 reference harness. It is deliberately different from a benchmark launcher. Its default mode runs on a CPU, makes no network request, does not load GLM-5.2, and does not claim that CUDA or HBM executed. It assembles the complete typed receipt shape so an engineer, executive, or investor can see exactly which evidence a real replay still owes.
EVENT_ORDER = (
"request", "context", "route", "prefix_lookup", "prefill",
"attention_moe", "lowering", "gpu_hbm", "kv_placement",
"decode", "tool_call", "retry_verifier", "outcome_bill",
)
config = load_reference_config("reference-config.json")
receipt = architecture_receipt(config)
# Default truth boundary:
assert receipt["run_id"] is None
assert receipt["capture_kind"] == "architecture_only"
assert receipt["banner"] == "ARCHITECTURE ONLY / RUN NOT CAPTURED"
assert all(row["value"] is None for row in receipt["resource_ledger"])
Run the inspectable path with no GPU:
python3 examples/hbm-learning-journey/nvidia/08-c001-integrated/c001_reference_harness.py --pretty
python3 -m unittest discover \
-s examples/hbm-learning-journey/nvidia/08-c001-integrated \
-p 'test_*.py' -v
Capture mode does not start Hermes, vLLM, SGLang, CUDA, Nsight, or a facility meter. It joins artifacts a separate real workload already produced. The join requires fifteen hashed artifact kinds: request, context, route, prefix-cache identity, engine trace, operator trace, compiler artifacts, kernel profile, memory placement, fabric, tool, verifier, power, facility, and cost. Every artifact must carry the same non-placeholder run_id and synchronized clock boundary.
The harness rejects partial capture arguments, path traversal, hash mismatch, mixed run IDs, cache claims without model/tokenizer/engine/prefix/KV identity, accepted outcomes without a measured live verifier, duplicated energy ledgers, and coolant circulation mislabeled as consumed water. This is the actual code boundary between a useful architecture lesson and a false production claim.
Operator libraries make different promises
The operator layer is where the high-level tensor operation becomes a concrete implementation choice.
- cuBLAS and cuBLASLt provide matrix multiplication. cuBLASLt adds descriptors, layouts, heuristic selection, workspace, fused epilogues, and reduced-precision paths. The receipt needs matrix dimensions, layouts, input and compute types, selected algorithm, workspace, and duration.
- CUTLASS exposes source-visible hierarchical GEMM, tiling, pipelines, copies, Tensor Core operations, and epilogues. The packet includes BF16, FP8, block-scaled NVFP4, grouped MoE, decode-shape GEMV, and profiler examples tied to a pinned release.
- CuTe and CuTe DSL expose layouts, thread-value mapping, tiled copies, tiled MMA, TMA, shared-memory layout, and architecture-specific narrow-precision movement. A layout drawing is not a measured kernel.
- Transformer Engine manages transformer-oriented low-precision execution, recipes, scaling, and numerical comparison. Weight precision, activation precision, accumulation, and KV precision remain separate.
- NVIDIA Model Optimizer prepares quantized or otherwise transformed artifacts. Its output must retain the original revision, calibration hash, quantization configuration, excluded modules, export format, and evaluation delta.
- cuDNN Backend/Frontend can select operation graphs, heuristics, execution plans, attention paths, and workspaces. It stays an alternative until a trace names its plan.
- FlashInfer is an independent serving-kernel project with paged-KV, prefill, decode, sampling, GEMM, and MoE surfaces. Its exact API must match the pinned release.
- Triton is an independent kernel language and compiler used by PyTorch and inference projects. Generated Triton IR, LLVM IR, PTX, and cubin are artifacts, not assumptions.
- Custom CUDA C++ gives direct control and also direct responsibility for bounds, synchronization, numerics, portability, and maintenance.
CUDA compilation makes the executable boundary visible
The offline path and runtime-compiled path must remain distinct:
CUDA C++ source
-> nvcc or NVRTC
-> PTX virtual ISA
-> ptxas or driver JIT
-> cubin
-> architecture-specific SASS
-> scheduler, Tensor Core/CUDA Core, load-store unit
# REFERENCE COMMAND SHAPE. Select the architecture for the detected GPU and pinned toolkit.
nvcc -O3 --ptx kernel.cu -o kernel.ptx
nvcc -O3 --cubin kernel.cu -o kernel.cubin
cuobjdump --dump-sass kernel.cubin
nvdisasm kernel.cubin > kernel.sass
PTX is not final GPU machine code. SASS is the architecture-specific disassembly. NVRTC compiles device code at runtime; NVJitLink can join device modules. Compile latency must be reported separately from execution latency, and cached compilation must be distinguished from cold compilation.
Runtime allocation is not the same as engine KV allocation
The CUDA Runtime and Driver APIs expose devices, contexts, modules, streams, events, copies, launches, memory pools, peer access, and graphs. cudaMallocAsync can reuse storage from a stream-ordered pool. vLLM or SGLang can manage logical KV blocks above that allocation layer. The two allocators answer different questions.
// TOUCHDOWN REFERENCE SHAPE. Error checks omitted here; full example is in the repo.
cudaMemPool_t pool;
cudaDeviceGetDefaultMemPool(&pool, device_id);
cudaMallocAsync(&buffer, bytes, stream);
kernel<<<grid, block, shared_bytes, stream>>>(buffer);
cudaEventRecord(done, stream);
cudaFreeAsync(buffer, stream);
CUDA Graphs can reduce repeated CPU launch overhead by capturing a compatible sequence and replaying it. Batch shape, expert routing shape, addresses, or unsupported dynamic work can prevent reuse. The receipt therefore records graph eligibility, capture result, replay count, update failures, and fallback.
NCCL, NVLink, NVSwitch, and NIXL occupy different levels
NCCL asks for communication. NIXL coordinates state movement. NVLink carries bits over a physical scale-up link. NVSwitch routes those links across a supported domain. The same task can use more than one, but the names are not interchangeable.
NCCL implements collectives such as all-reduce, all-gather, reduce-scatter, all-to-all, and send/receive. NVLink and NVSwitch are physical scale-up fabric, not function calls. NIXL orchestrates point-to-point state movement and can select transports or storage backends. Dynamo KVBM manages KV blocks across declared memory tiers and uses NIXL for movement.
MoE token dispatch
-> NCCL or declared communication backend
-> NVLink/NVSwitch inside a supported scale-up domain
-> InfiniBand/RoCE and GPUDirect RDMA across nodes when qualified
Disaggregated KV movement
-> Dynamo/NIXL request
-> endpoint metadata and selected backend
-> GPU, pinned host, SSD, or remote source
-> physical transport
-> destination and completion event
NCCL Tests qualify a topology. They do not become GLM-5.2 throughput. nvidia-smi topo -m, NVLink status, Fabric Manager, DCGM, UCX information, InfiniBand verbs tools, and NIXL logs must agree about the route. A fallback to host bounce or TCP remains visible.
The trace must join code, hardware, power, cooling, and acceptance
NVTX gives business phases names such as C-001/prefill, C-001/moe_grouped_gemm, C-001/tool/pytest, and C-001/verifier. CUPTI supplies lower-level activity and correlation data used by NVIDIA profiling tools. Nsight Systems shows the end-to-end CPU, CUDA, memory-copy, NCCL, and idle timeline. Nsight Compute inspects selected kernels. Compute Sanitizer checks memory, race, initialization, and synchronization failures.
nsys profile --trace=cuda,nvtx,osrt,cudnn,cublas \
--output=glm52-hermes python run_hermes_fixture.py
ncu --set full --target-processes all \
--kernel-name 'regex:.*moe.*gemm.*' \
--output=glm52-moe-kernel python run_single_layer_fixture.py
NVML and DCGM can expose device identity, power, cumulative energy where supported, temperature, clocks, utilization, memory, health, and fabric state. They do not automatically provide facility energy or task attribution. A child GPU energy counter explains part of a rack or facility meter; it must not be added again when the parent meter already includes it.
The aligned accounting formulas remain:
IT_kWh = IT_kW * occupied_seconds / 3600
facility_kWh = IT_kWh * PUE
site_water_L = IT_kWh * WUE
cost_per_accepted_patch = total_aligned_path_cost / accepted_patches
PUE and WUE require a declared facility and time boundary. Closed-loop coolant circulation is not site water consumption. Electricity-generation water is another boundary again. If those inputs are absent, the result stays unknown.
Search the complete NVIDIA and adjacent-library packet
The matrix below is generated from the repository registry. It includes every component named in the archived research input. Required, Trace, Alternative, and Later describe its role in the teaching packet. Observed in run is a separate field and remains false until a receipt proves execution.
| Component and owner | Category | Packet role | Workload hook | Trace state | Coverage and evidence | Receipts |
|---|---|---|---|---|---|---|
| CUDA cubin artifact NVIDIA | binary_artifact | Required | compiler_artifact preserve target-specific GPU code object | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NCCL NVIDIA | collective_library | Required | distributed_execution collective traffic for tensor or expert parallelism | available_not_on_trace | parser_only source_backed_architecture | code · source |
| nvcc NVIDIA | compiler | Required | offline_compilation compile CUDA C++ to PTX, cubin and executable artifacts | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| torch.compile and TorchInductor PyTorch Foundation | compiler | Required | operator_lowering capture FX regions and lower them through Inductor | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NVIDIA Container Toolkit NVIDIA | container_runtime | Required | environment expose GPUs and driver libraries to OCI containers | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NIXL NVIDIA / ai-dynamo open-source project | data_movement | Required | kv_transfer orchestrate transfer through selected memory, network or storage plugins | available_not_on_trace | parser_only source_backed_architecture | code · source |
| GPUDirect RDMA NVIDIA | data_path | Required | scale_out_transfer enable supported NIC DMA to registered GPU memory | available_not_on_trace | parser_only source_backed_architecture | code · source |
| NVIDIA Dynamo NVIDIA / ai-dynamo open-source project | distributed_serving | Required | routing_and_disaggregation route requests and separate prefill from decode workers | available_not_on_trace | parser_only source_backed_architecture | code · source |
| NGC container NVIDIA | environment | Required | environment freeze a compatible user-space CUDA and inference stack | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NVLink NVIDIA | hardware_interconnect | Required | scale_up_fabric carry supported GPU-to-GPU scale-up traffic | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NVSwitch NVIDIA | hardware_switch | Required | scale_up_fabric switch NVLink traffic inside the supported domain | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| vLLM vLLM Project | inference_engine | Required | serving paged KV allocation, scheduling, prefix caching, prefill and decode | available_not_on_trace | parser_only source_backed_architecture | code · source |
| FlashInfer FlashInfer Project | inference_kernel_library | Required | prefill_and_decode_attention single-request prefill and decode attention against KV state | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| PTX ISA artifact NVIDIA | intermediate_representation | Required | compiler_artifact preserve virtual ISA before target-specific assembly | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| Custom CUDA C++ kernel Touchdown Labs example using NVIDIA CUDA | kernel | Required | kernel_execution launch a minimal checked kernel through the runtime and driver paths | available_not_on_trace | fixture_backed illustrative | code · source |
| CuTe and CuTe DSL NVIDIA | kernel_dsl | Required | kernel_authoring compose layouts, copies and MMA operations | available_not_on_trace | parser_only source_backed_architecture | code · source |
| Triton language and compiler Triton Project | kernel_dsl | Required | operator_lowering author and JIT compile a GPU kernel | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| CUTLASS NVIDIA | kernel_library | Required | gemm_and_moe source-visible BF16, FP8, NVFP4 and grouped GEMM kernels | available_not_on_trace | parser_only source_backed_architecture | code · source |
| Dynamo KVBM NVIDIA / ai-dynamo open-source project | kv_cache | Required | kv_offload_and_restore manage KV blocks across GPU, pinned host, SSD and remote tiers | available_not_on_trace | parser_only source_backed_architecture | code · source |
| SASS disassembly NVIDIA | machine_instruction_artifact | Required | compiler_artifact disassemble the target-specific instruction stream | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| cuBLAS NVIDIA | math_library | Required | linear_layer ordinary GEMM baseline | available_not_on_trace | parser_only source_backed_architecture | code · source |
| cuBLASLt NVIDIA | math_library | Required | linear_layer descriptor-based GEMM with heuristic tactic selection and workspace | available_not_on_trace | parser_only source_backed_architecture | code · source |
| CUDA stream-ordered memory pools NVIDIA | memory_management | Required | allocation allocate and reuse device memory with cudaMallocAsync | available_not_on_trace | parser_only source_backed_architecture | code · source |
| PyTorch eager and ATen PyTorch Foundation | model_framework | Required | model_execution reference eager operator path | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NVIDIA Model Optimizer NVIDIA | model_optimization | Required | quantization_preparation calibrate and prepare a quantized model artifact | available_not_on_trace | parser_only source_backed_architecture | code · source |
| Transformer Engine NVIDIA | precision_library | Required | transformer_linear FP8 execution with explicit recipe context | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| CUDA Graphs NVIDIA | runtime | Required | decode_replay capture and replay a stable launch graph | available_not_on_trace | parser_only source_backed_architecture | code · source |
| CUDA Runtime API NVIDIA | runtime | Required | kernel_dispatch device allocation, asynchronous launch and error handling | available_not_on_trace | parser_only source_backed_architecture | code · source |
| CUDA streams and events NVIDIA | runtime | Required | kernel_dispatch order asynchronous work and measure GPU elapsed time | available_not_on_trace | parser_only source_backed_architecture | code · source |
| CUDA Toolkit NVIDIA | toolchain | Required | environment provide compiler, runtime, libraries, binary tools and profilers | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| Compute Sanitizer NVIDIA | correctness_tool | Trace | kernel_correctness check memory and synchronization errors | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NCCL Tests NVIDIA | fabric_benchmark | Trace | fabric_qualification measure collective bandwidth on the exact allocated topology | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| DCGM NVIDIA | fleet_telemetry | Trace | device_and_fabric_telemetry collect health, power, energy, thermal, memory and link fields | available_not_on_trace | parser_only source_backed_architecture | code · source |
| CUPTI NVIDIA | instrumentation | Trace | gpu_activity_collection provide callback and activity data beneath profiler tools | available_not_on_trace | parser_only source_backed_architecture | code · source |
| NVTX NVIDIA | instrumentation | Trace | all_business_and_runtime_phases name C-001 phases for cross-layer timeline joins | available_not_on_trace | parser_only source_backed_architecture | code · source |
| Nsight Compute NVIDIA | kernel_profiler | Trace | selected_kernel_analysis collect kernel-level memory, occupancy and instruction metrics | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| InfiniBand verbs and performance tools linux-rdma community with vendor contributions | network_qualification | Trace | fabric_qualification inspect RDMA devices and measure bandwidth or latency | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| nvidia-smi NVIDIA | operator_cli | Trace | environment_and_topology report device identity, topology, link and coarse telemetry | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| Nsight Systems NVIDIA | profiler | Trace | end_to_end_timeline capture CPU, CUDA, NVTX and selected system activity | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| CUDA Driver API NVIDIA | runtime | Trace | module_load_and_dispatch load a target cubin, resolve a symbol and launch explicitly | available_not_on_trace | parser_only source_backed_architecture | code · source |
| NVML NVIDIA | telemetry_api | Trace | device_power_and_health sample timestamped power, temperature, clocks, utilization and memory | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| UCX OpenUCX Project | communication_framework | Alternative | transport_selection provide selected shared-memory, TCP, RDMA or GPU-aware transports | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| nvJitLink NVIDIA | compiler | Alternative | runtime_linking link device code into a loadable cubin | available_not_on_trace | parser_only source_backed_architecture | code · source |
| NVRTC NVIDIA | compiler | Alternative | runtime_compilation compile an in-memory CUDA C++ device program to PTX | available_not_on_trace | parser_only source_backed_architecture | code · source |
| SGLang SGLang Project | inference_engine | Alternative | serving RadixAttention scheduling, prefill, decode and tool-serving path | available_not_on_trace | parser_only source_backed_architecture | code · source |
| TensorRT-LLM NVIDIA | inference_engine | Alternative | serving NVIDIA-native LLM runtime comparison | unsupported | parser_only source_backed_architecture | code · source |
| TensorRT NVIDIA | inference_runtime | Alternative | supporting_model_execution build and run engines for encoders, rerankers or auxiliary models | available_not_on_trace | parser_only source_backed_architecture | code · source |
| cuDNN backend and frontend graph APIs NVIDIA | kernel_library | Alternative | attention_or_fusion build and execute supported operation graphs | available_not_on_trace | parser_only source_backed_architecture | code · source |
| LMCache LMCache Project | kv_cache | Alternative | prefix_lookup_and_offload lookup, inject, store and multi-tier KV movement through an engine connector | available_not_on_trace | parser_only source_backed_architecture | code · source |
| SGLang HiCache SGLang Project | kv_cache | Alternative | prefix_lookup_and_offload hierarchical GPU, host and storage KV caching | available_not_on_trace | parser_only source_backed_architecture | code · source |
| CUDA Unified Memory NVIDIA | memory_management | Alternative | memory_residency_teaching demonstrate managed virtual memory and migration | available_not_on_trace | not_started source_backed_architecture | code · source |
| NVSHMEM NVIDIA | one_sided_communication | Alternative | distributed_execution GPU-initiated one-sided communication and synchronization | available_not_on_trace | parser_only source_backed_architecture | code · source |
| nvCOMP NVIDIA | compression | Later | state_storage compress or decompress candidate state on GPU | available_not_on_trace | parser_only source_backed_architecture | code · source |
| CUB NVIDIA / CCCL | cuda_cpp_core_library | Later | optional_device_primitive provide block and device scan, reduce, sort and selection primitives | available_not_on_trace | parser_only illustrative | code · source |
| libcu++ NVIDIA / CCCL | cuda_cpp_core_library | Later | kernel_authoring use CUDA-aware C++ atomics and standard-library facilities | available_not_on_trace | parser_only illustrative | code · source |
| Thrust NVIDIA / CCCL | cuda_cpp_core_library | Later | optional_parallel_algorithm invoke CUDA C++ parallel algorithms | available_not_on_trace | parser_only illustrative | code · source |
| cuFFT NVIDIA | cuda_library_catalog | Later | scientific_or_media_operator fast Fourier transforms when invoked by a supporting workload | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| cuRAND NVIDIA | cuda_library_catalog | Later | sampling_or_diffusion_noise generate random values for sampling or diffusion paths | available_not_on_trace | parser_only illustrative | code · source |
| cuSOLVER NVIDIA | cuda_library_catalog | Later | optional_solver dense or sparse factorizations for supporting workloads | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| cuSPARSE NVIDIA | cuda_library_catalog | Later | optional_sparse_operator sparse matrix operations when the selected workload invokes them | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| cuSPARSELt NVIDIA | cuda_library_catalog | Later | optional_structured_sparse_gemm structured sparse matrix multiplication | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| cuTENSOR NVIDIA | cuda_library_catalog | Later | optional_tensor_contraction general tensor contraction when selected by a workload | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| cuTensorNet NVIDIA | cuda_library_catalog | Later | tensor_network_workload tensor-network contraction outside the central GLM path | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| Cooperative Groups NVIDIA | cuda_programming_model | Later | kernel_authoring coordinate explicit thread groups | available_not_on_trace | parser_only illustrative | code · source |
| DALI NVIDIA | data_pipeline | Later | media_loading_and_preprocessing build accelerated input pipelines for declared media workloads | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| DOCA NVIDIA | dpu_sdk | Later | network_or_storage_offload program supported BlueField networking, storage or DPA services | available_not_on_trace | not_started source_backed_architecture | code · source |
| Multi-Instance GPU (MIG) NVIDIA | gpu_partitioning | Later | deployment_and_isolation partition supported GPUs into isolated instances | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| CUDA Multi-Process Service (MPS) NVIDIA | gpu_sharing | Later | deployment_and_concurrency share GPU execution resources across CUDA processes | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| BlueField DPU NVIDIA | hardware_dpu | Later | network_or_storage_offload host supported DOCA services and offload selected infrastructure work | available_not_on_trace | not_started source_backed_architecture | code · source |
| NVIDIA GPU Operator NVIDIA | kubernetes_operator | Later | cluster_deployment reconcile GPU drivers, device plugin, toolkit, telemetry and MIG components | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NVIDIA Network Operator NVIDIA | kubernetes_operator | Later | cluster_deployment reconcile RDMA and accelerated networking components | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NVDEC NVIDIA | media_hardware_api | Later | video_decode decode source or validation video for Wan2.2 workflows | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NVENC NVIDIA | media_hardware_api | Later | video_encode encode accepted Wan2.2 output clips | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| CV-CUDA NVIDIA / CV-CUDA Project | media_library | Later | media_preprocessing GPU image preprocessing for a declared media workload | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| NPP NVIDIA | media_library | Later | image_or_signal_processing run image and signal primitives when selected by a media path | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| nvImageCodec NVIDIA | media_library | Later | image_codec_dispatch select image codec implementations for a media workload | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| nvJPEG NVIDIA | media_library | Later | image_decode decode JPEG inputs for media workloads | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| nvJPEG2000 NVIDIA | media_library | Later | image_decode decode JPEG 2000 inputs for media workloads | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| CUDA Virtual Memory Management NVIDIA | memory_management | Later | address_space_management reserve, map and remap virtual address ranges | available_not_on_trace | not_started source_backed_architecture | code · source |
| NVIDIA Triton Inference Server NVIDIA | model_server | Later | deployment serve model repositories through backend adapters | available_not_on_trace | parser_only source_backed_architecture | code · source |
| cuDSS NVIDIA | solver_library | Later | optional_sparse_direct_solver solve sparse linear systems outside the central LLM path | available_not_on_trace | fixture_backed source_backed_architecture | code · source |
| GPUDirect Storage and cuFile NVIDIA | storage_data_path | Later | weight_or_state_storage move supported file data to or from GPU memory with explicit fallback reporting | available_not_on_trace | parser_only source_backed_architecture | code · source |
B200, GB200, H200, MI355X, Rubin, and Kyber are not interchangeable labels
The default reference profile is B200/GB200 with an NVFP4 preparation path. That is not a public GLM-5.2 NVFP4 workload receipt. H200 remains a Hopper/HBM3E BF16 or FP8 comparison. MI355X remains a separate AMD ROCm receipt path. Equal evidence means the same task, model revision or explicitly bounded substitute, quality gate, SLO, concurrency, meter boundary, and acceptance rule.
Rubin is a GPU generation. Kyber is a rack architecture for larger future scale-up domains. Neither name is evidence that this C-001 run executed there. Roadmap and preliminary system specifications stay source-backed architecture until hardware, software, topology, and workload receipts exist.
What the run receipt must prove
One real C-001 execution has one run_id. Wan2.2 V-001 has a different run_id; the two workloads join only through a declared comparison identifier.
The public page emits a demo manifest, not a fake run receipt:
schema_version: touchdown.hbm-demo-manifest.v1
fixture_id: C-001
comparison_id: CMP-C001-V001
publication_hold: false
trace_contract:
run_id: null
capture_kind: architecture_only
banner: ARCHITECTURE ONLY / RUN NOT CAPTURED
run_receipt_emitted: false
A real receipt is a different object. It requires one non-placeholder run ID and a captured environment, typed events, artifacts, verifier, and resource boundaries:
schema_version: touchdown.hbm-run-receipt.v1
fixture_id: C-001
run_id: required
capture_kind: measured_run
environment:
agent: Hermes
model_revision: required
engine_and_version: required
weight_precision: required
activation_precision: required
accumulation_precision: required
kv_precision: required
gpu_uuid_and_topology: required
events:
- request
- context_snapshot
- route_decision
- cache_lookup
- engine_phase
- model_operation
- kernel_dispatch
- memory_activity
- fabric_activity
- tool_call
- verifier_result
- power_interval
- thermal_cooling_interval
- water_allocation
- cost_allocation
outcome:
state: pending
verified_patch requires the declared automated verifier. accepted_patch additionally requires explicit acceptance. No accepted output means energy and cost per accepted output are null even though total time, energy, and cost remain visible.
Primary documentation for this code path
- CUDA Toolkit, Runtime, Driver, compiler, binary utilities, and library documentation
- NVRTC runtime compilation
- CUTLASS and CuTe
- cuDNN graph and backend interfaces
- Transformer Engine
- TensorRT-LLM
- NCCL
- NVIDIA Dynamo, NIXL, and KVBM
- FlashInfer
- Nsight Systems, Nsight Compute, DCGM, and NVML
How do Vera, Rubin, HBM4, CMX, and Kyber form one accepted-task system?
In plain English. Vera is the CPU side that handles control-heavy work and tools. Rubin is the GPU side that repeatedly transforms model tensors. HBM4 is Rubin's local working memory. NVLink connects selected CPU and GPU or GPU and GPU domains. CMX is a lower context-storage tier. Kyber is a future rack design. Together they describe possible homes and paths for one task; they are not one chip and they do not prove that GLM-5.2 ran on the platform.
The earlier sections explain each layer. This section keeps all of them on one page.
Start with the user. A developer does not buy an HBM stack, an NVLink domain, or a rack. The developer asks Hermes, backed by GLM-5.2, to inspect a repository, change code, call tools, run tests, repair failures, and return one accepted patch. The system earns its cost only when that verifier closes.
C-001 request
-> repository, policy, tools, and prior turns
-> CPU orchestration and tokenization
-> cache identity and placement decision
-> GPU prefill, attention, MoE, and KV creation
-> decode a tool call
-> CPU sandbox, compiler, tests, or retrieval
-> restore a valid prefix or recompute it
-> more GPU decode
-> candidate patch
-> verifier
-> accepted patch or another paid attempt
NVIDIA's Vera Rubin architecture gives the path named physical homes. Vera is the CPU and CPU-memory side. Rubin is the GPU and HBM4 side. NVLink-C2C connects those two memory domains coherently. NVLink 6 and NVSwitch connect GPU domains for scale-up. ConnectX and Spectrum-X or InfiniBand handle other network boundaries. BlueField-4 handles infrastructure work. CMX is a flash-backed shared context tier below HBM and host memory. MGX packages compute, switching, power, cooling, mechanics, and serviceability into rack systems. Kyber is a later MGX rack architecture, not a GPU or memory generation.
Evidence boundary. NVIDIA's 2026 material is official product and preliminary roadmap documentation. It establishes named architecture, published specifications, and vendor targets. It does not establish a Touchdown GLM-5.2 run, accepted-patch rate, customer price, sustained HBM traffic, rack energy per task, CMX restore p99, or Kyber application result. Those fields remain unknown until a synchronized run receipt exists.
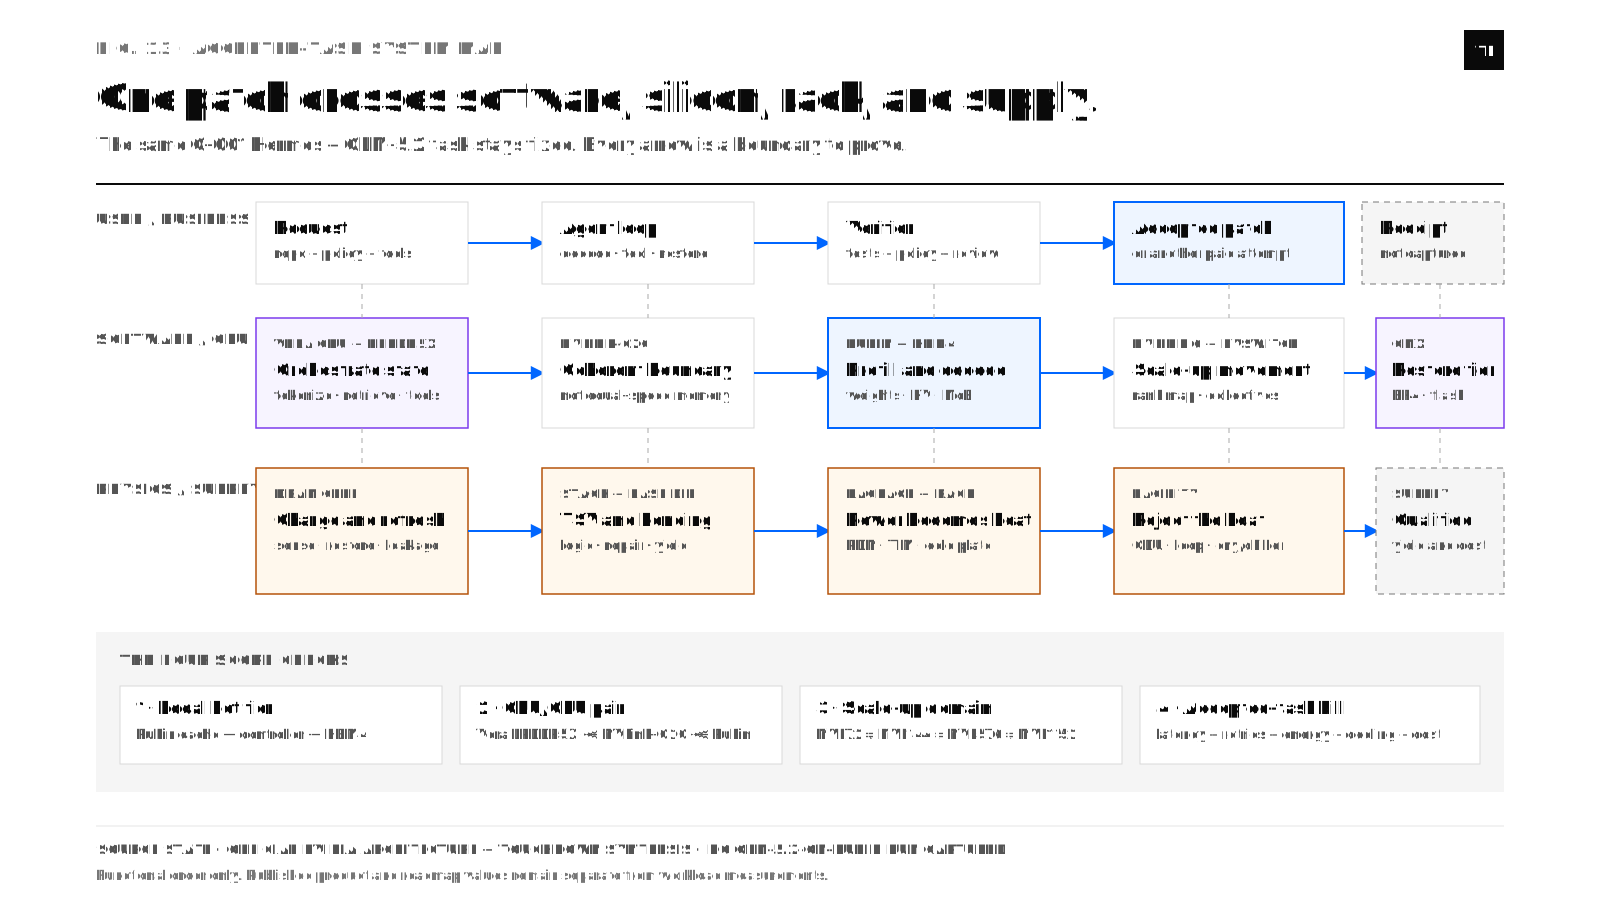
One request crosses six different boundaries
The word memory hides six different contracts in this example.
| Boundary | What crosses it | Physical path | Failure the user feels |
|---|---|---|---|
| Application to model | Instructions, schemas, retrieved code, tool results | CPU memory into the serving engine | Wrong or bloated context, bad cache identity, longer prefill |
| Vera to Rubin | Tokens, metadata, state, commands, and possibly reusable tensors | Coherent NVLink-C2C between CPU LPDDR5X and GPU HBM4 domains | Migration or remote access misses the latency deadline |
| Rubin to local HBM4 | Weights, active KV, activations, expert buffers, workspaces | GPU cache and controller into multiple HBM4 stacks | Capacity pressure, low useful bandwidth, stalls, throttling |
| Rubin to Rubin | Tensor, expert, sequence, or collective buffers | NVLink 6 through NVSwitch inside a named scale-up domain | Exposed collective wait, imbalance, retries, degraded links |
| Compute to context storage | Reusable or evicted KV blocks plus identity and integrity metadata | HBM or host memory through DPU/NIC, Spectrum-X, CMX flash, and back | Restore arrives too late, misses, is stale, or reduces batch capacity |
| Silicon to accepted result | Electricity, heat, telemetry, retries, and verifier state | Package, rack power, liquid loop, facility boundary, and software receipt | More rack time, energy, water allocation, or money per accepted patch |
These are not one flat address space or one flat bandwidth number. Coherence can make CPU and GPU memory easier to program without making remote CPU memory equal to local HBM. A large NVLink domain can reduce a scale-out boundary without making all HBM bytes equally local. CMX can retain reusable context without becoming a hot-tier replacement.
Vera CPU owns the control-heavy half of the agent loop
The CPU is not a background detail. It prepares prompts, schedules GPU work, runs the operating system, searches repositories, launches tests, handles storage and networking, and joins the final evidence. A faster GPU cannot remove a serial tool or verification bottleneck on the CPU.
NVIDIA describes Vera as a data engine rather than a passive boot processor. Its official architecture pairs up to 1.5 TB of LPDDR5X with up to 1.2 TB/s of CPU-memory bandwidth. Second-generation NVLink-C2C provides a published 1.8 TB/s coherent CPU-GPU path. [OFFICIAL PRODUCT DOCUMENTATION, REVIEWED 2026-07-11] Those are vendor specifications, not measured C-001 values.
For the fixed coding task, the CPU side can own:
Linux and containers
Hermes agent state
request parsing and authentication
repository and policy retrieval
tokenization and prompt construction
tool schemas and cache identity
scheduler, admission, block tables, and placement policy
CUDA Runtime and Driver calls
NCCL and NIXL setup
sandboxed search, editing, compilation, tests, and lint
retries, verifier, and telemetry joins
Rubin does not run git grep, a Python test suite, or the human acceptance rule merely because it is the accelerator. During a tool call, the GPU may serve another request, hold state, spill reusable state, or sit idle. That interval belongs in the economics. Faster decode does not fix a serial test suite; more HBM does not fix a broken sandbox.
The published coherent-memory model can make placement and migration easier, but four distinctions remain:
- A unified virtual address is not one uniform latency domain.
- Coherence is not proof that a tensor lived in Vera memory or moved over NVLink-C2C.
- CPU LPDDR5X bandwidth is not Rubin HBM4 bandwidth.
- Unified Memory is a mechanism, not a complete KV-cache policy. The engine still needs identity, deadlines, admission, prefetch, eviction, security, and fallback.
Rubin GPU and HBM4 own the hot repeated path
NVIDIA's current Rubin documentation publishes 288 GB of HBM4 per GPU, up to 22 TB/s of aggregate HBM4 bandwidth per GPU, and 3.6 TB/s of bidirectional NVLink 6 bandwidth per GPU. It also describes 224 streaming multiprocessors and fifth-generation Tensor Cores. [OFFICIAL PRODUCT DOCUMENTATION, REVIEWED 2026-07-11] The word up to and the physical scope matter. These figures do not say how much GLM-5.2 traffic is useful, how many HBM stacks are exposed to software, or whether one kernel reaches the device peak.
For C-001, Rubin's hot tier can contain:
| Object | Why it wants HBM4 | Why capacity alone is insufficient |
|---|---|---|
| Model weights and experts | Decode repeatedly reads weights; MoE needs candidate experts resident or fetchable | Forty billion active parameters per token does not mean only forty billion parameters need placement |
| Active KV | The next token reads prior attention state and appends new state | Exact geometry depends on GLM-5.2 architecture, engine, dtype, block layout, and concurrency |
| Prefill activations | Long prompts expose large attention and GEMM work | Temporary peaks, tiling, fusion, and checkpointing change live bytes |
| MoE routing buffers | Tokens are permuted, dispatched, combined, and sometimes moved across GPUs | Expert imbalance and all-to-all wait can dominate even with free HBM |
| Kernel workspaces | Libraries reserve temporary buffers for selected algorithms | Reserved allocation is not logical tensor size or measured traffic |
| Communication buffers | Collectives and transfers need staging and synchronization | Aggregate link bandwidth is not application progress |
The execution path remains:
PyTorch operation
-> vLLM, SGLang, or another pinned engine
-> eager dispatch, torch.compile, or engine-specific lowering
-> cuBLASLt, CUTLASS, cuDNN, FlashInfer, Triton, or custom CUDA
-> PTX
-> target cubin and SASS
-> Rubin SM and Tensor Core execution
-> registers, shared memory or TMEM, L2, memory controller, HBM4
One Python line can fuse into a generated kernel, call an external library, trigger several kernels, or graph-break into fallback. The article's NVIDIA example registry therefore treats framework support, configured execution, dispatched artifacts, profiler evidence, and accepted output as separate states.
HBM4 begins as a DRAM bit and ends as qualified package capacity
HBM4 is still dynamic random-access memory. Each stored bit ultimately depends on charge, capacitance, voltage, sensing margin, leakage, restoration, and refresh. HBM becomes high-bandwidth by stacking dies, connecting them vertically, exposing a wide 2,048-bit-class interface, creating parallel channels, shortening package routes, and scheduling many requests, not by inventing a refresh-free cell.
The complete manufacturing path is:
DRAM design and wafer process
-> known-good memory dies
-> TSV formation, thinning, reveal, and test
-> die bonding and stack assembly
-> base or interface logic die
-> dense package fabric, substrate, and accelerator die
-> electrical, memory, link, power, and thermal test
-> repair, burn-in, reliability, and customer qualification
-> cooled server and rack that can sustain the workload
In 2026, named vendor evidence has advanced beyond a generic roadmap. Micron reports 36 GB 12-high HBM4 in high-volume production for Vera Rubin and 48 GB 16-high samples. Samsung reports commercial HBM4 shipments using a 4 nm logic base die. Samsung and SK hynix report shipping 12-layer HBM4E samples, not HBM4E volume production. [VENDOR PRODUCT AND SAMPLE ANNOUNCEMENTS, REVIEWED 2026-07-11] Supplier announcements remain vendor evidence. A sample is not customer qualification; gross stack output is not delivered accelerator capacity.
The system supply bound is therefore:
usable accelerator output = min(
good accelerator dies,
qualified HBM stacks,
base-die and advanced-package capacity,
substrates and assembly,
test and repair capacity,
firmware and system qualification,
power- and cooling-ready racks
)
An HBM shortage reaches software because scarce hot-tier bytes become more valuable. Prefix stability, paged allocation, FP8 KV, NVFP4 weight paths, expert placement, compression, offload, batching, and reduced fragmentation can increase accepted tasks per constrained HBM GB. None is free: every saved byte must survive quality, latency, energy, failure, and engineering-cost gates.
HBM4E and custom HBM expand the logic boundary
HBM4E is not merely HBM4 at a higher clock. Public 2026 samples add higher vendor-reported pin rates and approximately 4 TB/s-class per-stack targets, while the base die, packaging, signal integrity, power density, thermals, test, yield, and customer qualification become harder. Those are sample-stage vendor targets, not a common shipping configuration.
Custom HBM changes another variable: customer-specific logic, interface behavior, or adjacent functions can move into the base-die and package design. Marvell, Samsung, Micron, and SK hynix have publicly described custom-HBM directions. Possible design surfaces include movement, telemetry, RAS, security, repair, remapping, layout conversion, compression, or carefully bounded near-memory operations. The public material does not prove that every function moves, that the full memory controller relocates, or that a startup can order it on useful terms.
Touchdown uses modular HBM more narrowly as a research term: expose composable memory-movement primitives such as place, prefetch, gather, scatter, compress, quantize, restore, repair, and remap, then choose whether each primitive belongs in software, a GPU kernel, the accelerator controller, a DPU, a package chiplet, or a custom base die.
That is a hypothesis, not a product claim. For each primitive, the receipt needs:
object identity and security domain
preconditions and correctness rule
software API and lowering
source and destination
latency and useful/physical bytes
power, heat, and error counters
fallback and rollback
accepted-task replay
manufacturing, yield, NRE, and lock-in cost if silicon changes
The base die earns the function only when avoided movement exceeds its area, power, heat, verification, yield, non-recurring engineering, software, and supply-chain costs.
NVLink-C2C, NVLink 6, NVSwitch, and the network are different paths
Use the names at their physical scopes:
Vera CPU <-> paired Rubin GPUs
second-generation NVLink-C2C, coherent CPU-GPU path
Rubin GPU <-> Rubin GPU inside a named scale-up domain
NVLink 6 through NVSwitch
compute node or rack <-> another network endpoint
ConnectX or BlueField through InfiniBand or Spectrum-X Ethernet
HBM or host state <-> CMX context tier
engine/KV manager + NIXL + transport + BlueField/Spectrum-X + flash
NIXL is software for data movement. NVLink is a physical scale-up link. NCCL is a collective-communication library. NVSwitch is switching silicon. BlueField is an infrastructure processor. CMX is a context-storage platform. Calling all of them NVLink erases the exact boundary an engineer must measure.
For GLM-5.2 MoE, the runtime may shard or replicate experts and use all-to-all exchange for token dispatch and combine. A larger scale-up domain offers more placement choices, but can also enlarge the participant set, synchronization surface, failure domain, and idle-capacity bill. The required artifact is not a topology diagram. It is a rank map joined to collective message sizes, p50/p95/p99, link state, HBM traffic, accepted patches, and cost.
CMX is a restore tier, not more local HBM
NVIDIA describes BlueField-4-powered CMX as a flash-backed, Ethernet-attached context tier for reusable KV at pod scale. Dynamo and KV block managers decide placement; NIXL orchestrates movement; Spectrum-X supplies the RDMA network; BlueField-4 handles the KV I/O plane; DOCA Memos supplies context communication and storage functions. NVIDIA publishes vendor targets of up to 5x sustained tokens per second and 5x power efficiency relative to traditional storage for its described use case. [OFFICIAL VENDOR ARCHITECTURE AND TARGET, REVIEWED 2026-07-11] This article does not convert those targets into C-001 results.
This supports the memory-wall argument across both accelerator generations without collapsing them. A Blackwell GPU keeps its active working set in its own HBM3E. A Rubin GPU keeps its active working set in HBM4. Vera's LPDDR5X is a separate CPU-memory domain. BlueField-4 is a DPU that handles infrastructure processing. CMX is the lower flash-backed context platform built around that DPU, Spectrum-X, NIXL, DOCA Memos, and the serving layer. None of those lower tiers turns into local GPU HBM. They reduce HBM pressure only when a reusable KV object can leave the hot tier and return before recomputation would have finished.
For the full software and memory-hierarchy explanation, read KV Cache Is Becoming the Memory Hierarchy of Inference. This HBM article uses that earlier work as the systems context, then follows the additional package, fabric, power, cooling, supply, and cost boundaries.
The safe hierarchy is:
Rubin HBM4
active weights, active KV, activations, workspaces
Vera LPDDR5X
CPU work, warm state, metadata, possible offload or staging
local SSD or CMX
reusable context that can be prefetched before its deadline
general storage
durable repositories, indexes, logs, artifacts, and cold state
A CMX restore wins only when:
identity lookup
+ queueing
+ network transfer
+ flash service
+ integrity check
+ HBM placement
+ miss and tail-risk cost
<
recomputed prefill under the same p99 and quality requirement
The cache key must include the model and tokenizer revision, template, tool schema, repository commit, policy version, tenant, ACL, KV format, and engine compatibility. A fast stale or cross-tenant restore is a correctness and security failure.
NVL72, Kyber NVL144, NVL576, and Feynman Kyber NVL1152 are different systems
HBM belongs to individual accelerator packages. When a model spans many accelerators, some data must cross package, rack, or multi-rack boundaries. The names below identify nested system scopes: one GPU, one rack, or several racks connected into a larger domain. A larger number is not automatically a faster task.
The latest official NVIDIA topology keeps four scopes separate:
| Name | Rack composition | Published scale-up scope | Evidence state |
|---|---|---|---|
| Vera Rubin NVL72 | One MGX NVL rack with 72 Rubin GPUs and 36 Vera CPUs | 72-GPU NVLink domain | Official product architecture; NVIDIA says full production with shipment targeted for the second half of 2026 |
| Vera Rubin Ultra Kyber NVL144 | One future Kyber rack | 144 GPUs in one rack-scale NVLink domain | Official preliminary roadmap |
| Vera Rubin Ultra NVL576 | Eight separate 72-GPU MGX NVL racks | 576 GPUs in one multirack NVLink domain | Official preliminary roadmap |
| Feynman Kyber NVL1152 | Eight future 144-GPU Kyber racks | 1,152 GPUs in one multirack NVLink domain | Official preliminary roadmap |
Kyber is the future 144-GPU MGX NVL rack architecture. It is not Rubin, Rubin Ultra, Feynman, HBM4E, NVL576, or a generic word for every NVIDIA rack. NVIDIA's older 800 VDC material used different illustrative Kyber language; the March 2026 POD topology above is the current naming authority used here.
NVIDIA also describes third-generation MGX features including modular cable cartridges, a PCB midplane, power steering, rack-level energy storage, 45 C liquid-cooling operation, and serviceable NVLink switch trays. Those are architecture and vendor claims. Final Kyber PCB stackup, board dimensions, impedance distributions, manufacturing yield, supplier allocation, qualified power envelope, cooling flow, customer price, and GLM-5.2 result are not public in the reviewed primary sources.
A larger domain matters only if the workload uses it. A low-concurrency coding service can pay for idle GPUs. A model-parallel MoE can gain from local expert placement and still lose to collective imbalance, tool-idle time, or retries. Wan2.2's current Ulysses constraints do not become a valid 144-way configuration merely because a future rack contains 144 GPUs.
Power, cooling, supply, and money close the same receipt
The rack does not stop at GPU telemetry:
utility and switchgear
-> UPS, rectification, distribution, busbar, and voltage conversion
-> Vera, Rubin, HBM4, NVSwitch, ConnectX, BlueField, storage, pumps, and controls
-> package heat through TIM and cold plate
-> rack manifold and technology-cooling loop
-> CDU and facility-water loop
-> dry cooler, chiller, cooling tower, or heat-reuse sink
Power is a rate. Energy is power integrated over time. Heat transported by liquid is not electrical energy. Closed-loop coolant circulation is not site-water consumption. Site withdrawal, discharge, evaporation, drift, blowdown, and source-energy water are separate ledgers. PUE and WUE are useful only when their intervals and boundaries align with the task allocation.
For the same C-001 run, the CFO-facing denominator is:
cost_per_verified_accepted_patch =
accelerator_or_provider_time
+ CPU, sandbox, storage, and network
+ allocated facility electricity and cooling
+ allocated site-water cost where measured
+ retries and rejected attempts
+ engineering, operations, and review allocation
------------------------------------------------
verified accepted patches
No value is inferred from a roadmap. Unknown remains visible. A vendor rack envelope sizes infrastructure; only synchronized meters and an allocation rule turn it into task energy. A supplier shipment statement informs diligence; only qualified delivered capacity turns it into available service.
The alternatives change the boundary, not the proof rule
The article's later sections examine each alternative in detail. This is the compact system map:
| Architecture | What changes | Current evidence boundary | C-001 question |
|---|---|---|---|
| Standard HBM4 | Wider stacked-DRAM hot tier and more capable base/interface logic | Named vendor products are shipping or ramping; workload-specific traffic remains unmeasured | Do useful HBM bytes and accepted throughput justify the package and supply cost? |
| HBM4E | Higher vendor targets within the next HBM generation | Named vendor samples and development targets; not one common volume product | Does the higher interface target survive power, heat, signal, package, yield, qualification, and useful-bandwidth measurement? |
| Custom HBM or cHBM | Customer-specific base/interface-die logic, controller, security, telemetry, or bounded compute surfaces | Vendor design direction; access, function partition, NRE, ownership, and production qualification remain customer-specific | Which function belongs in the base die, and does replay pay back NRE, heat, yield, and lock-in? |
| SPHBM4 | JEDEC standard-package HBM4-stack integration direction using a different buffer/interface boundary | Public standard record; a shipping product, access terms, and workload value must still be named | Does the standard package path improve access or integration without losing the state deadline, bandwidth, or qualification contract? |
| Memory-on-logic | DRAM moves above logic through much denser vertical connections | Research and modeled systems unless a named product says otherwise | Does shorter movement survive heat, PDN, test, repair, yield, and serviceability? |
| Qualcomm HBC | Near-memory compute and 3D-stacked LPDDR-based architecture | Official forward-looking Dragonfly roadmap; HBC Gen 1 commercial samples expected in 2027 | Do vendor effective bandwidth targets become lower cost per accepted task at matched quality and p99? |
| Intel XBM | Patent-described backend-transistor DRAM, fine subchannels, repair, and UCIe-facing serialization | Published patent application, not shipping silicon or a committed product | Can the cell, stack, base-die arbitration, link, package, and repair path be built and measured? |
| Huawei HiBL / HiZQ | Phase-specific proprietary HBM direction for prefill/recommendation versus decode/training | Official Huawei roadmap and vendor specifications; supplier, process, yield, and independent results remain undisclosed | Does workload phase specialization beat a complete system under the same verifier and facility boundary? |
| CXMT reported HBM path | Potential DRAM and packaging integration path | CXMT officially lists DDR and LPDDR; HBM product, qualification, bandwidth, yield, and volume were not found on its product site | Which reported supply-chain elements become qualified shipping artifacts? |
| NVIDIA CMX | Shared flash-backed context tier below hot memory | Official vendor architecture and performance targets, not a local-HBM replacement | Does verified restore beat recomputation without harming batch capacity, p99, security, or energy? |
The memory wall is not one wall
The useful part of the argument in the Wafer post is physical: moving a bit costs energy, and a shorter, denser connection can reduce that cost. HBM already applies that idea. It moves stacked DRAM close to the accelerator and replaces a narrow off-package memory channel with a very wide package-local interface.
The argument becomes too simple when distance is treated as the whole memory wall. The complete problem has at least eight coupled limits:
capacity
+ physical bandwidth
+ useful bandwidth after access-pattern and protocol losses
+ latency and queueing
+ data-movement energy
+ DRAM activation, refresh, retention, and controller energy
+ package, power-delivery, and cooling limits
+ yield, repair, qualification, supply, and cost
= the memory wall seen by a real system
A design can shorten one wire and still lose on capacity, bank conflicts, refresh, heat, yield, software coverage, or total cost. It can publish a very large effective bandwidth number without exposing physical pin bandwidth or sustained application throughput. It can also help memory-bound decode while helping a compute-bound phase much less.
The numerical claims need their original boundaries:
| Repeated claim | What the strongest reviewed source actually supports | What remains unresolved |
|---|---|---|
HBM movement costs 3 to 4 pJ/bit |
A 2017 NVIDIA Research paper estimates about 3.97 pJ/bit for a complete HBM2 access in its modeled scope |
This is not a universal HBM link constant and should not be transferred unchanged to HBM3E or HBM4 |
Dense vertical I/O costs about 0.5 pJ/bit |
A separate research interface reports 0.65 pJ/bit in its own measured test-chip scope |
It does not prove total DRAM-access energy, package energy, or a commercial memory-on-logic product |
DRAM starts losing bits above 85°C |
Higher temperature can reduce retention margin and increase refresh or reliability pressure | Micron's current HBM3E brief specifies an operating range through 105°C; 85°C is not a universal failure cliff |
Qualcomm has 18x and 54x more bandwidth |
Qualcomm publishes 133 TB/s effective memory bandwidth per card for AI250 and describes 18x and 54x generation comparisons against its AI200 baseline |
These are future vendor targets for effective bandwidth; HBC Gen 1 commercial sampling is expected in mid-2027 |
| Qualcomm proves HBM is obsolete | Qualcomm positions HBC for high-capacity, memory-bound inference and decode | No shipping HBC system, independent benchmark, physical-bandwidth disclosure, yield result, or matched HBM replacement receipt is public |
| d-Matrix already uses stacked DRAM under compute | d-Matrix's current Corsair architecture is SRAM-based digital in-memory compute; its later Raptor program targets 3D DRAM, and the company says Pavehawk test silicon was validated in its labs | The future commercial product, manufacturing yield, full software path, independent performance, and HBM comparison remain unproven |
| Samsung has already bonded HBM directly onto a GPU | Samsung publicly documents HBM4, logic base dies, custom-HBM direction, and hybrid-bonding research | The exact primary artifact for a shipping Samsung HBM stack bonded directly over a GPU compute die was not found in the reviewed sources |
This produces a more accurate replacement map:
standard HBM
-> wider HBM plus more capable logic base dies
-> custom HBM with bounded customer-specific functions
-> near-memory compute beside or beneath high-capacity memory
-> memory-on-logic with much denser vertical connections
-> in-memory compute that removes selected data movement
That is not a countdown to HBM's disappearance. These architectures can coexist. Standard HBM can remain the best hot tier while custom HBM removes a bounded movement, near-memory compute owns a narrow phase, and a capacity tier holds state that does not deserve expensive local bandwidth.
Any proposed HBM replacement must disclose the same comparison packet:
same model, weights, precision, batch, sequence, and quality rule
+ physical capacity and physical pin bandwidth
+ useful and effective bandwidth with the derivation shown
+ bytes read, written, avoided, and moved across each boundary
+ p50, p99, sustained throughput, and failure rate
+ card and rack power, temperature, refresh, throttling, and cooling scope
+ package topology, repair, yield, qualification, and software coverage
+ delivered-system cost and constrained supply
= a replacement claim that can be evaluated
Without that packet, closer memory, effective bandwidth, and bandwidth per watt are research or vendor signals. They are not proof that a technology replaces HBM.
The Touchdown view is not that HBM has failed. HBM is exceptional at the role it was built for. The research question is whether explicit, composable movement and state primitives can put each byte at the cheapest physical boundary that still meets correctness and latency. Software, kernels, controllers, DPUs, packages, custom base dies, and new memory devices are all candidate implementation levels.
The proof rule never changes:
same model and revision
same Hermes task and repository
same verifier and quality rule
same latency and reliability target
same accounting boundary
different placement, precision, primitive, or hardware
-> compare accepted tasks, useful/physical bytes, tail latency,
energy, heat, failures, constrained capacity, and total cost
What each reader should take into the next section
- Student or intern: Picture one state object moving through a hierarchy. Ask where it lives, who can read it, how long it remains useful, and what physical boundary a read crosses.
- Software engineer: Stabilize prompt, repository, model, tokenizer, tenant, and tool identity before calling reuse a cache hit. Instrument the CPU tool loop as carefully as GPU decode.
- Kernel engineer: Join source operation, compiler path, executable artifact, launch, cache/HBM/fabric counters, correctness, and accepted output. A peak number is not a bottleneck diagnosis.
- Infrastructure engineer: Keep NVLink-C2C, NVLink/NVSwitch, PCIe/CXL, RDMA, and scale-out traffic separate. Capture topology, degraded state, queueing, and restore deadlines.
- Memory or package engineer: Follow the bit through array, TSV, bond, base die, package, PDN, thermal path, test, repair, and qualification. Do not let a system aggregate hide the component boundary.
- CTO: Decide which experiment is reversible before committing to a model, engine, topology, cache tier, or custom-silicon path.
- CFO: Price occupied capacity and failed work, not theoretical accelerator throughput. Separate capital, energy, cooling, water, support, and engineering assumptions.
- CEO or investor: Ask what receipt connects the technical advantage to accepted product output, and which supplier, qualification, software, power, and cooling dependencies can block it.
This section is the bridge. The remaining article keeps descending into the memory technologies, movement policies, facility physics, manufacturing constraints, and falsification tests that make the bridge real.
Primary sources for this system bridge
- [OFFICIAL NVIDIA PRODUCT ARCHITECTURE] Inside the NVIDIA Vera Rubin Platform. Vera LPDDR5X, coherent NVLink-C2C, Rubin HBM4, NVLink 6, and published device architecture.
- [OFFICIAL NVIDIA PRODUCT AND ROADMAP ARCHITECTURE] NVIDIA Vera Rubin POD. NVL72, current MGX, CMX/STX, NVL576, Kyber NVL144, Feynman Kyber NVL1152, serviceability, power, and cooling direction.
- [OFFICIAL NVIDIA CPU WORKLOAD EXPLANATION] NVIDIA Vera CPU Sets a New Standard for Agentic Workloads. CPU sandbox, tool, retrieval, processing, scheduling, and orchestration roles.
- [OFFICIAL NVIDIA CONTEXT-TIER ARCHITECTURE] BlueField-4-Powered CMX Context Memory Storage. CMX, BlueField-4, NIXL, Dynamo, DOCA Memos, Spectrum-X, and vendor performance targets.
- [OFFICIAL NVIDIA POWER ARCHITECTURE] Building the 800 VDC Ecosystem. Kyber power-delivery direction; no C-001 energy claim.
- [VENDOR HBM4 PRODUCT] Micron HBM4 for Vera Rubin. 12-high volume-production statement and 16-high sample statement.
- [VENDOR HBM4 PRODUCT AND HBM4E SAMPLE] Samsung commercial HBM4 and Samsung HBM4E samples. Vendor production and sample states.
- [VENDOR HBM4E SAMPLE] SK hynix 12-layer HBM4E sample. Sample shipment and vendor specifications.
- [VENDOR CUSTOM-HBM ARCHITECTURE] Marvell custom HBM compute architecture. Public custom base-die, controller, package, and interface design direction.
- [OFFICIAL FORWARD-LOOKING ROADMAP] Qualcomm Dragonfly and HBC. Vendor targets and expected sample dates, not shipping HBC proof.
- [OFFICIAL FORWARD-LOOKING PRODUCT PAGE] Qualcomm Dragonfly AI250. Card and rack capacity, effective-bandwidth, power, and decode-positioning claims remain future vendor targets.
- [OFFICIAL COMPANY ROADMAP AND LAB-VALIDATION CLAIM] d-Matrix and Alchip 3D DRAM announcement. Separates current SRAM-based Corsair from the future Pavehawk and Raptor 3D-DRAM program.
- [PEER-REVIEWED MODELED HBM2 ACCESS ENERGY] Fine-Grained DRAM: Energy-Efficient DRAM for Extreme Bandwidth Systems. The approximately
3.97 pJ/bitvalue is scoped to the paper's HBM2 access model. - [MEASURED RESEARCH INTERFACE] A 0.65-pJ/bit 3.6-TB/s/mm I/O Interface. A test-chip interface result, not a total memory-system or commercial-product result.
- [VENDOR PRODUCT BRIEF] Micron HBM3E product brief. Operating-temperature specification used to reject a universal
85°Cfailure cliff. - [PEER-REVIEWED MODELED MEMORY-ON-LOGIC STUDY] 3D Stacked HBM and Compute Accelerators for LLM. Configuration, thermal, and power-delivery research, not a shipping-system receipt.
- [OFFICIAL HUAWEI ROADMAP, CHINESE] Huawei Ascend roadmap keynote. HiBL/HiZQ workload positioning and vendor specifications; supply and independent performance remain unknown.
- [OFFICIAL CXMT PRODUCT SITE] CXMT products. DDR and LPDDR are listed; an official HBM product row was not found in the reviewed site.
How do the AMD MI400 Series, MI455X, HBM4, Venice, UALink, and Helios form one rack-scale system?
In plain English. Venice is the CPU side of the rack. MI455X is the accelerator. HBM4 is its local working memory. ROCm is the AMD software path that turns framework operations into GPU work. UALink or UALink over Ethernet connects GPUs for scale-up, while Vulcano and Ultra Ethernet serve scale-out roles. Salina handles bounded infrastructure work. Helios is the reference rack that combines these layers. A production announcement and peak specification still do not prove one Touchdown workload ran.
Publication state: integrated additive architecture-only lane.
run_idis null. The release candidate is not deployed.
The previous NVIDIA section follows one accepted coding task across Vera, Rubin, HBM4, NVLink, BlueField, CMX, power, cooling, and verification. AMD needs the same treatment. A developer does not buy an MI455X, an HBM4 stack, or a UALink cartridge. The developer asks an agent to inspect a repository, change code, run tools and tests, repair failures, and return one accepted patch.
If you searched for MI4100, stop at the name before trusting any number. No reviewed official AMD source establishes an MI4100 product. AMD uses MI400 Series for the family and MI455X for the launched CDNA 5 accelerator inside Helios. Older MI450 Series, MI450 architecture, and MI450X labels remain attached to their exact sources. Their relationship is not public.
request and repository state
-> Venice CPU orchestration, tokenization, tools, and scheduling
-> route, cache, and placement decision
-> MI455X prefill, attention, MoE, and KV creation
-> HBM4 reads and writes
-> UALink-over-Ethernet scale-up when state or experts cross GPUs
-> Vulcano / Ultra Ethernet scale-out when work crosses rack boundaries
-> Salina DPU for bounded network, storage, security, and state-I/O work
-> CPU sandbox and verifier
-> accepted patch or another paid attempt
July 23, 2026 launch correction. AMD's official Advancing AI keynote displayed AMD HELIOS above the status IN PRODUCTION TODAY, and Lisa Su said Helios is “in full production.” AMD described the MI455X enhanced accelerator module as a production module, said shipments are on track to start at the end of Q3, and said the ramp continues into Q4. AMD's same-day MI400 launch page and Helios launch page replace the older pre-launch product-state and bandwidth fields. MI455X product identity and Helios production state are now official current. That does not mean all customer shipments were delivered today.
Evidence boundary. Helios is still an AMD reference design, not a product for sale directly by AMD: OEM and ODM partners build the branded systems. Production status, shipment timing, product form, launch specifications, ROCm qualification, and workload execution are separate claims. The same-day launch sources establish a launched product, a production reference-design system, and published peak ceilings. They do not establish a universal orderable AMD rack SKU, a Touchdown GLM-5.2 or Wan2.2 run, customer price, MI455X TBP, sustained HBM traffic, UALoE p99, rack energy per task, production yield, or an accepted Touchdown result. The older
MI450-001engineering-projection footnote remains attached to the older 19.6 TB/s brochure snapshot and its performance comparisons; it does not override the July 23 launch specification.
AMD terms used in this section
| Term | Plain-language meaning |
|---|---|
| OAM | OCP Accelerator Module, a standardized accelerator-module form used by products such as MI355X |
| EAM | AMD's enhanced accelerator module label for the MI455X form described in the Helios launch |
| XCD | Accelerator Complex Die, one compute chiplet in an AMD Instinct package |
| CU | Compute Unit, AMD's repeated GPU execution block |
| LDS | Local Data Share, fast on-chip memory shared by work-items in a workgroup |
| MFMA | Matrix Fused Multiply-Add, an AMDGPU instruction family used for matrix work |
| ROCr and HSA | ROCr is ROCm's low-level runtime; HSA supplies the heterogeneous queue, memory, and execution model it exposes |
| COMGR and HSACO | COMGR manages AMD GPU compilation artifacts; an HSACO is an HSA code object containing target-specific executable code and metadata |
| UALink and UALoE | UALink is the scale-up interconnect contract; UALoE is AMD's UALink-over-Ethernet path for the Helios rack |
| Vulcano 800 AI NIC | AMD Pensando's named 800 Gb/s-per-NIC path for scale-out and scale-across networking; AMD describes up to three NICs per GPU and therefore up to 2.4 Tb/s per GPU as a vendor-published ceiling |
| Pollara 400 AI NIC | AMD Pensando's 400 Gb/s AI NIC for extending current Ethernet clusters; it is an AI NIC, not the Salina DPU |
| Salina DPU | AMD Pensando's front-end DPU for bounded network, storage, security, encryption, integrity, telemetry, and DPU-managed NVMe work |
| VAST AI Operating System | VAST Data's storage, data, and event-driven software platform; in the cited AMD test, a VAST flash partition is one remote home for reusable KV blocks |
| OEM and ODM | Partners that turn AMD's reference design into branded, orderable systems with their own final bill of materials, firmware, service, and qualification |
CDNA 4 is the concrete baseline
MI355X is a current CDNA 4 OAM accelerator. AMD publishes 256 compute units, 1,024 matrix cores, 16,384 stream processors, 160 KB LDS per CU, 256 MB last-level cache, 185 billion transistors, 288 GB HBM3E, 8 TB/s of peak HBM bandwidth, 1,400 W TBP, direct-liquid cooling, and 10.1 PFLOPS MXFP4. Its compiler target is gfx950.
The public physical path is:
PyTorch / vLLM / SGLang
-> ROCm and HIP
-> AITER, Composable Kernel, Triton, hipBLASLt, or rocBLAS
-> CDNA 4 wavefronts and matrix instructions
-> registers, LDS, cache, and XCDs
-> package Infinity Fabric and I/O dies
-> HBM controller
-> eight 36 GB HBM3E stacks
That does not mean each kernel receives 8 TB/s. Useful bandwidth still depends on layout, concurrency, channel balance, bank behavior, cache reuse, fusion, communication, power, and the actual operation.
ROCm is the memory software stack, not a PyTorch checkbox
Seeing torch.version.hip proves that a PyTorch build knows about AMD's HIP platform. It does not tell you which operator library ran, which GPU executable was dispatched, which HBM counters moved, or whether the final patch or clip passed. This section follows those layers separately.
PyTorch is one framework entry point. It does not identify the allocator, queue, selected operator, generated device object, collective, physical movement, profiler interval, or management receipt. A real AMD walkthrough must keep the complete path visible:
framework and serving:
PyTorch / vLLM / SGLang / workload repository
operator and kernel selection:
AITER / Composable Kernel / Triton AMD
rocBLAS / hipBLASLt / MIOpen / sparse / FFT / solver / random / tensor libraries
compiler and executable identity:
hipcc or clang -> LLVM AMDGPU -> COMGR -> AMDGPU code object / HSACO
dispatch and memory:
HIP runtime -> ROCr / HSA queues -> amdgpu driver
allocation, copies, streams, events, page state, kernels, registers, LDS, cache, HBM
collectives and movement:
RCCL / rocSHMEM / MoRI / UCX where the pinned workload actually selects them
package or node links -> UALink or UALoE scale-up -> Vulcano / Ultra Ethernet scale-out
evidence and operations:
rocprofiler SDK / rocprofv3 / ROCm Systems Profiler / ROCtx
AMD SMI / RAS / topology / firmware / clocks / power / temperature
media:
rocDecode / rocJPEG only when ingest or output processing selects them
Each name answers a different question. torch.version.hip can establish a framework build identity. It cannot establish that AITER replaced an ATen fallback, that a particular HSACO was dispatched, that RCCL moved bytes across a named link, that HBM controllers sustained useful traffic, or that the accepted result consumed a measured amount of energy.
The matrix below is the source-bounded AMD memory-software packet used by the interactive trace. Available means the component and its documented role exist. Walkthrough role says where C-001 or V-001 could select it. Observed remains false until one pinned run joins the source, executable artifact, dispatch, counters, output, verifier, power interval, and run_id.
| Component and branch | Layer | Memory role | Walkthrough role | Platform scope | Coverage and evidence | Exact next proof |
|---|---|---|---|---|---|---|
| ROCm platform and compatibility matrix rocm_hip | platform release, driver, firmware, operating-system, and user-space compatibility | Defines the version envelope in which HBM allocations and device execution can be attributed to an AMD runtime. | C-001: identity, prefill, decode, kv_state V-001: identity, latent_prepare, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: support_must_be_queried | parser_only official_current · not_observed | bash -lc 'rocminfo > rocminfo.txt && hipconfig --full > hipconfig.txt && amd-smi version > amd-smi-version.txt'official source |
| HIP runtime and programming model rocm_hip | device runtime, allocations, streams, events, launches, graphs, and peer access | Owns device allocation and copy APIs that may place or move model state and intermediate tensors in HBM. | C-001: identity, prefill, decode, kv_state V-001: identity, latent_prepare, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'rocprofv3 --hip-trace --memory-copy-trace --kernel-trace --output-directory hip-trace -- ./fixed-workload'official source |
| PyTorch on ROCm rocm_hip | framework tensor, ATen, autograd, distributed, and compilation entry | Creates the framework-visible tensors and caches later lowered into AMD runtime allocations and kernels. | C-001: prompt_context_ingest, prefill, decode, kv_state, tool_loop V-001: prompt_encode, latent_prepare, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | python3 -c "import json,torch; print(json.dumps({'torch':torch.__version__,'hip':torch.version.hip,'devices':[torch.cuda.get_device_name(i) for i in range(torch.cuda.device_count())]},indent=2))"official source |
| ROCr and HSA runtime rocm_hip | queue, signal, agent, executable loading, and low-level runtime | Binds executable queues and signals to device agents and memory pools below HIP. | C-001: identity, prefill, decode V-001: identity, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'rocprofv3 --hsa-trace --kernel-trace --memory-copy-trace --output-directory hsa-trace -- ./fixed-workload'official source |
| AITER inference operator library math_kernel | attention, MLA, paged attention, MoE, GEMM, normalization, RoPE, quantization, sampling, and communication-aware operators | May read weights and KV pages, write activations and KV state, and allocate operator workspaces in HBM. | C-001: prefill, decode, kv_state V-001: denoise_attention, denoise_mlp | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'git -C "$AITER_SRC" rev-parse HEAD > aiter-revision.txt && rocprofv3 --kernel-trace --memory-copy-trace --output-directory aiter-trace -- "$WORKLOAD_RUNNER"'official source |
| Composable Kernel and CK Tile math_kernel | templated HIP kernels, tile programming, examples, instances, and profiler clients | Defines tiled reads, writes, LDS staging, and HBM-facing kernel layouts for covered operators. | C-001: prefill, decode V-001: denoise_attention, denoise_mlp, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'git -C "$ROCM_LIBRARIES_SRC" rev-parse HEAD > rocm-libraries-revision.txt && "$CK_PROFILER" gemm "$CK_GEMM_ARGS" | tee ck-profile.txt'official source |
| hipBLASLt math_kernel | descriptor-driven GEMM, heuristics, epilogues, tuning, and solution selection | Reads matrix operands and scale metadata from HBM, uses workspace, and writes GEMM outputs to HBM. | C-001: prefill, decode V-001: prompt_encode, denoise_mlp, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$HIPBLASLT_BENCH" $HIPBLASLT_ARGS 2>&1 | tee hipblaslt-bench.txt'official source |
| rocBLAS math_kernel | BLAS operations and reference GEMM baseline | Reads dense matrix and vector operands from HBM and writes BLAS results, with optional workspace. | C-001: prefill, decode V-001: prompt_encode, denoise_mlp, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'rocblas-bench -f gemm -r f32 --transposeA N --transposeB N -m 4096 -n 4096 -k 4096 --alpha 1 --beta 0 | tee rocblas-bench.txt'official source |
| MIOpen math_kernel | deep-learning primitives, convolutions, normalization, fusion, and solution selection | May read feature maps and weights from HBM, allocate workspace, and write convolution or normalization outputs. | C-001: V-001: denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'MIOpenDriver conv -n 1 -c 64 -H 224 -W 224 -k 64 -y 3 -x 3 -p 1 -q 1 -F 1 -V 1 | tee miopen-driver.txt'official source |
| Triton AMD backend math_kernel | tile-language compilation, scheduling, and AMD target lowering | Generated kernels define global-memory tile loads and stores that may map to HBM traffic. | C-001: prefill, decode V-001: denoise_attention, denoise_mlp, vae_decode | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only public_code · not_observed | bash -lc 'git -C "$TRITON_SRC" rev-parse HEAD > triton-revision.txt && TRITON_ALWAYS_COMPILE=1 python3 "$PINNED_TRITON_FIXTURE" 2>&1 | tee triton-run.txt'official source |
| rocWMMA math_kernel | wave-level matrix-fragment API and matrix-core programming | Loads operand fragments from HBM through cache and LDS and writes matrix results back to device memory. | C-001: prefill, decode V-001: denoise_mlp | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'git -C "$ROCM_LIBRARIES_SRC" rev-parse HEAD > rocm-libraries-revision.txt && "$ROCWMMA_SAMPLE" | tee rocwmma-sample.txt'official source |
| hipcc and amdclang++ compiler_artifact | offline HIP compilation driver and compiler frontend | Lowers source memory operations and target flags into device code that later issues cache and HBM transactions. | C-001: compile, prefill, decode V-001: compile, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'hipcc --version > hipcc-version.txt && hipcc --offload-arch=gfx950 -O3 -save-temps "$HIP_SOURCE" -o fixed-kernel 2> compile.log'official source |
| HIPRTC compiler_artifact | runtime HIP source compilation | Produces runtime device code whose kernels may later read and write HBM-resident objects. | C-001: compile, prefill, decode V-001: compile, denoise | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$HIPRTC_FIXTURE" --arch gfx950 --dump-code-object hiprtc-output.hsaco 2>&1 | tee hiprtc.log'official source |
| LLVM AMDGPU backend compiler_artifact | LLVM target lowering, code generation, metadata, and AMDGPU ISA emission | Lowers address spaces, loads, stores, atomics, cache policy, and synchronization into target-specific device instructions. | C-001: compile, prefill, decode V-001: compile, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only public_code · not_observed | bash -lc 'llvm-objdump --mcpu=gfx950 --disassemble --source "$DEVICE_ARTIFACT" > amdgpu-disassembly.txt'official source |
| AMD COMGR, ROCm Device Libraries, and HSACO code objects compiler_artifact | device compilation support, linking, device libraries, metadata, and executable code-object packaging | Packages the device instructions and metadata for kernels that later operate on HBM-resident objects. | C-001: compile, prefill, decode V-001: compile, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'readelf -h -n -s "$DEVICE_ARTIFACT" > hsaco-readelf.txt && sha256sum "$DEVICE_ARTIFACT" > hsaco-sha256.txt'official source |
| RCCL collective_fabric | collective communication library for all-reduce, all-gather, reduce-scatter, all-to-all, broadcast, and point-to-point operations | Reads and writes collective buffers that may live in HBM and cross accelerator or node boundaries. | C-001: prefill, decode, expert_parallel, tensor_parallel V-001: denoise_attention, sequence_parallel, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'git -C "$RCCL_TESTS_SRC" rev-parse HEAD > rccl-tests-revision.txt && "$RCCL_TESTS_SRC/build/all_reduce_perf" -b 8 -e 8G -f 2 -g 8 | tee rccl-all-reduce.txt'official source |
| rocSHMEM collective_fabric | partitioned global address-space communication and device-initiated memory operations | May expose symmetric device buffers and remote operations involving HBM-resident data. | C-001: expert_parallel, tensor_parallel V-001: sequence_parallel | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'git -C "$ROCSHMEM_SRC" rev-parse HEAD > rocshmem-revision.txt && "$ROCSHMEM_FIXTURE" 2>&1 | tee rocshmem-run.txt'official source |
| MoRI, MoRI-IO, and MoRI expert-parallel communication collective_fabric | modular RDMA interface, prefill/decode state transfer, and expert dispatch/combine | May move KV blocks and expert-routing buffers between GPU HBM and RDMA-visible communication paths. | C-001: prefill, decode, kv_state_transfer, expert_parallel V-001: sequence_parallel | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'git -C "$MORI_SRC" rev-parse HEAD > mori-revision.txt && "$PINNED_MORI_RUNNER" 2>&1 | tee mori-run.txt'official source |
| Infinity Fabric, UALink or UALoE, and Ultra Ethernet boundary collective_fabric | physical scale-up and scale-out topology beneath communication software | Carries communication derived from HBM-resident tensors across accelerator, tray, rack, or cluster boundaries. | C-001: kv_state_transfer, expert_parallel, tensor_parallel V-001: sequence_parallel, vae_decode | mi355x: source_backed_candidate, mi455x_helios: source_backed_candidate | parser_only official_preliminary · not_observed | bash -lc 'amd-smi topology --show-weight > topology-weight.txt && amd-smi topology --show-hops > topology-hops.txt && amd-smi topology --show-link-type > topology-links.txt'official source |
| ROCprofiler-SDK and rocprofv3 profiler_telemetry | HIP, HSA, kernel, memory-copy, allocation, marker, counter, and communication tracing | Can observe allocation, copy, dispatch, and counter surfaces needed to attribute candidate HBM activity. | C-001: identity, prefill, decode, kv_state, tool_loop V-001: identity, latent_prepare, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'rocprofv3-avail > rocprofv3-available.txt && rocprofv3 --runtime-trace --kernel-trace --memory-copy-trace --marker-trace --output-format csv --output-directory rocprofv3-out -- "$WORKLOAD_RUNNER"'official source |
| ROCm Compute Profiler profiler_telemetry | kernel counters, roofline, memory analysis, occupancy, and baseline comparison | Can expose counters related to cache, HBM bandwidth, LDS, occupancy, and instruction mix for a selected kernel. | C-001: prefill, decode V-001: denoise_attention, denoise_mlp, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'rocprof-compute profile -n "$RUN_NAME" --format-rocprof-output csv -- "$WORKLOAD_RUNNER" && rocprof-compute analyze -p "./workloads/$RUN_NAME/$GPU_TARGET"'official source |
| ROCm Systems Profiler profiler_telemetry | CPU, thread, runtime, system, accelerator, and communication timeline | Can place HBM-facing kernels and copies in the same timeline as CPU scheduling, tools, storage, and network work. | C-001: prompt_context_ingest, prefill, decode, tool_loop, accepted_task V-001: prompt_encode, latent_prepare, denoise, vae_decode, accepted_clip | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'rocprof-sys-sample --output-path rocprof-sys-out -- "$WORKLOAD_RUNNER"'official source |
| AMD SMI telemetry profiler_telemetry | device inventory, clocks, power, temperature, memory use, topology, links, and health telemetry | Can report device-level memory allocation and health signals, but not which workload object produced the bytes. | C-001: identity, prefill, decode, tool_loop V-001: identity, latent_prepare, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'amd-smi version > amd-smi-version.txt && amd-smi metric --csv > amd-smi-metric.csv'official source |
| AMD SMI management and RAS controls management_ras | inventory, configuration, reset, process, firmware, error, topology, and reliability administration | Exposes device and memory health boundaries needed before treating an HBM result as valid. | C-001: preflight, identity, postflight V-001: preflight, identity, postflight | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'amd-smi static --asic --board --vbios --driver > amd-smi-static.txt && amd-smi metric --ecc --pcie --xgmi > amd-smi-ras.txt'official source |
| ROCm Validation Suite management_ras | system qualification, stress, memory, PCIe, peer, and GPU validation | Can exercise memory and platform health before workload-specific HBM claims are accepted. | C-001: preflight, postflight V-001: preflight, postflight | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'rvs -g > rvs-gpu-list.txt && rvs -c "$RVS_CONFIG" -l rvs-run.log'official source |
| AMD Instinct MI355X system acceptance guide management_ras | platform bring-up and acceptance tests for inventory, memory, fabric, power, cooling, and sustained operation | Defines the acceptance boundary that must pass before a workload-specific HBM receipt is trusted. | C-001: preflight, postflight V-001: preflight, postflight | mi355x: source_backed_candidate, mi455x_helios: not_applicable | parser_only official_current · not_observed | bash -lc 'sudo lspci -d 1002:75a3 > mi355x-pcie.txt && test "$(wc -l < mi355x-pcie.txt)" -eq 8'official source |
| rocDecode media | video decode API and hardware-assisted media ingest | May create decoded frame surfaces and staging buffers before preprocessing or model input. | C-001: V-001: input_decode, preprocess | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'git -C "$ROCDECODE_SRC" rev-parse HEAD > rocdecode-revision.txt && "$ROCDECODE_SAMPLE" "$PINNED_VIDEO" 2>&1 | tee rocdecode-run.txt'official source |
| rocJPEG media | JPEG decode and image ingest | May create decoded image surfaces and staging buffers before multimodal or video preprocessing. | C-001: multimodal_input V-001: input_decode, preprocess | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'git -C "$ROCJPEG_SRC" rev-parse HEAD > rocjpeg-revision.txt && "$ROCJPEG_SAMPLE" "$PINNED_IMAGE" 2>&1 | tee rocjpeg-run.txt'official source |
| rocAL media | accelerated data loading, decode, augmentation, and preprocessing pipeline | May allocate input batches, decoded surfaces, augmentation intermediates, and model-ready tensors. | C-001: multimodal_input V-001: input_decode, preprocess | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$ROCAL_FIXTURE" --input "$PINNED_MEDIA_MANIFEST" --output rocal-output 2>&1 | tee rocal-run.txt'official source |
| ROCm Performance Primitives media | image and tensor preprocessing primitives | May read decoded image or tensor batches, apply preprocessing, and write model-ready outputs. | C-001: multimodal_input V-001: preprocess, output_postprocess | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$RPP_FIXTURE" --manifest "$PINNED_IMAGE_BATCH" 2>&1 | tee rpp-run.txt'official source |
| ROCm 7.14 TheRock gfx1250 source-bring-up registry compiler_artifact | ROCm build and distribution target registry at tag therock-7.14 | A source target can make future HBM4-capable device code buildable, but it does not allocate HBM or establish a supported runtime. | C-001: source_bringup, compile_candidate V-001: source_bringup, compile_candidate | mi355x: source_backed_candidate, mi455x_helios: source_bringup_not_qualified | parser_only public_code · not_observed | bash -lc 'git -C "$THEROCK_SRC" checkout therock-7.14 && git -C "$THEROCK_SRC" rev-parse HEAD > therock-revision.txt && rg -n "gfx1250.*MI450/MI450X/MI455X" "$THEROCK_SRC/cmake/therock_amdgpu_targets.cmake" > therock-gfx1250.txt'official source |
| amdgpu, KFD, and GPU firmware boundary rocm_hip | kernel driver, compute-device interface, firmware loading, memory mapping, queues, and reset boundary | Owns the kernel-visible GPU memory, process, queue, page-mapping, fault, reset, and firmware boundary beneath ROCr and HIP. | C-001: preflight, allocation, dispatch, fault_recovery V-001: preflight, allocation, dispatch, fault_recovery | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'uname -a > kernel.txt && modinfo amdgpu > amdgpu-modinfo.txt && dmesg --level=err,warn | rg -i "amdgpu|kfd|firmware" > amdgpu-kfd-dmesg.txt || true'official source |
| rocminfo HSA agent and memory-pool inventory profiler_telemetry | HSA system, agent, cache, ISA, queue, and memory-pool enumeration | Reports the runtime-visible agents and memory pools required to distinguish a detected accelerator from an assumed one. | C-001: identity, preflight V-001: identity, preflight | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'rocminfo > rocminfo.txt && sha256sum rocminfo.txt > rocminfo.sha256'official source |
| hipBLAS portability wrapper math_kernel | BLAS portability interface and backend dispatch wrapper | Accepts matrix and vector operands, strides, layouts, and workspaces that may reside in HBM before dispatching to a backend. | C-001: prefill, decode, expert_compute V-001: prompt_encode, denoise, vae_decode | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$HIPBLAS_BENCH" $HIPBLAS_ARGS 2>&1 | tee hipblas-bench.txt'official source |
| hipTensor math_kernel | tensor contraction, permutation, reduction, and plan selection | Reads multidimensional tensors and metadata, may allocate workspace, and writes contracted or transformed tensors. | C-001: candidate_tensor_contraction V-001: candidate_tensor_contraction, denoise, vae_decode | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$HIPTENSOR_FIXTURE" --manifest "$HIPTENSOR_CASE" 2>&1 | tee hiptensor-run.txt'official source |
| hipSPARSE and rocSPARSE math_kernel | sparse matrix and vector portability interface plus AMD backend | Reads sparse values, indices, pointers, dense operands, and workspaces and writes sparse or dense outputs. | C-001: candidate_sparse_operator, expert_compute V-001: candidate_sparse_operator | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$ROCSPARSE_FIXTURE" --manifest "$SPARSE_CASE" 2>&1 | tee rocsparse-run.txt'official source |
| hipSPARSELt math_kernel | structured-sparse matrix multiplication, pruning, compression, plan, and algorithm selection | May store structured-sparse weights, compressed metadata, dense activations, workspace, and outputs in HBM. | C-001: candidate_structured_sparse_gemm, expert_compute V-001: candidate_structured_sparse_gemm | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$HIPSPARSELT_BENCH" $HIPSPARSELT_ARGS 2>&1 | tee hipsparselt-run.txt'official source |
| hipFFT and rocFFT math_kernel | FFT portability interface, plan generation, kernels, work buffers, and transforms | Reads signal tensors, twiddle or plan data, and workspace and writes frequency-domain or inverse-transform outputs. | C-001: not_selected_by_current_source V-001: candidate_frequency_transform | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$ROCFFT_RIDER" $ROCFFT_ARGS 2>&1 | tee rocfft-run.txt'official source |
| hipRAND and rocRAND math_kernel | random-number portability API, generators, distributions, states, and output buffers | May create random states and output tensors for sampling or latent initialization in device memory. | C-001: sampling_candidate V-001: latent_prepare_candidate | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$ROCRAND_FIXTURE" --manifest "$RNG_CASE" 2>&1 | tee rocrand-run.txt'official source |
| hipSOLVER and rocSOLVER math_kernel | dense and sparse linear-system and factorization portability API plus AMD backend | Reads matrices and solver metadata, uses workspaces and pivot buffers, and writes factors or solutions. | C-001: not_selected_by_current_source V-001: not_selected_by_current_source | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$ROCSOLVER_FIXTURE" --manifest "$SOLVER_CASE" 2>&1 | tee rocsolver-run.txt'official source |
| rocALUTION math_kernel | iterative sparse solvers, preconditioners, matrix formats, and host-device movement | May place sparse matrices, vectors, preconditioners, staging buffers, and solver state across host memory and HBM. | C-001: not_selected_by_current_source V-001: not_selected_by_current_source | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$ROCALUTION_FIXTURE" --manifest "$ROCALUTION_CASE" 2>&1 | tee rocalution-run.txt'official source |
| hipCUB and rocPRIM math_kernel | device and block primitives for scan, reduce, sort, select, partition, and memory operations | Reads and writes device ranges and temporary storage used by routing, sampling, indexing, sorting, and reduction paths. | C-001: routing_candidate, sampling_candidate, indexing_candidate V-001: reduction_candidate, indexing_candidate | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$ROCPRIM_FIXTURE" --manifest "$PRIMITIVE_CASE" 2>&1 | tee rocprim-run.txt'official source |
| rocThrust math_kernel | parallel algorithms, iterators, containers, scans, reductions, sorts, and transforms | May own device containers and temporary ranges for higher-level indexing, sorting, selection, transform, and reduction work. | C-001: routing_candidate, sampling_candidate, indexing_candidate V-001: indexing_candidate, postprocess_candidate | mi355x: source_backed_candidate, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$ROCTHRUST_FIXTURE" --manifest "$ROCTHRUST_CASE" 2>&1 | tee rocthrust-run.txt'official source |
| UCX transport boundary collective_fabric | communication framework and transport selection above network and memory registration | Can register and move buffers between local or remote memory domains, but it is not an HBM allocator, cache policy, or physical fabric. | C-001: kv_state_transfer_candidate, expert_parallel_candidate V-001: distributed_tensor_transfer_candidate | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only public_code · not_observed | bash -lc 'ucx_info -v > ucx-version.txt && ucx_info -d > ucx-devices.txt && "$UCX_FIXTURE" 2>&1 | tee ucx-run.txt'official source |
| hipFile and AMD Infinity Storage storage_kv | early-access direct-to-GPU storage I/O with synchronous, asynchronous, batch, and POSIX fallback paths | Can move file-backed state between storage and device memory while preserving a distinct fallback path through host I/O. | C-001: kv_offload_candidate, model_state_load_candidate V-001: model_state_load_candidate, latent_or_output_io_candidate | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_preliminary · not_observed | bash -lc 'ais-check --output ais-check.json && "$HIPFILE_FIXTURE" --manifest "$HIPFILE_CASE" 2>&1 | tee hipfile-run.txt'official source |
| ROCm AMD Infinity Context storage_kv | early-access disaggregated KV-cache inference stack across GPU memory, CPU DRAM, local NVMe, and NFS over RDMA | Defines a tiered KV-state architecture and test harness; it does not prove that C-001 selected it or that any tier moved bytes. | C-001: kv_lookup_candidate, kv_offload_candidate, prefill_decode_disaggregation_candidate V-001: not_applicable_to_diffusion_kv | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_preliminary · not_observed | bash -lc 'git -C "$AIC_SRC" rev-parse HEAD > aic-revision.txt && docker compose -f "$AIC_COMPOSE" config > aic-compose.txt && "$AIC_BENCH" --manifest "$C001_MANIFEST" 2>&1 | tee aic-run.txt'official source |
| vLLM, LMCache, and NIXL ROCm integration storage_kv | version-pinned serving, KV block management, and transfer integration inside the AIC technology preview | Separates the serving engine, cache identity and policy, and movement backend across GPU, CPU, local storage, and network-storage tiers. | C-001: prefill, decode, kv_lookup_candidate, kv_transfer_candidate V-001: not_applicable_to_diffusion_kv | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_preliminary · not_observed | bash -lc 'docker compose -f "$AIC_COMPOSE" config > integration-compose.txt && "$AIC_BENCH" --manifest "$C001_MANIFEST" --capture-kv-trace 2>&1 | tee integration-run.txt'official source |
| ROCm Data Center Tool management_ras | data-center GPU discovery, groups, monitoring, diagnostics, policy, health, and telemetry | Can collect device health and memory-related telemetry around a workload interval without proving object-level HBM traffic. | C-001: preflight, runtime_monitoring, postflight V-001: preflight, runtime_monitoring, postflight | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc 'rdci discovery -l > rdc-discovery.txt && rdci dmon -l > rdc-fields.txt && "$RDC_CAPTURE" --manifest "$WORKLOAD_INTERVAL" > rdc-capture.json'official source |
| TransferBench and ROCm Validation Suite boundary management_ras | simultaneous transfer benchmark versus broader platform validation and diagnostics | TransferBench measures configured copy paths; RVS checks system health. Neither proves a workload selected the path or that logical bytes equal HBM or wire bytes. | C-001: preflight_transfer_baseline, postflight V-001: preflight_transfer_baseline, postflight | mi355x: support_must_be_queried, mi455x_helios: not_public | parser_only official_current · not_observed | bash -lc '"$TRANSFERBENCH" "$TRANSFER_CONFIG" 2>&1 | tee transferbench-run.txt && rvs -c "$RVS_CONFIG" -l rvs-run.log'official source |
| Legacy ROCm-SMI, profiler, and RBT negative guard management_ras | fail-closed routing away from legacy ROCm-SMI, old profiler entry points, and the ROCm Bandwidth Test | Prevents stale tool output from being treated as current AMD SMI, rocprofv3, ROCm profiler, or TransferBench evidence. | C-001: preflight_negative_guard V-001: preflight_negative_guard | mi355x: not_applicable, mi455x_helios: not_applicable | parser_only official_current · not_observed | bash -lc 'for tool in rocm-smi rocprof rocprofv2 rocm-bandwidth-test amd-smi rocprofv3 TransferBench; do command -v "$tool" || true; done > tool-routing.txt'official source |
For C-001 Hermes plus GLM-5.2, the expected inspection path is:
model and engine identity
-> HIP allocation and stream identity
-> selected attention, GEMM, MoE, normalization, or sampling operator
-> AMDGPU target and HSACO digest
-> dispatch geometry and kernel name
-> HBM allocation, read/write counters, cache behavior, and stalls
-> RCCL / rocSHMEM / MoRI only if the placement plan communicates
-> CPU tool window and verifier
-> accepted patch, latency, energy, and cost under one run_id
For V-001 Wan2.2, the expected inspection path is different:
prompt, model revision, latent contract, and dtype
-> HIP allocations for weights, latent state, transient Q/K/V, activations, and workspaces
-> selected attention, convolution, normalization, scheduler, and VAE operations
-> AMDGPU target, HSACO digests, and repeated denoising dispatches
-> HBM traffic and allocation high-water mark across the denoising timeline
-> RCCL collective and rank map only if the declared parallel plan communicates
-> rocDecode or rocJPEG only if the declared media path actually uses it
-> accepted clip, quality rule, latency, energy, and cost under a different run_id
The catalog deliberately includes libraries that may be available but absent from both traces. Package presence is not execution. Import success is not dispatch. A microbenchmark is not an accepted coding task or video. A profiler capture without synchronized workload and verifier identity is not a business receipt.
The current MI455X software evidence has one important split:
public source bring-up:
TheRock maps gfx1250 to MI450 / MI450X / MI455X
several ROCm 7.14 components contain gfx1250 source or changelog entries
RCCL contains an MI455X performance-test configuration
published qualification:
the ROCm 7.14 hardware-support table still stops at MI350 / MI355X gfx950
TheRock's supported-GPU table does not list gfx1250
AITER's published hardware table still stops at MI355X
MoRI marks the MI450X family path as work in progress
ROCm Infinity Context labels Helios / MI455X as upcoming
local observation:
no selected MI455X operator
no captured gfx1250 HSACO or disassembly
no dispatch, HBM counter, fabric trace, power interval, output, or run_id
AMD's Helios page also uses Day-0 support and production-ready AI performance language for the software ecosystem. That is a vendor platform direction, not a component-level release receipt. The trace therefore labels MI455X software source bring-up, not qualified, not selected, and not observed until the release table, exact package set, hardware, and workload artifacts agree.
MI455X changes the memory and system boundary
The headline change is straightforward: one MI455X exposes more local HBM capacity and a much higher published peak HBM bandwidth than the MI355X baseline. That creates more room for weights, active state, batching, and workspaces. It does not predict application speed because kernels, collectives, software support, power, and the workload can still become the bottleneck.
AMD currently publishes these MI455X and Helios launch specifications. Product, production, and launch-specification states are current. Peak compute, memory-bandwidth, scale-up, and scale-out fields are still vendor-published ceilings, not measured workload results:
| Boundary | Published value | Evidence state |
|---|---|---|
| Product identity | MI455X / CDNA 5 | official current launch |
| MI455X module state | production enhanced accelerator module | official current launch statement |
| Helios production state | in full production on July 23, 2026 | official current launch statement |
| Shipment state | on track to start at the end of Q3 and ramp into Q4 2026 | official forward-looking schedule |
| HBM4 per GPU | 432 GB | official current launch specification |
| Peak HBM bandwidth per GPU | 23.3 TB/s | official current launch specification; peak ceiling |
| Transistors per GPU | 320 billion | official current launch specification |
| Peak OCP MXFP4 per GPU | 40 PFLOPS | official current launch specification; theoretical peak |
| Peak OCP MXFP8 per GPU | 20 PFLOPS | official current launch specification; theoretical peak |
| GPUs per Helios rack | 72 across 18 four-GPU compute trays | official current launch specification |
| Rack HBM4 | 31 TB | official current launch specification |
| Aggregate peak rack HBM bandwidth | 1.7 PB/s | official current launch specification; peak ceiling |
| Peak rack OCP MXFP4 | 2.9 EFLOPS | official current launch specification; theoretical peak |
| Peak rack OCP MXFP8 | 1.4 EFLOPS | official current launch specification; theoretical peak |
| Aggregate scale-up bandwidth | 260 TB/s | official current launch specification; peak ceiling |
| Aggregate scale-out bandwidth | 43 TB/s | official current launch specification; peak ceiling |
The June brochure and the product page captured before the launch used 19.6 TB/s per MI455X. Multiplying that older field by 72 produced the old 1.4112 PB/s Touchdown arithmetic. Both values remain useful only as a dated pre-launch snapshot. The July 23 launch values that govern this article are 23.3 TB/s per MI455X and 1.7 PB/s aggregate peak per Helios rack.
The direct CDNA 4 to CDNA 5 arithmetic is:
HBM capacity:
432 / 288 = 1.50x
HBM bandwidth:
23.3 / 8.0 = 2.91x
FP4 peak:
40 / 10.1 = 3.96x
primary GPU domain:
72 / 8 = 9x as many GPUs
rack HBM peak reconciliation:
432 GB * 72 = 31,104 GB = 31.104 decimal TB
AMD publishes the rounded rack capacity headline as 31 TB
72 * 23.3 TB/s = 1,677.6 TB/s = 1.6776 PB/s
AMD publishes the rounded rack headline as 1.7 PB/s
The capacity is a vendor-published product total, and the bandwidth is a vendor-published peak ceiling. The arithmetic does not reveal HBM stack count, stack height, supplier, reserved capacity, sustained traffic, or application speedup. CDNA 5 compute grows faster than memory capacity and bandwidth. A weak kernel or exposed collective can strand more peak arithmetic than before.
AMD also prints a 10x performance increase versus MI355X headline. The brochure footnote bounds that claim to engineering projections: a future MI400 Series design versus MI355X using an MoE inference model with 2K and 16K prefill under TP8 and EP8, plus projected training improvements for GEMM and attention. A separate footnote compares the theoretical dense MXFP4 peak of a 72-MI455X Helios rack with an eight-MI355X platform. Neither is a universal 10x application result.
What is inside the Helios reference rack?
Think of the rack as six connected responsibilities: CPU control, GPU compute, local HBM, GPU-to-GPU scale-up, rack-to-rack scale-out, and power/cooling/service. The partner that delivers the final system must turn AMD's reference design into one qualified configuration with exact parts, firmware, topology, support, and facility requirements.
AMD describes an Open Rack Wide system built from MI455X GPUs, 6th Gen EPYC Venice CPUs, Vulcano 800G AI NICs, Salina DPUs, four UALink-over-Ethernet scale-up cartridges, central power shelves, a vertical busbar, and direct-liquid cooling.
host and control:
6th Gen EPYC Venice
up to 256 CPU cores and 1.6 TB/s CPU-memory bandwidth
accelerator hot tier:
72 MI455X GPUs across 18 four-GPU compute trays
31 TB HBM4 and 1.7 PB/s aggregate peak HBM bandwidth per rack
scale-up:
UALink or UALink over Ethernet
four scale-up cartridges in the reference architecture
scale-out and offload:
Pensando Vulcano 800 Gb/s AI NIC path
Pensando Salina DPU role named in the Helios brochure
mechanical, power, and cooling:
double-wide Open Rack Wide
central power shelves and vertical busbar
liquid manifold and quick-disconnect service boundaries
The product page makes the scope explicit: this is a partner blueprint. OEMs and ODMs can turn it into branded systems, so the final tray population, NIC and DPU count, firmware bundle, rack power, cooling inputs, service contract, price, and qualification result belong to the delivered partner configuration.
The published network, offload, security, and serviceability claims also need separate scopes:
| Boundary | Published statement | What remains unproven |
|---|---|---|
| Scale-up cartridges | four cartridges; UALink over Ethernet; up to 72 GPUs; 260 TB/s aggregate | message latency, switch path, collective mapping, retries, congestion, useful application bandwidth |
| Vulcano AI NIC | 800 Gb/s Ethernet per named NIC; brochure also says up to 2.4 Tb/s of scale-out bandwidth per GPU | exact NIC count and topology, how the per-NIC, per-GPU, and 43 TB/s rack figures reconcile, delivered throughput |
| Helios scale-out | 43 TB/s aggregate peak | endpoint count, traffic class, oversubscription, p95/p99, failure recovery |
| Salina DPU | network, security, storage, encryption, integrity, and telemetry offload | final rack population, workload-selected function, bytes, latency, power, accepted-work effect |
| Salina projected limits | 400 Gb/s bandwidth, 10M connections/s, 100M packets/s, 400 Gb/s encryption offload, 4M storage IOPS in the brochure footnote | final silicon, Helios integration, customer configuration, matched-workload result |
| Security | hardware root of trust, continuous attestation, isolation, device identity, encrypted memory and interconnect claims | exact trust chain, key ownership, cipher boundary, attestation evidence, overhead, tenant policy |
| Serviceability | integrated power, cooling, and networking connections intended to avoid recabling during sled replacement | measured replacement time, failure isolation, spare policy, leak handling, uptime |
The important point is not tray count alone. Helios exposes several physically different paths:
| Path | Intended role | What it is not |
|---|---|---|
| MI455X HBM4 | active weights, active KV, activations, workspaces | pooled cold storage |
| Venice DDR | CPU work, metadata, warm state, staging | local HBM4 |
| Infinity Fabric | CPU-GPU or package/node connectivity where supported | rack-wide persistent storage |
| UALink over Ethernet | GPU scale-up and collective traffic | NVMe or object storage |
| Vulcano / Ultra Ethernet | AI scale-out | local GPU memory |
| Salina DPU | network, storage, security, encryption, integrity, telemetry, bounded transfer execution | dense tensor compute |
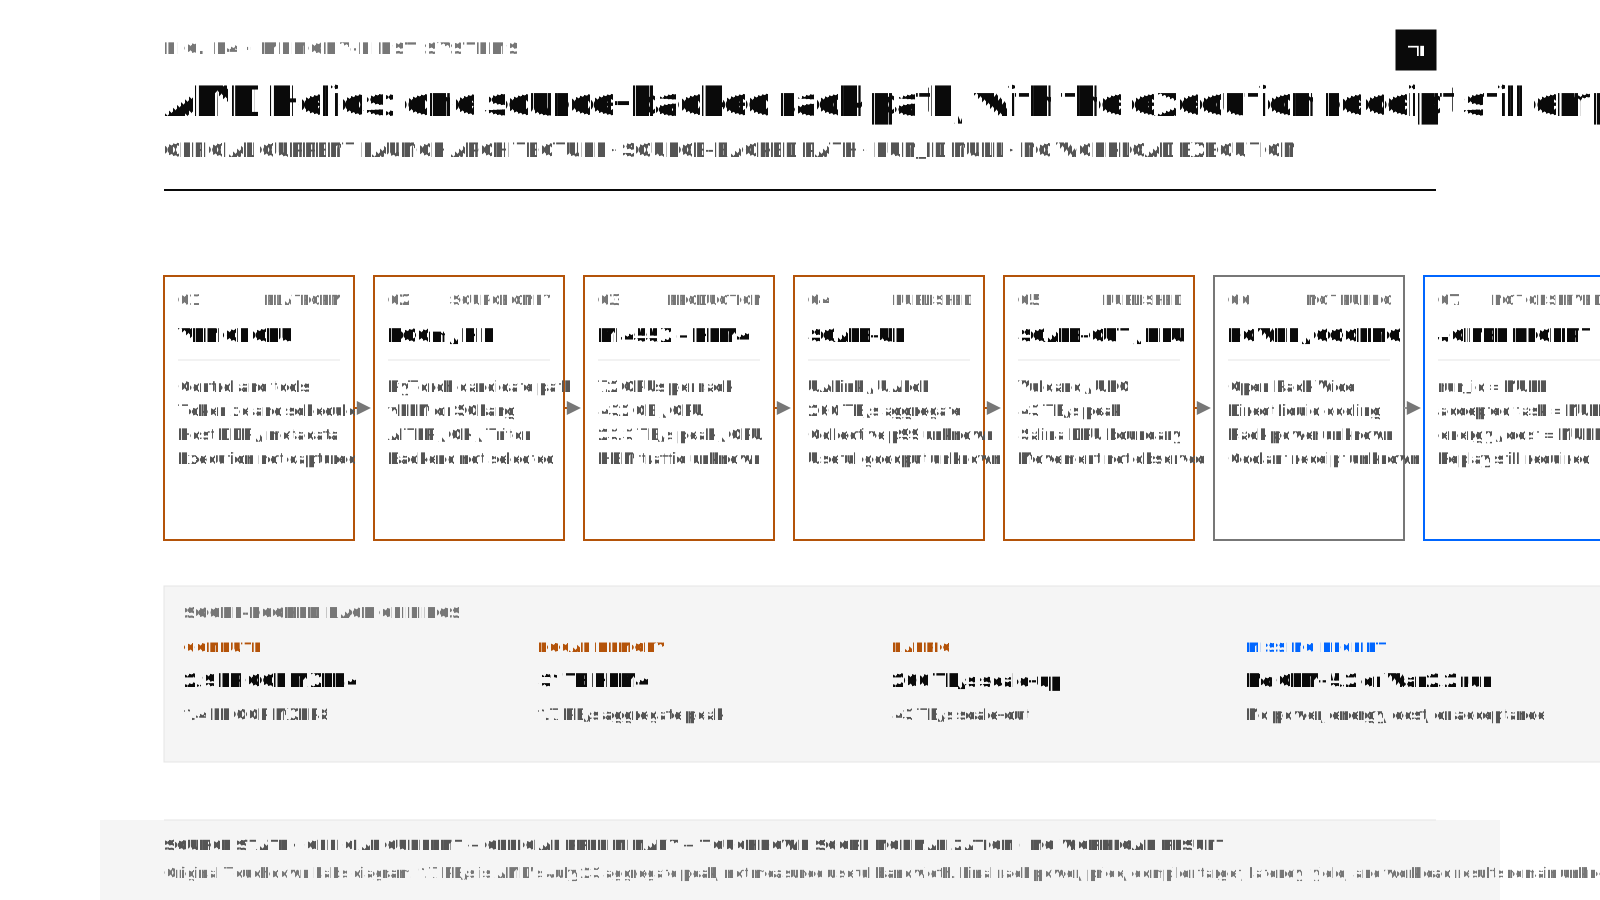
The HBM4 package is a pressure point, not a disclosed stack map
AMD publishes up to 432 GB HBM4 for MI455X. That total does not establish the exact stack count, stack height, package organization, supplier mix, qualification, yield, or customer allocation. Those fields remain not public until an AMD package disclosure, qualified product document, or physical analysis proves them.
HBM4 doubles the external stack interface from the 1,024-bit HBM3-class boundary to 2,048 bits. More wires buy bandwidth, but increase the pressure on:
base-die logic
microbump or bonding density
package routing
power delivery
signal integrity
warpage
thermal extraction
known-good-die test
stack and package yield
The base die becomes more strategic because advanced logic can support PHY, repair, telemetry, RAS, security, power management, address mapping, remapping, and possible customer-specific movement functions. It also adds area, heat, verification, process, yield, and lock-in cost.
AMD and Samsung announced an HBM4 supply direction for MI455X. That is evidence of collaboration and intent. It is not evidence of final volume allocation, price, yield, or customer qualification.
UALink bandwidth is not MoE latency
Peak bandwidth describes how much data a link can move under a declared scope. MoE latency asks how quickly small, uneven expert-routing messages finish, especially at the slow tail. Those are different measurements.
Helios publishes 260 TB/s of rack scale-up bandwidth. That does not answer the most important inference questions:
64-byte to 4-KB message latency
all-to-all p99
expert-dispatch jitter
barrier cost
incast behavior
congestion control
retransmission
collective setup
failure recovery
MoE inference can send small, bursty, skewed messages. Decode is latency sensitive. A fabric can deliver excellent large-transfer bandwidth and still expose bubbles on expert routing or token-by-token work.
The required receipt joins:
rank and expert map
message-size histogram
RCCL operation
p50 / p95 / p99
link and retry state
GPU idle time
HBM traffic
accepted tasks
power and cost
CXL is a conditional warm tier, not Helios HBM
CXL can add CPU-attached memory capacity, but the GPU does not experience it as local HBM. A restore must cross a real topology and still beat recomputation or another placement choice before the next operation needs the data.
No reviewed AMD product artifact establishes a production Helios CXL KV-cache path. CXL can still be tested as CPU-attached capacity behind Venice or a separate memory server.
Good candidates:
stable repeated prefixes
paused-session KV
recommendation embeddings
retrieval indexes
model and checkpoint staging
predictably prefetched cold experts
Bad default candidates:
active weights used every token
active per-token KV
hot activations
GPU workspaces
MoE all-to-all
The decision is not HBM or CXL in the abstract:
CXL fetch and restore
vs
recompute prefix
vs
wait for state owner
vs
route request to state owner
vs
use host DDR or storage
Use CXL only if the complete path improves accepted tasks per rack-hour under the same p99 and quality rule.
Penguin Solutions' MemoryAI is a useful comparison. It is a separate 4U memory server built around dual EPYC CPUs, 3 TB DDR5, and up to eight 1 TB CXL cards for up to 11 TB of system memory. It targets KV and context capacity. It does not make CXL-attached DDR behave like local MI455X or Rubin HBM.
Astera Labs sells CXL controllers, retimers, switches, cable modules, and management software to hyperscalers, cloud platforms, OEMs, and memory-module vendors. Penguin sells complete systems, integration, deployment, and operations. These are different points in the stack.
MI400 is a family, not one universal SKU
Keep source labels exact:
| Name | Public role |
|---|---|
| MI430X | high-precision HPC, AI for science, and sovereign systems; 432 GB HBM4 and 19.6 TB/s disclosed |
| MI440X | enterprise/on-prem eight-GPU role; final memory, bandwidth, power, and package not public |
| MI450 Series | label used in major deployment agreements |
| MI455X | named flagship Helios accelerator |
| Meta custom MI450-based GPU | customer-specific accelerator; exact memory and package not publicly specified |
Do not silently convert every MI450-family customer into a stock MI455X customer.
Customer claims need exact labels
| Customer | Confirmed public object | Unsafe rewrite |
|---|---|---|
| OpenAI | MI450 Series, up to 6 GW, first 1 GW in 2H 2026 | all stock MI455X |
| Meta | custom GPU based on MI450 architecture, Helios, up to 6 GW | confirmed 144 GB / six-stack product |
| Microsoft | Azure ND MI455X v7 / Helios direction | measured production economics |
| Oracle | 50,000 MI450-Series GPUs in Helios deployment | all stock MI455X |
| Anthropic | no primary confirmation found in this audit | confirmed customer |
How Helios compares with NVIDIA's HBM progression
The comparison must preserve scope and precision.
| Platform | Per-GPU memory | Per-GPU HBM bandwidth | Rack GPU memory | Rack HBM bandwidth | Scale-up |
|---|---|---|---|---|---|
| NVIDIA GB300 NVL72 | 288 GB HBM3E architecture | about 8 TB/s | 20 TB | 576 TB/s | 130 TB/s NVLink 5 |
| AMD Helios | 432 GB HBM4 | 23.3 TB/s peak | 31 TB | 1.7 PB/s aggregate peak | 260 TB/s UALoE |
| NVIDIA Vera Rubin NVL72 | 288 GB HBM4 | 22 TB/s | 20.7 TB | 1.58 PB/s | 260 TB/s NVLink 6 |
Helios publishes about 1.5x Rubin's HBM capacity per GPU and per rack, about 1.06x Rubin's per-GPU peak HBM bandwidth, and about 1.08x its rack aggregate peak HBM bandwidth. Both publish a 260 TB/s scale-up headline. Their latency, collective behavior, precision formats, runtime maturity, and accepted-work performance are not equivalent, and no same-workload receipt here establishes a winner.
The NVIDIA upgrade itself is revealing:
GB300 -> Rubin:
HBM capacity per GPU stays at 288 GB
rack GPU memory stays near 20 TB
per-GPU HBM bandwidth rises from about 8 to 22 TB/s
rack HBM bandwidth rises from 576 TB/s to 1.58 PB/s
scale-up bandwidth doubles from 130 to 260 TB/s
Rubin uses HBM4 mainly to increase bandwidth and system integration, not to produce a large local-capacity jump.
Where NVIDIA places reusable context
NVIDIA's public Rubin context answer is CMX, not raw CXL. CMX combines Dynamo, NIXL, Spectrum-X Ethernet, BlueField-4, DOCA Memos, and flash/NVMe-backed context capacity. KV is restored into host or GPU memory before its deadline.
Rubin HBM4:
active weights, active KV, activations, workspaces
Vera LPDDR5X:
CPU work, metadata, warm state, staging
CMX / local flash:
reusable context that can be restored before deadline
storage:
durable repositories, logs, indexes, and artifacts
CMX is not HBM. CXL is not HBM. A DPU is not HBM. The system wins only when the placement and restore policy make useful work cheaper without breaking p99, correctness, security, or quality.
How C-001 Hermes plus GLM-5.2 would traverse Helios
This is the fixed coding-agent workload from the rest of the article. The model is not a generic chatbot. It must inspect a repository, use tools, edit files, run tests, repair failures, and return one accepted patch.
1. Venice CPU boundary
hold system instructions, permissions, repository metadata, tool schemas,
tokenizer work, scheduling, sandbox state, test processes, and verification
2. Engine decision
select and pin PyTorch plus vLLM, SGLang, or another declared engine
capture container, ROCm, driver, firmware, model, tokenizer, and precision
3. Native AMD operation path
ROCm / HIP
-> AITER, Triton, Composable Kernel, hipBLASLt, or rocBLAS
-> RCCL or rocSHMEM when the chosen parallel plan communicates
-> AMDGPU compilation and HSACO only after the exact target is captured
4. MI455X and HBM4
read FP8 or BF16 model state according to the exact artifact
create and reuse prefix and active KV state
hold activations, MoE expert shards, routing buffers, and workspaces
never infer useful bandwidth from the 23.3 TB/s peak
5. Rack fabrics
use UALink or UALoE only when tensor, pipeline, expert, or other state
crosses the selected GPU placement
use Vulcano and Ultra Ethernet only when traffic crosses the rack boundary
6. Tool and verifier return
pause or continue GPU work under an explicit tool-window policy
run repository tools on the declared CPU sandbox
join the patch, tests, retries, latency, power, and cost under one run ID
ARCHITECTURE ONLY / RUN NOT CAPTURED. The current article has no selected MI455X compiler target, device executable, instruction stream, dispatch trace, HBM counter, UALoE trace, power interval, or accepted-patch receipt. NVIDIA code examples cannot fill those AMD fields.
One VAST Data and AMD test makes the reusable-KV path concrete. It is evidence for a memory hierarchy, not evidence that storage replaced HBM.
VAST Data published a July 23, 2026 benchmark using one AMD MI355X node, GPT-oss 120B, ROCm, vLLM 0.22.1, LMCache, tensor parallelism of one, concurrency from one through 300, and an explicitly described 128K-token setup. The remote path used the LMCache filesystem plugin, NFSv3 over RDMA, NFS multipath, an 800 Gb/s network, and a VAST storage partition. The source calls the adapters AMD Infinity Fabric 800Gb NICs; it does not identify them as Vulcano, so this article does not silently rename the test hardware. It also describes local host RAM as a comparison tier without identifying that memory as DDR5 or LPDDR5X.
active request
-> vLLM schedules GPT-oss 120B on MI355X
-> ROCm kernels create and consume active KV in MI355X HBM3E
-> LMCache identifies reusable KV chunks
-> filesystem plugin writes or restores through NFSv3 over RDMA
-> 800 Gb/s NIC and switch carry the transfer
-> VAST flash retains the reusable object
-> restored KV returns to the serving path before decode can use it
Step by step: from one long-context request to the physical memory system.
| Step | What moves or changes | Physical layer | Why the CEO or CFO should care | Receipt |
|---|---|---|---|---|
| 1. Request identity | Prompt, policy, model revision, tokenizer, tenant, and session identity enter the serving system | CPU registers, caches, and host memory | A wrong cache key can return stale or cross-tenant state even if the transfer is fast | Request ID, exact revisions, tenant and ACL policy |
| 2. Prefill | GPT-oss 120B transforms the 128K-token context into attention state | MI355X compute units read weights and write active KV through cache and HBM controllers | This is the expensive computation the remote cache is trying not to repeat | Kernel timeline, input tokens, TTFT, HBM bytes, output check |
| 3. HBM cell write | Each KV bit is encoded as charge in a DRAM cell and recovered through wordlines, bitlines, sense amplifiers, and restore | HBM3E DRAM arrays inside vertically stacked memory dies | HBM is fast because many channels operate in parallel close to the accelerator, but every access still consumes time and energy | Memory-controller counters and a synchronized board-power interval |
| 4. Vertical and package movement | Signals cross on-die metal, dense vertical TSVs, die-to-die bonds or bumps, the stack interface or base layer, and the accelerator package | Copper-dominated wiring, dielectrics, silicon, solder or hybrid-bond structures, redistribution layers, substrate, power delivery, and thermal interfaces | The memory wall is physical: wire length, capacitance, resistance, heat, yield, and package area turn bytes into cost | Vendor stack map, package cross-section, channel counters, thermal map, yield and repair data |
| 5. Chunk and policy decision | LMCache groups reusable KV into 8,192-token chunks and decides whether the object is eligible to leave local memory | Software metadata in host memory; active source blocks still reside in accelerator HBM | Chunk size trades metadata and transfer overhead against wasted bytes and late restores | Cache key, chunk IDs, admitted bytes, rejected bytes, eviction reason |
| 6. Read out of the hot tier | Eligible KV is copied out of accelerator memory toward the host or I/O path | HBM read, accelerator I/O, PCIe or platform path, DMA engines, host staging only if the selected path requires it | Copying state frees scarce HBM capacity but uses bandwidth and can interrupt useful work | Source and destination addresses, bytes, DMA path, overlap, p50/p95/p99 |
| 7. Remote transfer | NFSv3 over RDMA carries the filesystem I/O through the named 800 Gb/s adapters and Mellanox switch | NIC SerDes, copper or optical links, switch buffers, packet headers, flow control, and retransmission or fallback behavior | A nominal 800 Gb/s link does not guarantee useful KV goodput or a stable tail | Link topology, backend, packet and retry counters, transfer latency, NIC and switch power |
| 8. VAST flash retention | The KV object is written to or read from the VAST storage partition | Storage controllers, DRAM metadata and caches, flash channels, NAND media, power supplies, and cooling | Remote flash is cheaper capacity than accelerator HBM only if reuse, latency, durability, and operational cost work together | Object bytes, media and array identity, queue depth, service time, array energy, failure state |
| 9. Restore | A later matching request retrieves the exact chunks and reinstalls them into the serving path | Flash to network to accelerator I/O, followed by HBM writes before the GPU consumes the KV | The restore must arrive before recomputing prefill would have finished and must not crowd out active work | Hit, identity validation, bytes restored, full-restore p99, recompute baseline, correctness |
| 10. Accepted result | Decode continues and the application decides whether the output is useful | GPU decode, CPU tools, application verifier, logs, and durable output | Faster tokens are not business value if the result fails, retries, or needs human repair | Accepted output, retries, total latency, energy, cost, and failure ledger under one run ID |
The deepest physical point is easy to lose in a software diagram. A logical KV block is not a box floating inside the GPU. Its bits are represented by electrical state in DRAM cells. Access activates rows, perturbs bitlines, uses sense amplifiers to resolve very small voltage differences, restores cell charge, and moves data through on-die wiring and the HBM stack interface. Dense TSVs shorten the vertical path relative to board-level memory, while the wide package connection creates parallelism. The benefit comes with more difficult wafer processing, die thinning, alignment, bonding, thermal management, package routing, test, repair, and known-good-die economics. Exact MI355X stack materials, TSV dimensions, bonding process, and per-boundary energy are not public in the cited benchmark, so the article does not substitute a generic HBM diagram for a product teardown.
The offload path does not make those HBM writes disappear. It changes when they happen:
recompute path:
read weights from HBM
execute prefill again
write new KV to HBM
restore path:
read saved KV from remote flash
move it through storage, switch, NIC, and accelerator I/O
write restored KV to HBM
restore wins only when:
transfer time + queueing + validation + HBM reinstall + miss risk
is lower than
repeated prefill time under the same correctness and p99 requirement
The power and materials follow every arrow. HBM power includes array activation, sensing, restore, refresh, I/O, controller, and package losses. Compute power includes matrix, vector, cache, register, clock, and control activity during prefill. The remote path adds storage controllers and media, NIC SerDes, switch buffers, CPUs or DPUs, fans or liquid loops, voltage conversion, and facility overhead. Copper reduces resistance but does not remove capacitance. Shorter TSV and package paths can reduce movement energy relative to longer board or network paths, but manufacturing and cooling costs do not vanish.
For this exact benchmark, the honest ledger is:
known:
MI355X node
GPT-oss 120B
vLLM 0.22.1 plus LMCache plus ROCm
128K detailed context setting
tensor parallelism 1
concurrency 1 through 300
8,192-token chunks
NFSv3 over RDMA
800 Gb/s network
vendor-reported 9x TTFT and 9.7x token throughput
not published:
exact HBM bytes read and written
exact KV bytes stored and restored
cache-hit distribution
GPU, CPU, NIC, switch, and storage watts over the same interval
joules per request
electricity tariff
facility PUE
facility WUE and water allocation
hardware and support price
accepted-task result
The equations a real receipt must fill are:
task energy, kWh =
integral of
accelerator + CPU + DPU + NIC + switch + storage + allocated cooling power
over the same task interval
/ 3,600,000
electricity cost =
task energy in kWh * contracted tariff
allocated facility water, liters =
measured IT energy in kWh * declared WUE in liters per kWh
cost per accepted task =
electricity
+ allocated accelerator, network, and storage capacity
+ software, support, and engineering
+ failed attempts and human rework
divided by accepted tasks
Those formulas make the decision inspectable; they do not manufacture missing inputs. The older modeled HBM2 literature cited elsewhere in this article reports an approximately 3.97 pJ/bit access value for its own configuration. It is useful for understanding why distance and movement matter. It is not an MI355X, HBM3E, VAST, BlueField, CMX, or facility-water measurement.
The headline comparison is the VAST-optimized remote path against no offload, where the context was recomputed at the start of each decode turn. VAST reports a 9x improvement in time to first token and 9.7x greater token throughput for its named setup. These are [VENDOR-REPORTED BENCHMARK RESULTS]. VAST's page says AMD reviewed the claims but did not independently verify them, and that the result is specific to VAST and may not be typical. The page introduction says 120K tokens while the detailed setup and results say 128K; this article uses the explicit 128K setup and preserves the discrepancy instead of averaging it away.
The software configuration matters as much as the storage brand. The published path used asynchronous loading, direct I/O, 8,192-token LMCache chunks, a 16 MiB read-ahead value, and a filesystem base path on the shared VAST mount. That proves a named configuration was reported. It does not prove a cache hit, byte transfer, tail-latency distribution, power result, or accepted coding task on Touchdown infrastructure.
The new AMD networking parts occupy different boundaries.
| Part | Boundary | Memory-wall role | What it does not prove |
|---|---|---|---|
| Salina DPU | Front-end networking, security, software-defined networking, storage access, and DPU-managed NVMe | Can move infrastructure and storage work away from host CPU cores and make an NVMe-backed KV tier easier to operate | That an application used the DPU, that KV bypassed the host, or that restore beat recompute |
| UALink over Ethernet | Scale-up inside Helios | Connects 72 MI455X accelerators so distributed model state and communication can cross GPU packages | Cache identity, storage access, scale-out behavior, or application goodput |
| Vulcano 800 AI NIC | Scale-out and scale-across | AMD publishes 800 Gb/s per NIC and up to three NICs per GPU, or a 2.4 Tb/s-per-GPU ceiling | Sustained useful bandwidth, p99, switch behavior, power, or KV hit rate |
| Pollara 400 AI NIC | Existing Ethernet clusters | Brings AMD Pensando's AI-networking path to current deployments | The Salina storage role or the Vulcano Helios topology |
| VAST AI Operating System plus flash | Remote reusable-data and KV tier | Gives LMCache a remote filesystem target so reusable context can outlive local HBM pressure | Local-HBM latency, cache correctness, universal 9x performance, or lower total energy |
| LMCache | KV identity, chunking, admission, movement, and restore policy | Decides what reusable KV object is stored and requested | A physical wire, DPU, NIC, switch, or storage array |
The equivalent NVIDIA path uses different products but the same memory question:
Blackwell HBM3E or Rubin HBM4
active weights, active KV, activations, and workspaces
Grace or Vera CPU memory
CPU tools, metadata, warm state, and staging
BlueField-4 plus CMX
DPU-managed, Spectrum-X-connected flash context tier
Dynamo / KV block manager plus NIXL and DOCA Memos
identity, placement, and movement policy
BlueField is the DPU. CMX is the context-memory storage platform. NIXL is movement software. Dynamo and the KV manager make serving decisions. Blackwell HBM3E and Rubin HBM4 remain the hot tiers. For the complete KV-cache software hierarchy, read KV Cache Is Becoming the Memory Hierarchy of Inference. The point here is narrower: these systems exist because HBM capacity, bandwidth, energy, and cost make repeated recomputation expensive, not because flash has become HBM.
Memory, power, and money require one joined comparison.
candidate A: keep reusable KV in accelerator HBM
candidate B: spill to host DDR or LPDDR5X
candidate C: restore from VAST or CMX flash
candidate D: miss and recompute prefill
for every candidate:
same model, precision, prompt, context, concurrency, and output check
measure hit rate, bytes, queueing, restore p50/p95/p99, and recompute time
integrate accelerator, CPU, DPU, NIC, switch, storage, and cooling power
apply the actual electricity tariff and infrastructure allocation
divide by accepted tasks, not cache requests or generated tokens
The remote path can save money when avoided GPU-seconds and freed HBM capacity are worth more than the DPU, NIC, switch, flash, CPU, software, support, and tail-latency cost. It can save energy when avoided recompute exceeds the energy used to store, find, move, validate, and reinstall the KV blocks. It can lose on both when reuse is low, objects are stale, transfers arrive late, or the network and storage tier stay powered for little accepted work.
The VAST benchmark does not publish a synchronized power trace, electricity rate, storage-array energy, facility PUE, facility WUE, water allocation, purchase price, or accepted-task result. Those fields remain unknown. Coolant flow is not water consumption. A DPU or NIC TDP is not task energy. Water belongs in the facility ledger only when the same measured IT-energy interval is joined to a declared WUE and allocation method.
What this means by reader. The CEO asks whether more long-context sessions complete on time. The CFO compares avoided GPU-seconds and deferred accelerator capacity against storage, network, power, support, and engineering cost. The CTO owns cache identity, tenant isolation, failure fallback, topology, and rollback. The serving engineer captures the exact LMCache, vLLM, ROCm, filesystem, and transport versions. The infrastructure engineer measures DPU, NIC, switch, and storage queues. The kernel and GPU engineer decides when restore is slower than recompute and which active blocks must remain in HBM.
How V-001 Wan2.2 would traverse Helios
Wan2.2 creates a different state lifecycle. It does not grow an autoregressive LLM KV cache token by token. Its attention Q/K/V tensors are transient inside repeated denoising work.
1. Venice CPU boundary
accept the prompt, prepare metadata, schedule the text encoder,
allocate the latent contract, and manage the output and quality gate
2. ROCm candidate runtime
pin PyTorch, the Wan2.2 repository revision, ROCm, libraries,
model weights, dtype, resolution, frame count, and sampling steps
3. MI455X HBM4
retain model weights, latent state, transient Q/K/V,
activations, communication buffers, scheduler state, and VAE workspace
4. Distributed denoising
cross UALink or UALoE only if the pinned tensor, sequence, FSDP,
Ulysses, expert, or pipeline plan actually communicates
capture RCCL operation, message size, rank map, wait time, and retries
5. Decode and acceptance
decode through the selected VAE path
verify frame count, dimensions, codec, quality rule, and failure policy
divide total time, energy, and cost by accepted clips, not attempts
ARCHITECTURE ONLY / RUN NOT CAPTURED. No reviewed source proves Wan2.2 executed on Helios. The MI455X model path, kernels, transient HBM traffic, collective behavior, output quality, power, energy, water, and cost remain unknown.
What Touchdown should measure
For a coding-agent workload:
model and revision
precision and quality parity
engine and kernel path
context and concurrency
TTFT, TPOT, end-to-end p50/p95/p99
HBM occupancy and fragmentation
prefix-hit rate
KV bytes
KV offload tier and object identity
restore bytes and p50/p95/p99
model and expert shards
RCCL/NCCL wait
fabric message histogram
DPU/NIC activity
accelerator, CPU, DPU, NIC, switch, and storage power
facility PUE, electricity tariff, and separately measured WUE when available
cost and joules per accepted patch
For Wan2.2-style video:
latent dimensions and token count
denoising phases and steps
attention, FFN/MoE, and VAE time
QKV and activation traffic
HBM reads and writes
collective wait
power
quality gate
cost and joules per accepted clip
What each reader should take from the Helios lane
| Reader | Decision this architecture can inform now | Receipt still required |
|---|---|---|
| Investor | AMD has launched MI455X and moved the Helios reference-design system into full production | shipment ramp, partner configurations, supply, yield, customer acceptance, utilization, and economics |
| CEO | Helios could become another infrastructure option for the same accepted business workflow | accepted-task throughput, reliability, deployment time, and operator ownership |
| CFO | More HBM and rack bandwidth may change how many replicas, shards, or racks are needed | price, rack power, facility work, support, failures, utilization, and cost per accepted task |
| CTO / infrastructure | The port crosses runtime, kernels, collectives, topology, failure, and service boundaries | pinned version matrix, degraded-mode plan, topology tests, p95/p99, and rollback |
| Software engineer | The framework call is only the top of a different AMD runtime path | exact engine flags, fallbacks, artifact identity, logs, and correctness |
| Kernel engineer | Useful bandwidth depends on shapes, layout, fusion, occupancy, MFMA path, and communication | selected target, IR/HSACO, kernel name, counters, numerical parity, and profiler interval |
| Hardware / facility engineer | The rack combines HBM4 packages, fabrics, power shelves, busbar, liquid manifold, and service points | final BOM, rack power, flow, pressure, coolant, CDU, thermal map, repair, and yield |
Final AMD conclusion
Helios is serious competition because AMD now combines:
CDNA 5
HBM4
Venice
Vulcano
Salina
UALink
Ultra Ethernet
ROCm
semi-custom silicon
large customer commitments
The remaining question is not answered by a specification sheet:
Can AMD convert its published peak capacity and bandwidth advantage at the named MI455X and Helios scopes, plus its open customization path, into stable, quality-matched accepted-work throughput before NVIDIA's fabric, software, context, and deployment integration closes the system-level gap?
The answer needs synchronized workload, HBM, fabric, power, failure, quality, and cost receipts.
Primary sources
- AMD Helios
- AMD Helios brochure
- AMD Advancing AI 2026 Helios launch update
- AMD Advancing AI 2026 MI400 launch update
- AMD Advancing AI 2026 official keynote: Helios production announcement at approximately 31:00
- AMD AI Networking Built for Scale
- AMD Pensando Vulcano 800 AI NIC
- VAST Data and AMD KV-cache benchmark
- VAST AI Operating System
- Touchdown Labs: KV Cache Is Becoming the Memory Hierarchy of Inference
- ROCm 7.14 release notes
- ROCm hardware support table
- ROCm component changelog
- TheRock AMDGPU target registry
- TheRock supported-GPU table
- RCCL MI455X test configuration
- MoRI
- ROCm Infinity Context
- AMD MI355X
- AMD MI400 portfolio announcement
- AMD and OpenAI
- AMD and Meta
- Microsoft and AMD
- NVIDIA GB300 NVL72
- NVIDIA Vera Rubin NVL72
- NVIDIA CMX
- Micron HBM4 for Vera Rubin
- Samsung commercial HBM4
- Penguin MemoryAI
- Astera Labs Leo
Which memory technologies fit which state roles?
In plain English. No memory technology wins every job. Hot, frequently changing state needs to stay close. Warm, reusable state can sometimes tolerate a transfer. Cold, durable state belongs in cheaper storage. Some state is cheaper to recompute than to preserve. Start with the object's lifetime, access pattern, deadline, and correctness rule, then choose a tier.
There is no useful answer to What memory is best? without a state object, boundary, and workload.
The comparison needs the same questions for every technology:
What physical state stores the bit?
How far is it from compute?
What interface and controller expose it?
What is the useful access granularity?
How do first-byte latency and sustained service behave?
How do reads differ from writes?
Does it need refresh? What is its retention and endurance?
How large can the usable tier be in the named system?
What happens under contention, errors, and failure?
What ships, what is modeled, and what is only proposed?
The objective matrix
| Technology | Physical and interface distinction | Plausible role | What breaks first | Evidence state |
|---|---|---|---|---|
| SRAM, cache, scratchpad | Multi-transistor volatile cells close to logic | Smallest, hottest, repeatedly reused state | Area and leakage limit capacity | Shipping, implementation-specific |
| eDRAM | Dynamic cells integrated closer to logic | Larger near-compute working memory where process and refresh fit | Process integration, refresh, temperature, capacity, design/test complexity | Shipping precedents plus workload-specific papers |
| HBM3E | Stacked DRAM with a very wide local package interface | Hot weights, active KV, activations, latents, communication buffers | Capacity, heat, package/PDN, yield, supply, software utilization | Named shipping vendor artifacts; metrics remain source-scoped |
| HBM4 | Stacked DRAM with a wider local package interface and expanded base-logic design surface | Hot weights, active KV, activations, latents, communication buffers | Capacity, heat, package/PDN, yield, supply, software utilization | Public standard plus named shipping vendor artifacts; metrics remain source-scoped |
| Custom HBM and custom base logic | HBM-compatible stack with more configurable logic/control at the base/interface layer | Workload-specific movement, security, RAS, telemetry, or bounded near-memory functions | Non-recurring engineering, access, integration, qualification, power, heat, and yield | Standards and vendor roadmap/design-surface evidence |
| Standard Package High Bandwidth Memory (SPHBM4) | JEDEC JESD330-4 direction for HBM4-stack integration through a different buffer/interface die and standard-package path | Capacity or bandwidth integration under the public standard's scope | Ecosystem access, implementation, validation, and workload value | Public standard record exists; product and access must be named separately |
| Intel XBM application | Backend-transistor DRAM organization with fine subchannels, repair/control, and serialized-package embodiments | Architecture simulation and diligence candidate | Unmeasured latency, energy, retention, yield, cost, thermals, software, product status | Patent application only |
| GDDR7 | Discrete graphics DRAM, high per-pin signaling over a narrower aggregate interface than HBM stacks | High-bandwidth boards where package, cost, serviceability, or capacity trade differs | Signal/power complexity and aggregate board design | Shipping/vendor product evidence |
| DDR5 | Commodity system DRAM, typically DIMM-oriented and CPU-controlled | Large host-visible working memory | Lower accelerator-local bandwidth, longer path, transport overhead | Standard and shipping products |
| LPDDR5/LPDDR5X | Low-power DRAM interface optimized for energy and capacity-density trade-offs | Client, edge, and some data-center designs where power/capacity matter | Different bandwidth, package, controller, serviceability, and ecosystem | Shipping/vendor product evidence |
| CXL-attached memory | Coherent, load/store-capable expansion over a CXL link and topology | Capacity expansion, pooling, workload-defined warm state | Link latency/bandwidth, topology, contention, coherency, software policy, failure domain | Public consortium capability plus named vendor products; shipment state is checked per part |
| NVMe SSD and NAND | Block storage protocol over nonvolatile flash | Durable state, checkpoints, repositories, cold cache, predictable pages | First-byte latency, page/block behavior, writes, endurance, filesystem/controller path | Shipping standard and products |
| Sandisk HBF direction | Proposed high-bandwidth flash stack/interface | Very large read-mostly parameter or predictable-page state | First-byte latency, writes, page usefulness, software/controller maturity | Vendor roadmap and internal simulation |
| Kioxia high-bandwidth flash prototype | Separate flash-module prototype | Physical research evidence for higher-bandwidth flash modules | Prototype scope, workload proof, productization, software | Physical prototype announcement, not Sandisk HBF |
| Emerging device families | PCM, ReRAM/RRAM, MRAM, FeFET, oxide/gain-cell and related candidates | Specific retention, endurance, density, or compute roles if evidence survives | Variability, write cost, endurance, temperature, process, yield, control, ecosystem | Research or named vendor state only |
| Compression and rematerialization | Software reduces retained or moved bytes | Avoid memory demand when compute/quality permit | Extra compute, latency, precision risk, complexity | Shipping techniques; workload result required |
HBM remains the hot-tier baseline. The alternatives change capacity, distance, granularity, retention, energy, or programmability. None removes the need to measure the state path.
SRAM and eDRAM: closer is expensive in different ways
SRAM is the natural home for register files, caches, queues, and software-managed scratchpads because it can deliver fine-grained low-latency access close to compute. Its area cost prevents it from becoming a capacity-equivalent substitute for stacked DRAM.
That area trade affects kernel design. Tiling exists because a small on-chip SRAM working set can reuse data many times before HBM sees another request. Larger tiles can improve reuse but consume registers or shared memory, reduce occupancy, or constrain scheduling. The right tile is an interaction between the operation, data layout, on-chip capacity, and HBM path.
eDRAM offers another point. The RANA paper from ISCA 2018 explored refresh-aware eDRAM for CNN acceleration using synthesized RTL, cycle-accurate simulation, and modeled energy. [PAPER, MODELED] Its useful idea is that workload error tolerance, layer scheduling, bank allocation, and refresh control can be co-designed. Its limit is equally important: it is not fabricated RANA silicon, HBM, an LLM, video diffusion, robotics proof, or a current-node benchmark. It shows that retention and refresh can become workload-visible design variables under a bounded experiment.
HBM3E and HBM4: the hot-tier tournament baseline
HBM's strength is aggregate local bandwidth and channel parallelism under a tight package. HBM4 continues that direction while expanding the logic base-die and interface design space.
[VENDOR PRODUCT ARTIFACT] Micron's dated HBM3E product brief establishes a named HBM3E product family and its vendor-scoped specifications. It does not establish a universal HBM3E system result.
[SHIPPING VENDOR ARTIFACT] Samsung's dated announcement says it shipped a commercial HBM4 product and describes a 4 nm logic base die. It reports 11.7 Gb/s operation and capability up to 13 Gb/s for its named product context. [SHIPPING VENDOR ARTIFACT] Micron's dated announcement says it began volume production of a 36 GB 12-high HBM4 product designed for NVIDIA Vera Rubin and reports more than 2.8 TB/s for that named part. These are vendor statements, not Touchdown measurements. The scope is a part or stack, not every accelerator.
HBM4 does not solve everything by becoming wider or faster. The accelerator needs enough outstanding work, useful layout, controller balance, on-chip reuse, power, and thermal headroom. Capacity can still limit model size or concurrency. More interface pins and logic increase package and validation demands.
The accelerator roadmap is also a memory roadmap
Comparing generations is easy to get wrong because vendors publish at different scopes. A single-GPU capacity cannot be placed beside a 72-GPU rack total without naming the boundary. Peak theoretical bandwidth is not sustained useful bandwidth. A roadmap projection is not a shipping receipt.
Use this five-number decoder before reading the table:
| Number | What it answers | What it does not answer |
|---|---|---|
| Memory capacity, GB or TB | How much state can fit at the named device or rack scope | How fast the state arrives or how much is usable after runtime reservation |
| Local HBM bandwidth, GB/s or TB/s | The peak or measured byte rate between an accelerator and its local HBM | Fabric speed, latency, or accepted-task throughput |
| Compute rate, FLOPS | A theoretical or measured rate for eligible arithmetic at a named precision | Quality equivalence, memory utilization, or application speed |
| Fabric bandwidth, GB/s or TB/s | The peak or measured rate between named components or domains | Small-message p99, collective efficiency, or local HBM bandwidth |
| Latency, seconds or milliseconds | Time between two named events | Throughput, capacity, or the reason for the delay |
None of these five numbers proves how many patches, clips, or other tasks the system accepts.
| Vendor platform | Evidence state on July 23, 2026 | Published memory scope | Published memory bandwidth scope | Interconnect and system boundary |
|---|---|---|---|---|
| NVIDIA H100 SXM | Official current product | 80 GB HBM per GPU | 3.35 TB/s per GPU | NVLink 4, 900 GB/s per GPU; system topology varies |
| NVIDIA H200 SXM | Official current product | 141 GB HBM3E per GPU | 4.8 TB/s per GPU | Same 900 GB/s NVLink-class per-GPU figure; more local capacity and bandwidth than H100 |
| AMD Instinct MI350P | Official current product | 144 GB HBM3E per PCIe card | 4 TB/s peak theoretical per card | PCIe 5.0 x16; passive full-height double-slot card; 450 W configurable and 600 W maximum TBP |
| AMD Instinct MI355X | Official current product | 288 GB HBM3E per GPU | 8 TB/s peak theoretical per GPU | Seven scale-up Infinity Fabric links; 1,400 W published TBP for the OAM |
| NVIDIA GB200 NVL72 | Official current rack system | 13.4 TB HBM3E across 72 GPUs | 576 TB/s aggregate HBM | 130 TB/s aggregate NVLink domain, plus 36 Grace CPUs and LPDDR5X |
| NVIDIA GB300 NVL72 | Official current rack system | 20 TB HBM3E across 72 GPUs | Up to 576 TB/s aggregate HBM | 130 TB/s aggregate NVLink domain; more HBM capacity than GB200 |
| NVIDIA Vera Rubin NVL72 | Official preliminary | 20.7 TB HBM4 across 72 GPUs | 1,580 TB/s aggregate HBM | NVLink 6, 260 TB/s aggregate scale-up bandwidth; specifications subject to change |
| AMD MI455X / Helios | Official current launch and production reference design; shipments scheduled to begin near end-Q3 and ramp in Q4 | 432 GB HBM4 per MI455X; 31 TB across 72 GPUs | 23.3 TB/s peak per MI455X; 1.7 PB/s aggregate peak per rack | 72-GPU UALink/UALoE scale-up domain; OEM/ODM reference design rather than one direct AMD rack SKU |
| NVIDIA Vera Rubin Ultra NVL72 / Kyber NVL144 / NVL576 | Official preliminary topology | Final public per-system HBM specification is not treated as fixed here | Final delivered useful bandwidth is not public | Three different 72-, 144-, and 576-GPU domain options; Kyber is the 144-GPU rack |
| AMD Instinct MI500 Series | Official roadmap | HBM4E named; capacity not public in the reviewed primary source | Not public | CDNA 6 and 2 nm named; planned for 2027; AMD performance statements are projections |
| NVIDIA Feynman Kyber NVL1152 | Official preliminary topology | Final HBM implementation and delivered capacity not public | Not public | Eight 144-GPU Kyber racks in one planned scale-up domain |
[OFFICIAL PRODUCT / ROADMAP SOURCES] H100, H200, GB200, GB300, and Vera Rubin figures above use NVIDIA's named product pages and current platform documentation. MI350P uses AMD's current product page and enterprise deployment article. MI355X uses AMD's product page. The July 23 MI400 launch and Helios launch govern the current MI455X and Helios fields. The older 19.6 TB/s MI400-family projection and 1.4112 PB/s arithmetic rack total are historical, not current launch specifications. MI500 uses AMD's CES 2026 roadmap statement naming CDNA 6, 2 nm, HBM4E, and a planned 2027 launch. Future rows are not purchase specifications, and current peak specifications are not measured workload results.
How should a buyer compare RTX 6000, B200, B300, GB200, GB300, MI350P, MI355X, and Helios?
Start with scope. These products do not belong in one flat leaderboard. An RTX workstation card, a passive MI350P server card, one MI355X OAM, an eight-GPU DGX system, a Grace Blackwell Superchip, and a 72-GPU rack expose different memory domains, CPU boundaries, fabrics, cooling requirements, software contracts, and failure domains. The first question is not which number is largest. It is which state must stay local for which workload, and at what physical boundary.
| Compare at the same boundary | NVIDIA path | AMD path | Memory fact that matters | Design decision and limitation |
|---|---|---|---|---|
| Workstation or enterprise PCIe card | RTX 6000 Ada has 48 GB GDDR6. RTX PRO 6000 Blackwell Workstation, Max-Q, and Server each have 96 GB GDDR7, with different power and deployment roles documented below. | MI350P has 144 GB HBM3E and 4 TB/s peak local bandwidth in a passive PCIe server card. | This is local accelerator memory on one card. HBM3E and GDDR7 make different capacity, bandwidth, packaging, power, graphics, media, and serviceability bargains. | Choose from the actual job. Local graphics, media, CAD, visualization, and model development are not the same path as dense server inference, private RAG, or an eight-card agent service. No peak-memory ratio proves accepted-task throughput. |
| Accelerator and eight-GPU server | NVIDIA publishes 1,440 GB total GPU memory and 64 TB/s aggregate HBM3E bandwidth for DGX B200. NVIDIA publishes 2.1 TB total GPU memory for DGX B300. | AMD publishes 288 GB HBM3E and 8 TB/s peak per MI355X OAM. The buyer must name the exact eight-accelerator UBB or OEM server before multiplying or comparing a node. | A product page may report per accelerator, per baseboard, or per complete server. Aggregate capacity is the sum of separate local domains unless the runtime and fabric prove a usable distributed placement. | B200 and B300 package a qualified NVIDIA system and software boundary. MI355X gives more local HBM per named accelerator, but server topology, ROCm and kernel qualification, cooling, collectives, and support remain configuration-specific. |
| CPU-GPU superchip and 72-GPU rack | GB200 NVL72 publishes 13.4 TB HBM3E at 576 TB/s aggregate, 17 TB Grace LPDDR5X at 14 TB/s, and a 130 TB/s NVLink domain. GB300 NVL72 publishes 20 TB GPU memory, up to 576 TB/s aggregate memory bandwidth, the same published CPU-memory scope, and a 130 TB/s NVLink domain. | Helios publishes 31 TB HBM4 and 1.7 PB/s aggregate peak memory bandwidth across 72 MI455X accelerators, with Venice CPUs, UALink over Ethernet scale-up, Vulcano 800 scale-out NICs, and Salina DPUs. The OEM or ODM owns the exact host-memory configuration. | CPU memory, accelerator-local HBM, scale-up bandwidth, scale-out networking, and storage are five different boundaries. Coherent or routable access does not make them one pool with one latency. | Compare the whole model placement, KV and activation lifetime, collective graph, p99 latency, rack power, cooling, failure behavior, and accepted output. Published rack ceilings do not establish useful bandwidth, tokens per watt, or cost per accepted task. |
| Context and data outside local accelerator memory | NIXL coordinates movement. BlueField handles named infrastructure work. CMX is an announced context-memory storage direction. NVMe or remote storage retains colder objects. | ROCm and the serving engine own placement. Infinity Fabric or UALink handles named GPU domains. Vulcano and Salina own different network and infrastructure roles. The VAST plus LMCache example uses remote flash over a named RDMA path. | A DPU, NIC, CXL device, host-memory tier, or flash system does not become HBM. It changes where an object waits and how it returns. | Offload wins only when lookup, identity, transfer, restore, miss handling, energy, and failure behavior beat recomputation before the reuse deadline. |
The design sequence is the same for every row:
- Write down the exact weight, KV, activation, latent, workspace, communication-buffer, and tool-state objects.
- Prove which objects fit in each local memory domain after runtime reservation and fragmentation.
- Trace every byte that leaves local memory through the selected CPU, PCIe or coherent link, scale-up fabric, NIC or DPU, network, and storage path.
- Name the existing framework, compiler, kernel library, collective library, serving engine, placement layer, driver, firmware, and observability tools that support that exact hardware revision.
- Join output quality and accepted work to latency, measured power, integrated energy, cooling and water allocation, retries, failures, and money.
That sequence prevents three common mistakes: treating aggregate rack memory as one flat address space, treating a software package import as workload support, and treating a roadmap component as a delivered system.
In plain English. MI350P is the CDNA 4 card for an enterprise that wants local AI inference inside familiar PCIe servers without moving straight to an eight-OAM baseboard or a 72-GPU Helios rack. It has 144 GB of local HBM3E and 4 TB/s of published peak memory bandwidth. It is not the 288 GB MI350X or MI355X in another shell.
[OFFICIAL CURRENT PRODUCT SPECIFICATION, REVIEWED 2026-07-23] AMD publishes these product-scoped fields:
| Compute field | MI350P official value |
|---|---|
| GPU architecture and process | CDNA 4; TSMC 3 nm and 6 nm FinFET |
| Stream processors / matrix cores / compute units | 8,192 / 512 / 128 |
| Peak engine clock / transistors | 2,200 MHz / 73 billion |
| Peak MXFP4 / MXFP6 / MXFP8 matrix | 4.6 / 4.6 / 2.3 PFLOPS |
| Peak OCP FP8 matrix | 2.3 PFLOPS dense; 4.6 PFLOPS with structured sparsity |
| Peak FP16 and BF16 matrix | 1.15 PFLOPS dense; 2.3 PFLOPS with structured sparsity |
| Peak INT8 matrix | 2.3 POPS dense; 4.6 POPS with structured sparsity |
| Peak scalar FP16 | 72 TFLOPS |
| Peak FP32 matrix / scalar | 72 / 72 TFLOPS |
| Peak FP64 matrix / scalar | 36 / 36 TFLOPS |
| Memory, board, and software field | MI350P official value |
|---|---|
| Local memory | 144 GB HBM3E |
| Peak local HBM bandwidth / interface | 4 TB/s / 4,096 bit |
| Last-level cache / Infinity Cache | 128 MB / yes |
| Data protection | Full-chip ECC |
| Board power | 450 W configurable; 600 W maximum TBP |
| Host and external power | PCIe 5.0 x16; 12V-2x6 |
| Physical card | PCIe add-in card; full height; double slot; 10.5 in / 267 mm |
| Cooling | Passive |
| Operating system | Linux x86-64 |
| RAS and virtualization | RAS, page retirement, page avoidance; current AMD web specification says SR-IOV is supported, while the May 2026 brochure describes SR-IOV as future support for up to four partitions |
| Supported technologies | CDNA 4, 4th Gen AMD Infinity Architecture, ROCm |
| APIs | OpenMP, OpenCL, HIP, ROCm |
| Frameworks listed by AMD | TensorFlow, PyTorch, ONYX-RT, SGLang, JAX, Triton, Kokkos, RAJA |
AMD's page renders the framework label ONYX-RT; it is preserved here rather than silently corrected. AMD also says some technologies need third-party enablement, features vary by operating system, and the buyer should confirm support with the system manufacturer. Every compute and bandwidth rate above is a vendor-published theoretical peak, not a Touchdown benchmark.
AMD's current web specification and product brochure conflict on SR-IOV timing. Production virtualization therefore needs the exact ROCm, hypervisor, firmware, OEM-server, and support-matrix receipt. The article does not turn either source into an unqualified deployment claim.
[OFFICIAL AMD DEPLOYMENT POSITIONING, REVIEWED 2026-07-23] AMD describes MI350P as a dual-slot card for standard air-cooled partner servers, including configurations with up to eight cards. AMD names on-premises inference, RAG, generative AI, agentic AI, and small, medium, and large model inference. It also names ROCm, PyTorch, AMD Inference Microservices, Kubernetes GPU Operator, and partner bare-metal, virtualized, Kubernetes, and hybrid-cloud paths.
The useful enterprise role is specific:
private RAG and document assistants
agent and tool-calling inference
departmental or tenant-isolated model serving
embeddings, reranking, and generation pipelines
fine-tuning that fits the measured memory budget
regulated on-premises inference
incremental one-card to qualified eight-card deployment
That list is workload fit to test, not a claim that every workload wins.
Memory topology. One MI350P has one local 144 GB HBM3E domain. AMD publishes PCIe 5.0 x16 for the card. AMD does not publish the seven external scale-up Infinity Fabric links that it publishes for MI350X and MI355X OAM products. In an eight-card server, do not call the aggregate memory one flat HBM pool.
one card:
144 GB local HBM3E
4 TB/s local peak HBM bandwidth
eight cards, arithmetic only:
1,152 GB aggregate local HBM3E
32 TB/s aggregate local peak HBM bandwidth
3.6 kW configurable accelerator-board sum
4.8 kW maximum accelerator-board TBP sum
[TOUCHDOWN DERIVATION] The eight-card values are multiplication across eight separate cards. They are not one 1.152 TB address space, one shared 32 TB/s interface, complete server power, or measured workload performance. Independent replicas and tenant placement can use separate local memory domains. Model, tensor, expert, or sequence shards that span cards must cross the qualified server topology, and communication-heavy scaling needs its own PCIe and peer-transfer receipt.
Compatibility with an existing data center. The card uses a familiar PCIe, full-height, double-slot, passive-air-cooled server form. That reduces the mechanical and facility jump relative to an OAM baseboard or liquid-cooled rack. It does not make installation automatic.
The operator still has to qualify:
- the exact OEM server, BIOS, BMC, and GPU firmware;
- slot spacing, retention, service access, and a front-to-back fan curve for a passive 600 W card;
- 12V-2x6 cabling, branch power, PSU capacity, redundancy, and conversion loss;
- PCIe 5.0 x16 lanes, root complexes, switches, NUMA locality, and peer behavior;
- CPU, host DRAM, NIC, storage, and virtualization balance;
- Linux, ROCm, framework, container, Kubernetes or OpenShift, and GPU Operator versions;
- page retirement, page avoidance, SR-IOV, monitoring, failure isolation, and recovery;
- sustained inlet temperature, component temperature, throttling, noise, and error behavior under the real workload.
Eight cards can occupy 3.6 to 4.8 kW of accelerator-board power before CPUs, DRAM, NICs, storage, fans, PSUs, and losses. Passive cooling means the server fans move the heat. It does not mean cooling power is zero.
[ARCHITECTURE ONLY / RUN NOT CAPTURED] Touchdown has not captured an MI350P run_id, useful HBM counters, PCIe traffic, peer-transfer p99, node power, thermal behavior, accepted-task throughput, or cost per accepted task. The first receipt must join the exact server and card topology to firmware, ROCm, engine, model, precision, HBM allocation, transfer bytes, latency, power, temperature, throttling, retries, and the accepted output.
MI350P versus the RTX 6000 family: trace one workload before comparing ratios
WORKLOAD COMPARISON · INPUT-DRIVEN · NO WINNER WITHOUT A MATCHED RECEIPT
Start with the user. A developer asks an agent to inspect a repository, change code, run tests, repair failures, and return a reviewable patch. The model path creates weights, prompt state, active KV or architecture-specific attention state, workspaces, and communication buffers. The tool path leaves the accelerator for CPU search, file I/O, editing, compilation, tests, and review. The accepted patch, not a peak specification, is the final denominator.
- Hermes assembles system instructions, tool schemas, repository context, and the user's request.
- GLM-5.2 FP8 weights are sharded across local accelerator-memory domains. Its 744-billion-parameter FP8 weight floor is 744 GB decimal before scales, unquantized modules, padding, workspaces, graph buffers, attention state, and fragmentation.
- The serving engine performs prefill, sparse-MoE routing, decode, and the cross-card communication required by the exact placement.
- The workflow returns to the CPU for search, edits, tests, and logs, then adds new context for another model turn.
- A verifier accepts or rejects the patch. Retries, failed tests, tool time, GPU time, and energy remain part of the cost.
[TOUCHDOWN CAPACITY DERIVATION, NOT A RUN] The ideal 744 GB FP8 weight floor requires at least six 144 GB MI350P cards or eight 96 GB RTX PRO 6000 Server cards by raw capacity arithmetic. Eight MI350P cards provide 1,152 GB across eight separate HBM3E domains, leaving a 408 GB arithmetic remainder over that floor. Eight RTX PRO 6000 Server cards provide 768 GB across eight separate GDDR7 domains, leaving 24 GB before every runtime allocation. Neither aggregate is one flat pool. The calculation does not prove engine support, kernel correctness, communication performance, attention-state residency, or an accepted result.
| Exact product | Local memory | Published peak local bandwidth | Board power envelope | Host interface and role |
|---|---|---|---|---|
| AMD Instinct MI350P | 144 GB HBM3E; 128 MB last-level cache | 4,000 GB/s | 450 W configurable; 600 W maximum TBP | PCIe 5.0 x16; passive dual-slot enterprise card |
| NVIDIA RTX PRO 6000 Blackwell Server Edition | 96 GB GDDR7 ECC | 1,597 GB/s | Configurable up to 600 W | PCIe Gen 5; air or liquid server form; MIG up to four instances |
| NVIDIA RTX PRO 6000 Blackwell Workstation Edition | 96 GB GDDR7 ECC | 1,792 GB/s | 600 W maximum | PCIe Gen 5; workstation graphics, media, AI, and local model development |
| NVIDIA RTX PRO 6000 Blackwell Max-Q Workstation Edition | 96 GB GDDR7 ECC | 1,792 GB/s | 300 W maximum | PCIe Gen 5; lower-power workstation configuration |
| NVIDIA RTX 6000 Ada Generation | 48 GB GDDR6 ECC | 960 GB/s | 300 W maximum | PCIe 4.0 x16; earlier Ada workstation product |
What the specification sheet can say. MI350P has 48 GB more local memory than RTX PRO 6000 Server and 2.50 times its published peak local-memory bandwidth. Dividing peak bandwidth by a maximum board-power envelope produces 6.67 versus 2.66 GB/s per watt at 600 W. That is only a specification-envelope quotient. It is not measured useful bandwidth, tokens per watt, joules per token, node energy, or application efficiency.
HBM3E, GDDR7, DDR5, and LPDDR5X are different tiers. MI350P HBM3E and RTX PRO 6000 GDDR7 are accelerator-local memory. A conventional PCIe server reaches host DDR through its CPU, root complex, switches, and PCIe path. LPDDR5X belongs only when the named host actually contains it, such as a Grace-based system. Neither compared card includes LPDDR5X. Moving a prefix, weights, or attention state to a host tier changes capacity, but it also adds lookup, serialization, transfer, NUMA, page-pinning, latency, and CPU-memory power boundaries.
One reproducible RTX server result, and why it still cannot answer tokens per watt
[REPRODUCIBLE EXTERNAL RECEIPT, DIFFERENT WORKLOAD] MLPerf Inference v5.1 contains an HPE closed-division submission for one HPE ProLiant Compute DL380a Gen12 with eight RTX PRO 6000 Blackwell Server Edition cards, two Intel Xeon 6787P CPUs, 2,048 GB host memory, TensorRT 10.11.0.33, CUDA 12.9, and driver 575.57.08. Its Llama 2 70B 99% Server result is 26,005.90 tokens/s at the eight-GPU system boundary. It is not a single-card result, not C-001, and the submission does not include measured system power, price, or an accepted-patch denominator. The system JSON also labels accelerator memory as HBM2e, which conflicts with NVIDIA's official GDDR7 specification. The official NVIDIA product page controls the memory type.
No equivalent MI350P result was found that joins the exact model revision, precision, runtime, prompt and output lengths, concurrency, latency target, quality gate, board and node power, and price. A cross-vendor tokens-per-watt claim therefore remains unknown.
Primary and reproducible sources: AMD MI350P, MI350P brochure, RTX PRO 6000 Server, RTX PRO 6000 Workstation, RTX PRO 6000 Max-Q, RTX 6000 Ada, and MLPerf Inference v5.1 HPE result.
The two maintained internal vendor registries preserve the full claim history, source links, unknown fields, command paths, and update rules: 2026-07-10-amd-instinct-platform-engineering-ssot.md, 2026-07-10-nvidia-accelerator-platform-engineering-ssot.md, and 2026-07-10-amd-nvidia-platform-ssot-index.md. These internal draft files are evidence routers. The cited primary vendor page still controls if a specification changes.
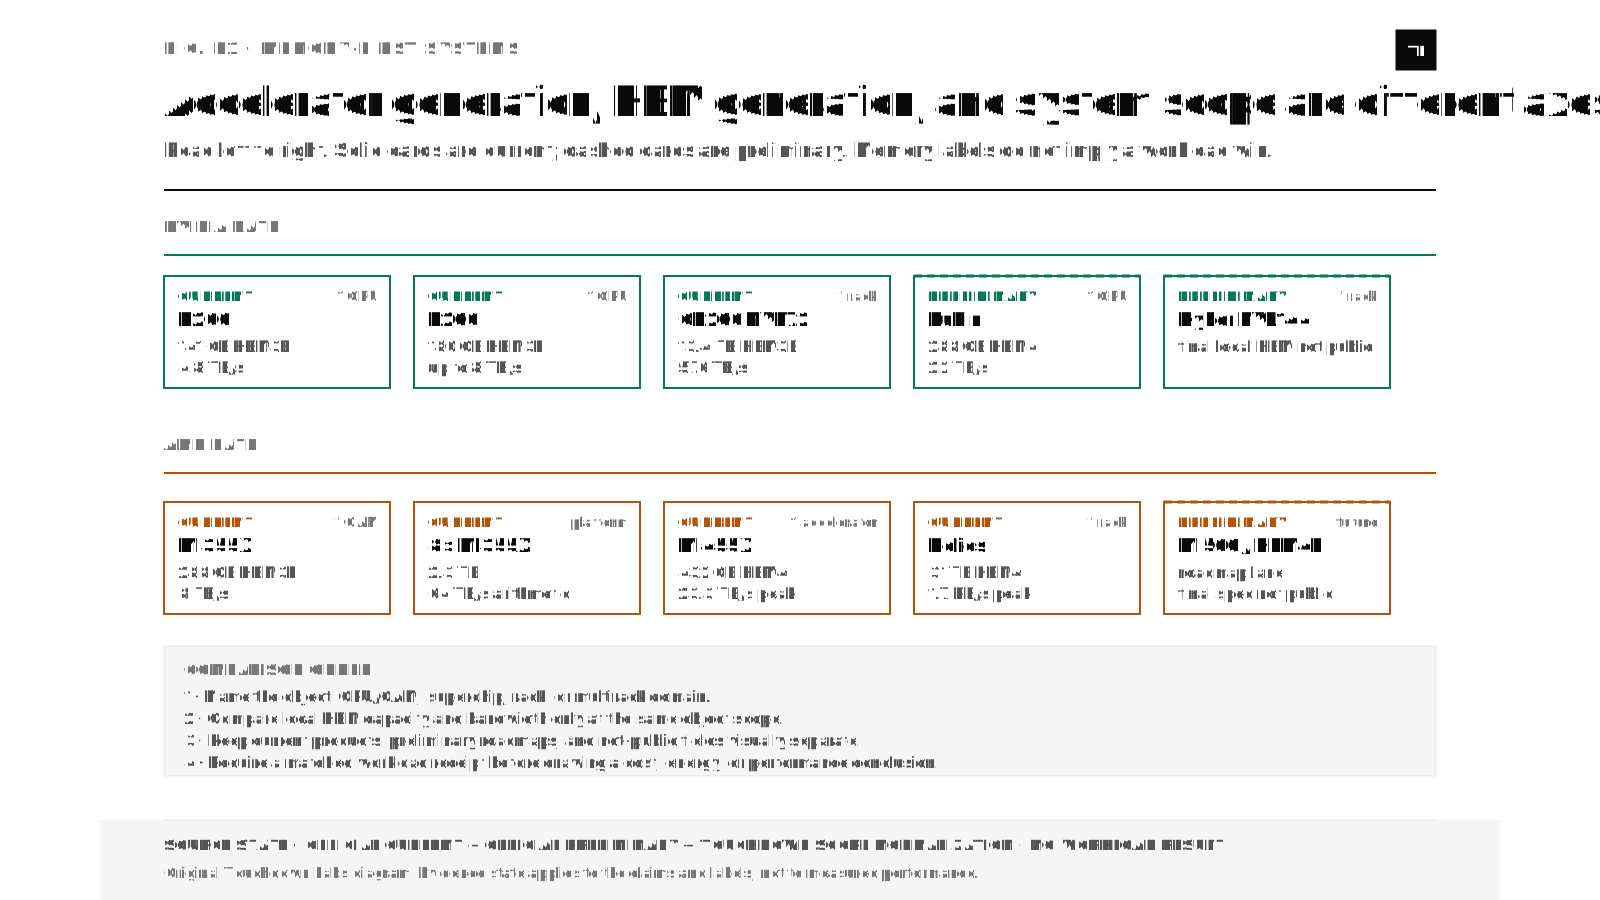
AMD and NVIDIA expose two native software and fabric paths
The hardware is not interchangeable below the framework. A PyTorch model can look portable while the actual fast path changes at the operator library, compiler target, collective library, topology, network endpoint, and offload layer.
Before tracing those software branches, freeze the CPU-to-accelerator topology. Coherent addressing can make two memory domains easier to program without making their physical latency, bandwidth, capacity, or power identical.
| Named system boundary | CPU-side memory | Accelerator-local memory | CPU-to-accelerator path | What remains topology-specific |
|---|---|---|---|---|
| Grace plus Blackwell in a GB200 Superchip | Grace LPDDR5X | Blackwell HBM3E | Coherent NVLink-C2C | Actual page placement, remote access, cache behavior, transfer counters, and task latency |
| Vera plus Rubin | Vera LPDDR5X | Rubin HBM4 | NVIDIA describes coherent second-generation NVLink-C2C | Delivered-system topology, placement policy, sustained behavior, and matched workload evidence |
| Conventional MI350P PCIe server | The qualified host's DDR and NUMA domains | 144 GB card-local HBM3E | PCIe 5.0 x16 | OEM slot wiring, NUMA route, peer path, useful transfer rate, airflow, power, and runtime qualification |
| MI355X OAM or UBB platform | The exact qualified host-memory tier | 288 GB local HBM3E per accelerator | Platform-specific host and Infinity Fabric topology | The orderable server, firmware, ROCm, peer, collective, cooling, and failure-domain contract |
| MI455X and Helios | Venice is the CPU and control boundary; the exact installed host-memory configuration belongs to the OEM or ODM system | 432 GB HBM4 per MI455X | The published platform separates CPU control, GPU scale-up, scale-out networking, and storage boundaries | Do not infer a universal CPU-to-MI455X link, coherent placement rule, or useful transfer rate from the rack name alone |
The current AMD path is:
request, training step, or diffusion step
-> PyTorch, JAX, vLLM, or SGLang
-> ROCm and HIP
-> AITER, Triton, Composable Kernel, hipBLASLt, or rocBLAS
-> RCCL or rocSHMEM
-> XCD cache and local HBM
-> Infinity Fabric scale-up
-> NIC and scale-out network
-> CPU DDR, NVMe, object storage, or a version-supported offload tier
The current NVIDIA path is:
request, training step, or diffusion step
-> PyTorch, JAX, TensorRT-LLM, vLLM, or SGLang
-> serving engine, Dynamo, KVBM, LMCache, or HiCache policy where configured
-> CUDA, CUTLASS, cuBLASLt, cuDNN, and engine kernels
-> local HBM for the active working set
-> NCCL collectives where the operation spans GPUs
-> NIXL orchestration where a tensor or KV object must move
-> selected backend such as UCX or libfabric
-> NVLink, PCIe, or an RDMA path
-> ConnectX or BlueField endpoint, switch, and network
-> destination HBM, CPU memory, storage, or CMX
[OFFICIAL CURRENT SOFTWARE PATHS, VERSION-SENSITIVE] AMD documents current ROCm architecture targets, AITER, RCCL, vLLM, and SGLang support surfaces for Instinct products. NVIDIA and the named open-source projects document CUDA, NCCL, TensorRT-LLM, vLLM, SGLang, Dynamo, NIXL, LMCache, and the CMX direction. A feature in documentation is not proof that the pinned model, kernel, connector, and hardware combination works. The receipt needs package versions, container digest, GPU architecture, launch command, topology, and logs.
That NVIDIA path is a set of conditional branches, not one mandatory sequence. A local single-GPU operation may touch none of NCCL, NIXL, a NIC, a DPU, or storage. A distributed or offloaded request must name which branch executed.
NIXL is software that coordinates transfer. NVLink is a physical/link scale-up fabric. NCCL is collective software. ConnectX is a NIC family. BlueField is a DPU and infrastructure-processing boundary that incorporates networking functions. LMCache is a KV-cache layer. CMX is an announced context-memory storage platform. On AMD, Infinity Fabric is the current scale-up path for MI300 and MI350 systems. UALink and UALoE belong to the launched Helios production reference design; the exact partner topology, ROCm package set, collective path, and workload behavior still require qualification. Do not label an MI355X UBB as UALink unless the exact orderable platform proves that topology.
| Network or infrastructure component | Role in the memory path | Platform or generation scope | Claim boundary |
|---|---|---|---|
| ConnectX-7 | NVIDIA NIC generation used in Hopper and early Blackwell-era system paths | Exact server and network configuration required | A NIC specification does not prove KV transfer, collective behavior, or accepted-task benefit |
| ConnectX-8 | NVIDIA 800 Gb/s-class NIC generation associated with GB300-era systems | Exact port, switch, rail, and transport configuration required | Peak link rate is not payload goodput or p99 |
| ConnectX-9 | NVIDIA NIC generation named for the Vera Rubin platform path | Roadmap or delivered-system state must remain explicit | Availability does not prove a selected backend or workload result |
| BlueField-4 | DPU and infrastructure processor with ConnectX-class networking functions in the Vera Rubin and CMX direction | Named platform and software stack required | It is not merely a NIC and does not become more local HBM |
| Pollara 400 | AMD Pensando AI NIC for existing Ethernet-cluster paths | Exact switch, ROCm, transport, and server configuration required | The product role does not prove that a workload used it |
| Vulcano 800 | AMD Pensando scale-out and scale-across NIC direction for Helios | Helios partner topology and delivery state required | Vendor link ceilings are not collective latency or application goodput |
| Salina | AMD Pensando DPU for infrastructure services | Selected system and software role required | A DPU is not an AI NIC, scale-up link, or local memory tier |
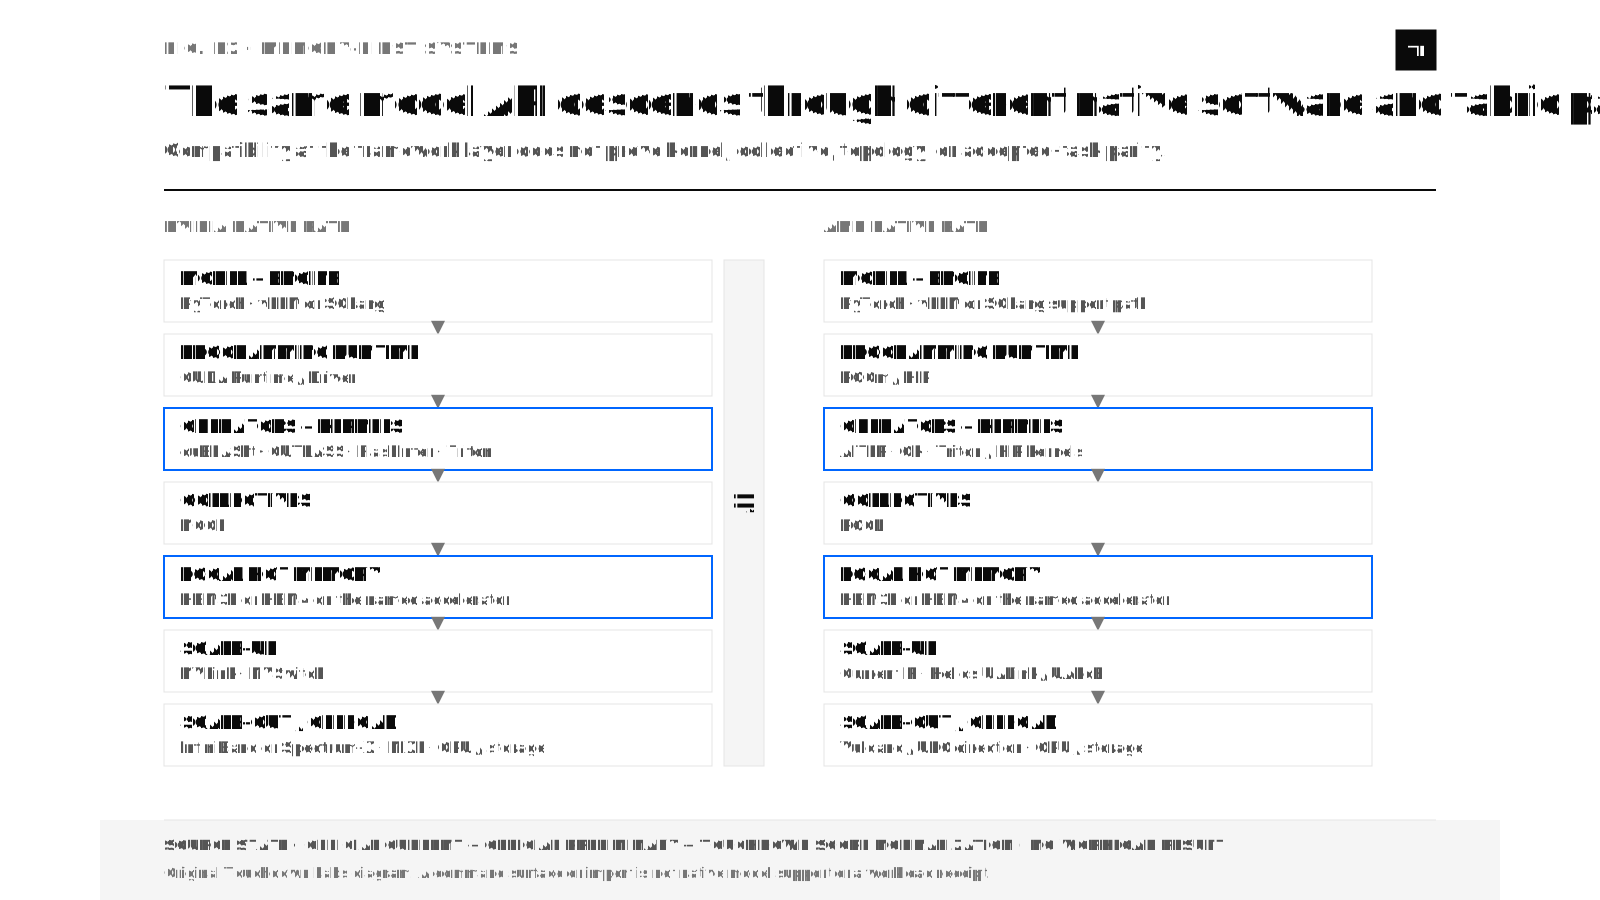
Keep current products separate from roadmap systems
Current orderable or production-described products and future systems answer different questions.
| Current product boundary | Memory and fabric fact | What still requires a workload receipt |
|---|---|---|
| AMD MI300X | 192 GB HBM3 and 5.3 TB/s per OAM; eight-GPU Infinity Fabric platform direction | sustained kernel bandwidth, RCCL topology, engine support, accepted output |
| AMD MI325X | 256 GB HBM3E and 6.0 TB/s per OAM; same gfx942 architecture family |
whether capacity avoids another shard or only increases idle memory |
| AMD MI350P | 144 GB HBM3E and 4.0 TB/s per PCIe card; 450 W configurable and 600 W maximum TBP; passive double-slot server form | OEM qualification, slot and NUMA topology, peer path, airflow, node power, useful HBM traffic, accepted output |
| AMD MI350X / MI355X | 288 GB HBM3E and 8.0 TB/s per OAM; gfx950; different 1,000 W and 1,400 W product envelopes |
cooling boundary, native kernel coverage, delivered throughput per watt |
| AMD MI455X / Helios | 432 GB HBM4 and 23.3 TB/s peak per accelerator; 31 TB and 1.7 PB/s aggregate peak across the 72-GPU production reference design | released gfx1250 qualification, selected operator and HSACO, useful HBM traffic, partner configuration, power, accepted output, and run_id |
| NVIDIA H100 / H200 | Hopper with 80 GB HBM3 or 141 GB HBM3e; NVLink 4 | whether added H200 capacity changes parallelism, KV residency, and cost |
| NVIDIA GH200 | Hopper HBM plus coherent Grace LPDDR5X through NVLink-C2C | page residency, remote access, offload overlap, TTFT and TPOT |
| NVIDIA B200 GPU | Blackwell GPU product boundary with HBM3E and NVLink 5 | installed memory configuration, selected kernel, useful bandwidth, power, and accepted result |
| NVIDIA HGX B200 | Eight B200 GPUs in an HGX baseboard and server-platform boundary | exact OEM server, CPU, host memory, NICs, cooling, topology, collective path, and task result |
| NVIDIA DGX B200 | Complete eight-B200 NVIDIA system boundary | delivered software image, operating configuration, node power, workload throughput, and accepted-work economics |
| NVIDIA GB200 Superchip | One Grace CPU plus two Blackwell GPUs connected through NVLink-C2C | placement across separate LPDDR5X and HBM3E domains, remote-access behavior, and matched workload result |
| NVIDIA GB200 NVL72 | 36 Grace CPUs and 72 Blackwell GPUs in a rack-scale NVLink domain | useful HBM and NVLink bandwidth, collective wait, rack utilization, facility power, and accepted-work economics |
| NVIDIA B300 / Blackwell Ultra | GPU-architecture and product boundary with up to 288 GB HBM3E | installed product configuration, sustained behavior, power, and accepted result |
| NVIDIA GB300 NVL72 | Blackwell Ultra rack boundary with approximately 20 TB aggregate GPU memory | reasoning or video result for the exact model, precision, quality gate, topology, and power boundary |
[TOUCHDOWN STRATEGY EXTRAPOLATION, NOT A BENCHMARK] The design signals become useful only when their pros and cons stay attached to the workload:
| Platform choice | Plausible use case to test | Design advantage | Trade-off or failure mode | Strategy signal, not a forecast |
|---|---|---|---|---|
| RTX 6000 Ada or RTX PRO 6000 Blackwell workstation variants | Local model development, graphics, visualization, media, CAD, and bounded inference | One card combines graphics, media, and AI functions with a mature workstation software path | 48 or 96 GB local memory can force smaller models, more quantization, more sharding, or more host movement | A mixed graphics and AI workload can value functions that a pure HBM capacity comparison ignores. |
| RTX PRO 6000 Blackwell Server Edition | Enterprise PCIe inference where 96 GB per card fits the selected shard and NVIDIA software is important | Familiar server form, GDDR7, MIG, and NVIDIA's deployment and inference stack | Less local capacity and lower published local bandwidth than MI350P; distributed state can amplify movement and communication | Software and deployment integration can compensate for a weaker paper memory ratio only if accepted-task throughput and operations prove it. |
| AMD MI350P | Air-cooled PCIe inference, private RAG, agent services, and incremental enterprise deployment where 144 GB local HBM changes the shard plan | More local memory and published bandwidth than the compared RTX PRO server card in a conventional PCIe form | Passive 600 W maximum card, OEM airflow, PCIe topology, ROCm versioning, kernel coverage, and peer behavior all require qualification | AMD can compete by making larger local HBM available without forcing the buyer directly into an OAM baseboard or liquid-cooled rack. |
| NVIDIA B200 or B300 systems | Large training, inference, and reasoning workloads that benefit from an integrated NVIDIA server and software boundary | Qualified system architecture, NVLink, mature libraries, management, and broad deployment support | High system and facility commitment, vendor-specific integration, and no guarantee that the workload uses peak HBM or compute | Integration reduces time and qualification risk, which can be worth more than an isolated component ratio. |
| AMD MI355X systems | Memory-heavy training or inference where 288 GB and 8 TB/s per OAM reduce shards or preserve more hot state locally | Large HBM3E capacity and bandwidth per accelerator with an eight-GPU platform path | 1,400 W product envelope, liquid cooling, exact server topology, ROCm and operator coverage, collectives, and support are workload-specific | More state per accelerator can reduce communication or increase batching, but only if the software uses it and the facility can sustain it. |
| NVIDIA GB200 or GB300 NVL72 | Rack-scale training, inference, and reasoning that benefit from Grace CPUs, LPDDR5X, coherent CPU-GPU access, NVLink, and one integrated system | CPU memory, HBM, scale-up, networking, software, and operations are designed together | The rack is a large power, cooling, networking, and operational boundary. Coherence does not erase placement cost. | NVIDIA is selling a memory and data-movement system, not only GPUs. The value must still close at the accepted workload. |
| AMD MI455X and Helios | Frontier training and inference where 432 GB HBM4 per accelerator and a 72-GPU open reference design change model or state placement | Very large published local and rack HBM capacity and bandwidth, plus an open OEM or ODM system direction | Exact partner configuration, released software qualification, useful HBM and UALoE behavior, rack power, cooling, reliability, and cost remain unproved here | AMD is attacking the rack-scale memory boundary directly. The strategic question is whether open system choice and HBM scale convert into faster qualification and accepted-work economics. |
The roadmap stays separate:
| Roadmap system | Source-backed statement | Unknown that must remain unknown |
|---|---|---|
| AMD MI430X | AMD names 432 GB HBM4 and 19.6 TB/s in the product context | final package, power, broad availability, delivered application result |
| AMD MI440X | AMD names an eight-GPU enterprise deployment role | final HBM, bandwidth, fabric, power, price |
| AMD MI450 Series / MI450X and other MI400 members | AMD uses source-specific family and architecture labels alongside the launched MI455X | whether those labels are equivalent to MI455X, final member taxonomy, member-specific configuration, qualification, and delivered performance |
| AMD MI500 family | AMD names CDNA 6, 2 nm, HBM4E, and a planned 2027 generation | capacity, bandwidth, package, power, scale-up topology, shipping system |
| NVIDIA Vera Rubin NVL72 | NVIDIA says the platform is in production while its published specification table remains explicitly preliminary | final non-preliminary values and customer-specific availability |
| NVIDIA Rubin Ultra NVL576 | eight 72-GPU MGX NVL racks in one announced scale-up domain | final Rubin Ultra GPU, HBM, power, delivered multirack behavior |
| NVIDIA Rubin Ultra Kyber NVL144 | one 144-GPU next-generation MGX NVL rack | PCB qualification, yield, rack power, final GPU specification, customer schedule |
| NVIDIA Feynman Kyber NVL1152 | eight 144-GPU Kyber racks in one announced domain | Feynman GPU, HBM, process, power, availability, workload result |
The MI450 naming boundary matters. AMD's own current public material uses MI450 Series, MI450 architecture, MI450X, and MI455X in different official contexts. The relationship is [NOT PUBLIC] until AMD publishes a final taxonomy. The safe move is to retain the exact source label, not normalize all four into one fictional SKU.
The Rubin boundary matters for the same reason. A current NVIDIA statement that the Vera Rubin platform is in production can coexist with a product table marked preliminary. Production status and specification finality are separate fields.
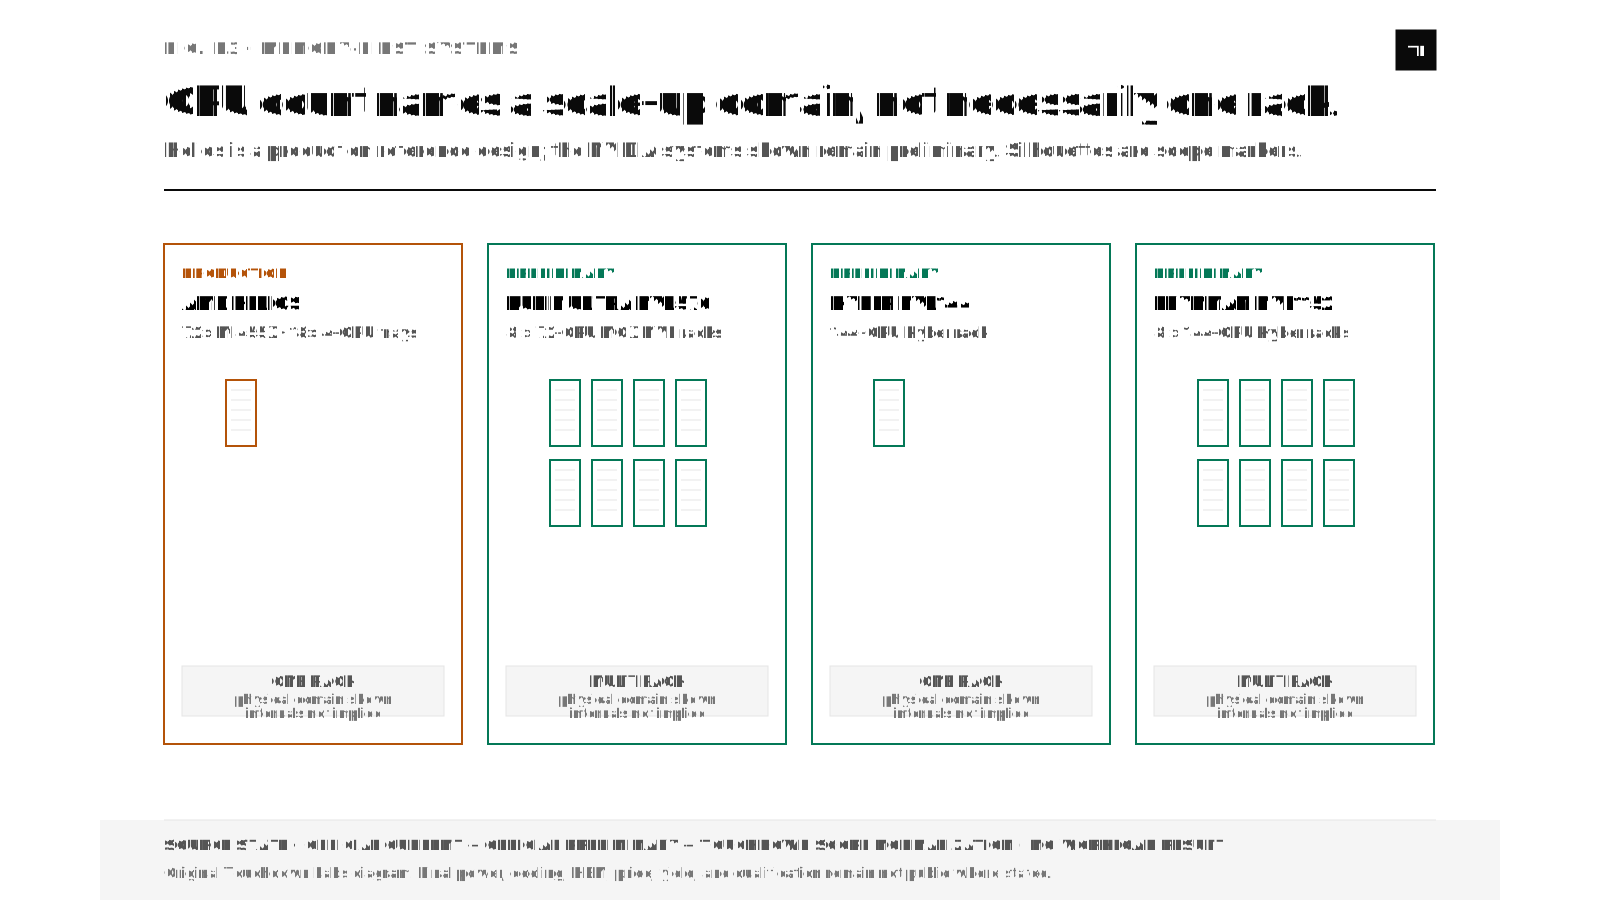
A native-support claim needs more than an import
The complaint that AMD software has not caught up is too vague to be useful. It mixes six separate questions: Can the framework express the workload? Does the compiler target the exact GPU? Does a tuned operator exist for the exact shape and precision? Do collectives match the installed topology? Can the serving and placement layers move state correctly? Can an operator deploy, observe, recover, and get support for the whole configuration?
AMD has made concrete progress. ROCm and HIP expose a broad framework and programming path. PyTorch, JAX, vLLM, and SGLang have AMD surfaces. AITER, Composable Kernel, Triton, hipBLASLt, rocBLAS, MIOpen, RCCL, rocSHMEM, and MoRI cover different operator, compiler, collective, and communication jobs. ROCm profiling and system-management tools expose additional diagnostics. AMD also publishes open source and source-level architecture signals that make the stack inspectable.
NVIDIA's current advantage is not captured by saying CUDA has more libraries. The stronger claim is integration depth across qualified hardware, CUDA, mature operator coverage, compiler and engine paths, NCCL, TensorRT-LLM, Dynamo, NIXL, observability, OEM systems, deployment tooling, and support. Even that advantage is workload-specific. A library existing in CUDA does not prove that the selected model, precision, kernel, topology, and memory policy are correct or economical.
| Software and operations layer | AMD current advancement | NVIDIA current integration | What is current, projected, or still unproved |
|---|---|---|---|
| Framework and serving surface | ROCm, HIP, PyTorch, JAX, vLLM, SGLang, and AMD Inference Microservices expose supported paths on named current products | CUDA frameworks, TensorRT-LLM, vLLM, SGLang, Dynamo, and NVIDIA AI Enterprise expose multiple supported paths on named current products | Package presence is current architecture evidence. Exact model revision, engine version, precision, and accepted output still require a run. |
| Operators and kernels | AITER, Composable Kernel, Triton, hipBLASLt, rocBLAS, MIOpen, and other domain libraries provide different tuned or lower-level paths | CUTLASS, cuBLASLt, cuDNN, TensorRT kernels, Triton, and engine-specific kernels provide different tuned or lower-level paths | Coverage is shape, datatype, architecture, and version specific. A fallback kernel can run correctly while leaving much of the memory or compute ceiling unused. |
| Compiler and device code | HIP, LLVM, COMGR, HSACO code objects, ROCr/HSA, and amdgpu/KFD form the current AMD lowering and dispatch path | CUDA compilation, PTX, SASS, cubins, the CUDA driver, and architecture-specific device code form the current NVIDIA path | MI455X gfx1250 source bring-up signals are not a released qualification packet. A target string is not proof of selected device code or dispatch. |
| Collectives and scale-up | RCCL, rocSHMEM, MoRI, Infinity Fabric, and the launched UALink or UALoE Helios direction cover different communication layers | NCCL, NVLink, NVSwitch, and the named rack topology cover different communication layers | A collective library is not a fabric. The receipt needs the exact graph, message sizes, topology, p50, p95, p99, retries, errors, and useful overlap. |
| Placement, KV, and external memory | vLLM or SGLang policy, LMCache, host memory, VAST, NFS over RDMA, and storage can form a remote-state path when configured | Dynamo, KVBM, LMCache or HiCache, NIXL, host memory, BlueField, and the announced CMX path can form different remote-state paths when configured | VAST's MI355X result is a vendor-reported named benchmark. CMX is an announced direction. Neither proves lower total energy or cost for C-001 or V-001. |
| NICs, DPUs, and specialized infrastructure compute | Pollara or Vulcano NICs and Salina DPUs can own named transport and infrastructure functions | ConnectX NICs and BlueField DPUs can own named transport and infrastructure functions | These components can remove work from the host CPU or change the movement boundary. They do not increase local HBM, become the scale-up fabric, or prove an application gain by existing. |
| Deployment and operations | ROCm containers, operators, system management, profiling, RAS, OEM qualification, and support matrices are moving the stack toward repeatable deployment | NVIDIA's software distribution, management, diagnostics, OEM qualification, and support integration are broader on many deployed configurations | Operational maturity must be scored per configuration: install, upgrade, observability, failure isolation, rollback, replacement, security, support, and accepted workload. |
Current versus projected software must stay separate. The current MI350P and MI355X rows can be evaluated against released ROCm packages and qualified OEM systems. The launched MI455X and Helios hardware direction has public source bring-up and vendor day-zero support language, but the article has no released, joined MI455X workload packet. Current Blackwell systems can be evaluated against released NVIDIA software and delivered configurations. Vera Rubin, BlueField-4 STX, and CMX contain current vendor architecture statements alongside preliminary, announced, or configuration-dependent fields. Neither vendor earns a future workload result from a current diagram.
The useful buyer question is therefore not whether AMD software is good or bad. It is: for this model, operation, precision, server, topology, and service-level objective, which exact path is qualified, what falls back, what can be observed, what fails, and who fixes it?
For either vendor, call a workload native_supported only when this packet exists:
model:
id: null
revision: null
tokenizer_revision: null
runtime:
framework: null
engine: null
engine_version: null
container_digest: null
hardware:
vendor: AMD_or_NVIDIA
exact_product: null
architecture_target: null
hbm_capacity_gb: null
topology:
scale_up: null
scale_out: null
gpu_ids: []
execution:
precision: null
tp: null
pp: null
ep: null
cp_or_sp: null
receipts:
launch_log: null
topology_snapshot: null
profiler_trace: null
collective_test: null
accepted_output: null
power_log: null
metrics:
throughput: null
p95_latency: null
p99_latency: null
accepted_tasks_per_hour: null
cost_per_accepted_task: null
An installed ROCm or CUDA package is parser_only evidence for the environment. A synthetic fixture can be fixture_backed. A real model that completes with captured topology and diagnostic artifacts is live_validated. Release readiness adds documentation, failure modes, supported versions, packaging, CI, and rollback. That state model prevents a software import from becoming a false claim of full AMD or NVIDIA coverage.
The generational path exposes several different engineering bets:
- H100 to H200 increases local memory capacity and bandwidth while keeping the Hopper compute generation. This is a clean example of memory changing the usable workload envelope without changing every compute block.
- GB200 makes the unit of discussion a 72-GPU liquid-cooled rack with Grace CPUs, LPDDR5X, NVSwitch, networking, power shelves, and facility requirements. HBM is now one tier inside a rack computer.
- GB300 increases HBM capacity and targets reasoning and attention-heavy use, but the application still needs scheduling and placement that turn capacity into goodput.
- Vera Rubin moves to HBM4 and doubles the published rack-level NVLink bandwidth relative to Blackwell NVL72. It also introduces a new CPU, networking, DPU, storage, power, and cooling context. A GPU-only comparison misses the system change.
- Kyber changes the physical rack and scale-up domain. Doubling GPUs per rack increases the number of local placement choices, collective participants, links, failure combinations, power-delivery constraints, and service operations. It does not make 144 HBM pools one uniform load/store address space for arbitrary code.
- AMD MI355X emphasizes very large HBM3E capacity per OAM and an eight-GPU UBB path. MI455X is launched, and Helios is an AMD production 72-GPU OEM/ODM reference design with HBM4 and UALink/UALoE. AMD says partner-system shipments are scheduled to start at the end of Q3 and ramp into Q4 2026. MI500 names the next memory generation but still lacks a public production specification.
For procurement or architecture, the row needs these additional fields before a decision:
exact orderable SKU and availability
GPU and HBM lot / revision
usable capacity after runtime reservation
sustained bandwidth for the named kernel mix
scale-up and scale-out topology
collective p50 / p95 / p99 by message size
board, tray, rack, and facility power boundaries
coolant and water accounting boundaries
software versions and supported models
accepted-workload throughput, latency, quality, and failure rate
price, support, deployment labor, spares, and utilization
Custom HBM and SPHBM4: more control, more obligation
[STANDARD] Standard Package High Bandwidth Memory (SPHBM4) is JEDEC JESD330-4. Its public record describes an HBM4-stack direction with a different buffer/interface die for standard-package integration. The standard does not by itself prove a shipping product or workload result. This article links the unrestricted public record but does not reproduce standard text or tables.
[VENDOR ROADMAP / DESIGN SURFACE] Marvell publicly describes a custom-HBM compute architecture. The significance is not a fixed partition. It is that a system designer may be able to move selected controller, security, RAS, telemetry, data-movement, or near-memory functions into the base/interface layer.
That possibility creates a full engineering burden:
- What exact function moves, and why is the base die better than the accelerator or software?
- What traffic does it avoid at which boundary?
- How does software invoke it and fall back?
- What is the added logic area, power, thermal density, and verification cost?
- What changes in test, repair, fault containment, and field update?
- Who supplies and qualifies the design?
- What non-recurring engineering and volume make it economic?
No public source reviewed for this article proves that Touchdown can order custom HBM, that a startup gets access on useful terms, or that one custom partition wins. Those remain diligence questions.
Intel XBM, claim by claim
[PATENT APPLICATION] The source calls it XBM, expanded in the description as cross-batch memory. It is not XBEM, and this document does not call it extreme bandwidth memory.
The public record is US 2026/0191095 A1, application 19/001,921, titled Ultra High Bandwidth Memory With Backend Transistors. The application was filed December 26, 2024 and published July 2, 2026.
Intel did not launch an XBM product in this publication. A patent application can still matter because it shows architectural territory the applicant considered worth describing and claiming. It does not show that the device works, a package yields, software exists, customers can buy it, or economics beat HBM4.
The filing describes several coupled ideas:
| Ingredient | What the application describes | Why it is interesting | What remains unknown |
|---|---|---|---|
| Backend-transistor 1T1C DRAM | Memory dies with DRAM devices using backend transistors | Changes cell and interconnect integration space | Density, retention, speed, leakage, variability, thermal budget, yield |
| Fine subchannels and datablock regions | Smaller independently useful organizational regions | May expose request parallelism or reduce unnecessary activation | Controller efficiency, queueing, real workload use |
| TSV gutters | Via regions between datablock regions | Couples vertical delivery to floorplanning | Area, stress, routing, heat, yield |
| Base-die options | Embodiments with base logic and different mounting organizations | Opens PHY, routing, test, repair, package control | Which embodiment, if any, becomes a product |
| UCIe-facing links | Serialized die-to-die package links, including a 32 GT/s example | Separates internal memory parallelism from package-facing serialization | Lane count, payload efficiency, latency, power, generation, interoperability |
| BIST, redundancy, repair | Per-die test and spare subchannel/datablock examples | Makes manufacturing recovery part of architecture | Coverage, repair granularity, area, performance, qualification |
| Package variants | Interposer and other package organizations in figures | Broadens integration choices | Signal integrity, PDN, heat, assembly, cost |
The key distinction is that serialized outside does not mean serial inside. The memory can retain substantial internal parallelism while a base die or distributed logic arbitrates traffic onto high-speed package-facing links.
That creates a raw bandwidth check. The original public HBM4 reference point used in the existing research is 8 Gb/s across 2,048 bits:
8e9 transfers/s * 2,048 bits / 8
= 2.048 TB/s raw
one ideal 32 GT/s lane-equivalent
= 32 Gb/s
= 4 GB/s raw
2.048 TB/s / 4 GB/s
= 512 ideal raw lane-equivalents
[TOUCHDOWN DERIVATION] The 512 result assumes one raw bit per transfer, one direction, and 100 percent efficiency. It is not an Intel physical lane count, not a UCIe payload result, and not a product topology. The filing includes a 64 by 32 GT/s callout in one figure, while total bundles, duplex behavior, protocol overhead, retry, arbitration, and sustained application bandwidth remain unknown.
The 32 GT/s filing example is also not a current UCIe ceiling. [STANDARD] The UCIe Consortium's public specifications page lists later 48 and 64 GT/s capability in UCIe 3.0. The architecture must treat link rate as a versioned target parameter, not a frozen identity.
The real questions are harder than raw division:
- How many physical lanes and bundles operate in each direction?
- What fraction becomes payload after framing, flow control, retry, repair, and idle cycles?
- What first-byte and tail latency come from serialization, arbitration, and turnarounds?
- What is energy per useful transferred bit at the link and system boundaries?
- Can base logic sustain mixed reads and writes without becoming the bottleneck?
- How do backend transistors behave across retention, leakage, variation, temperature, aging, and test?
- What package cost is removed or added in the chosen embodiment?
- How well do BIST, redundancy, and repair improve usable yield?
Do not say XBM eliminates an interposer. One filing figure uses an interposer. The safe claim is that described embodiments create multiple package choices, some of which may reduce dependence on a conventional HBM-style interposer.
Do not publish the filing's illustrative capacity language as a committed product. Do not publish bandwidth, latency, energy, thermals, yield, cost, qualification, availability, or schedule as measured. Those fields are null until evidence exists.
# [PATENT APPLICATION] Claim boundary
artifact: US-2026-0191095-A1
described_architecture: source_backed
measured_silicon: false
product_commitment: false
bandwidth_latency_energy_yield_cost: null
touchdown_analysis:
raw_lane_equivalence_only: true
physical_lane_count: null
XBM is important because it makes memory cells, internal organization, controller behavior, repair, package links, and topology one architecture search space. It is not important because it has already beaten HBM. It has not established that.
GDDR7, DDR5, and LPDDR5X: DRAM is not one interface
GDDR7 uses discrete graphics-memory devices and high per-pin signaling to provide board-level graphics bandwidth. Vendor pages describe PAM3 signaling and named part data rates. [VENDOR PRODUCT] Those figures are useful for a named device and bus width. A system comparison still needs device count, aggregate interface width, board routing, power, capacity, controller, and workload.
GDDR can be attractive when a design values a different package and cost structure from HBM. Its narrower aggregate interface and higher per-pin rate change signal integrity, power, board area, and controller choices. HBM is faster or GDDR is cheaper without a complete system is too high level.
DDR5 is the host-memory baseline for many servers. DIMMs provide large, serviceable CPU-visible capacity through the host memory controller. The path from a GPU to host DDR can cross an accelerator link, PCIe or another fabric, CPU root complex, NUMA topology, and memory controller. The capacity can be useful while the movement deadline still fails.
LPDDR5X is designed around lower-power I/O and capacity-density trade-offs and is widely associated with mobile and client systems. It also appears in data-center design discussions because power and memory capacity matter there. LPDDR is not a drop-in HBM or DDR DIMM replacement. It changes packaging, soldered-down serviceability, controller support, channel organization, capacity, bandwidth, and system architecture.
The comparison is therefore role-specific:
- HBM favors the widest, closest accelerator-local hot tier.
- GDDR favors high board-level graphics bandwidth under a different package and per-pin trade.
- DDR favors large, serviceable host working memory.
- LPDDR favors power and capacity-density directions under a different integration model.
CXL memory: capacity with a fabric contract
[STANDARD] The CXL Consortium's unrestricted public overview describes a cache-coherent interconnect built on PCIe physical infrastructure and capabilities for processors, accelerators, and memory expansion. Different device types, generations, switches, and system topologies expose different functions.
CXL-attached memory can expand addressable capacity, support pooling or sharing in applicable systems, and create another software placement option. It does not become HBM by joining the address space.
[VENDOR PRODUCT ARTIFACT] Samsung's MD210 CMM-D product page lists a named CXL memory product with Mass Production status. That establishes a vendor product state, not a workload result or a universal CXL latency and bandwidth profile.
The path still has link serialization, switch or topology effects, controller queues, coherency behavior, media access, contention, RAS, and software policy. The first byte and full object can arrive later than local HBM. Whether that is acceptable depends on the object and lookahead.
Warm tier is a workload-placement description in this article. It is not a CXL standards category.
We deliberately do not process, quote, or summarize the CXL 4.0 evaluation-specification download because its agreement restricts AI processing and use. We use the consortium's unrestricted public overview and announcements. We also do not reproduce JEDEC standard tables.
NVMe, NAND, and HBF: capacity changes granularity
NVMe exposes block storage over an efficient host/controller protocol. The underlying NAND can hold large durable state without power. It is the natural home for repositories, checkpoints, model files, cold cache, logs, and outputs.
It is not a transparent HBM extension. The path can include a filesystem, page cache, block layer, NVMe queue, SSD controller, flash translation layer, NAND page read, error correction, DMA, and destination allocation. Direct-storage paths can remove some CPU copies, but they do not erase first-byte latency, page granularity, contention, or endurance.
[VENDOR TARGET / BENCHMARK] Sandisk's HBF fact sheet proposes a high-bandwidth flash direction and reports projected capacity/bandwidth plus internal Llama simulation. Those are vendor claims. [STANDARDIZATION WORKSTREAM] SK hynix and Sandisk separately announced an OCP standardization effort. Neither establishes shipping HBF.
[PHYSICAL PROTOTYPE] Kioxia announced a separate high-bandwidth flash module prototype with its own capacity and bandwidth boundary. That is evidence of a physical prototype. It is not the Sandisk HBF product, and it is not an AI workload result.
The right HBF question is not Can flash replace HBM? It is Can a predictable, read-mostly, page-useful state stream arrive ahead of demand while a smaller hot tier holds mutable working state?
Emerging memories: candidates need a state role
PCM, ReRAM/RRAM, MRAM, FeFET, gain-cell, oxide-semiconductor and related research families offer different combinations of density, retention, write cost, endurance, analog behavior, and process integration.
That design space is real. It is also easy to misuse. A cell paper can measure one device under one condition without proving an array, controller, ECC, package, compiler, yield, or product. A nonvolatile bit can still have an expensive write. A dense cell can still have variability. A compute-in-memory primitive can still lose on data conversion, routing, precision, programming, or utilization.
The article therefore does not choose a Touchdown material stack. A candidate enters only with a named state role, device/array evidence, controller and software contract, thermal/process path, and merchant baseline.
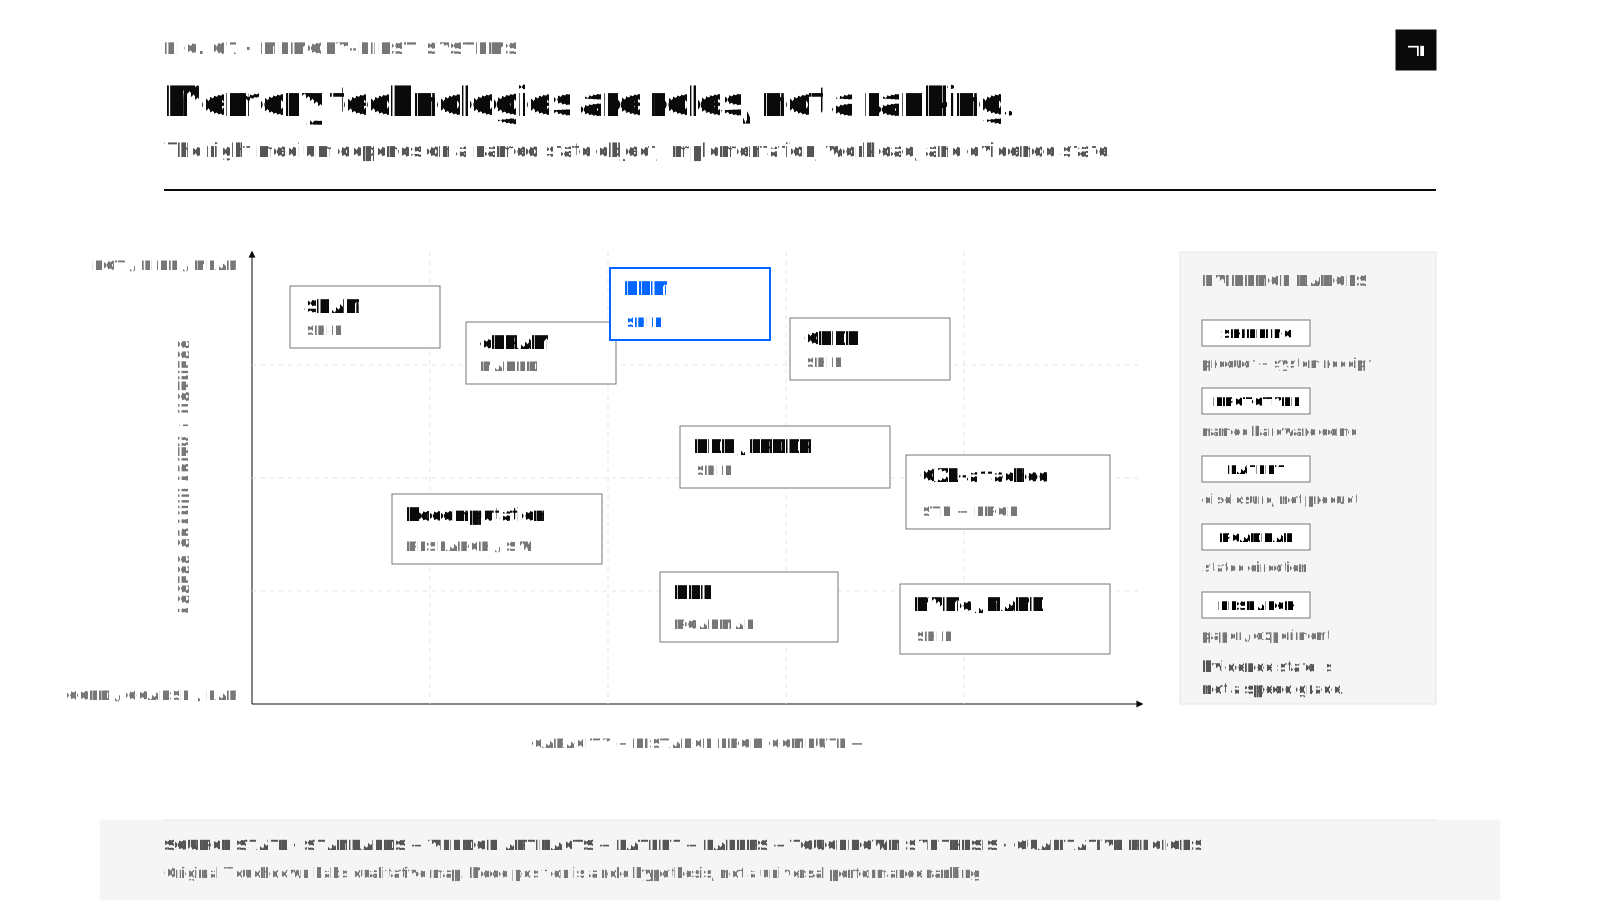
What this means by role. The CEO chooses a user outcome, not a medium. The CFO compares complete system and migration cost. The CTO uses HBM as the tuned baseline and tests lower or custom tiers one state role at a time. The hardware engineer rejects performance claims without package, controller, and evidence state. The software engineer must make placement and fallback explicit.
When should state move through HBM, host memory, CXL, or NVMe?
In plain English. Moving data is never free. Offload wins only when the HBM capacity it releases is more valuable than the transfer time, energy, extra software, failure risk, and tail-latency penalty it introduces. The object must also return before the next operation needs it.
A larger lower tier helps only when the system can predict, move, reuse, and retire state within the deadline. Capacity without a movement schedule is not useful capacity.
The minimum transfer model
For an object of bytes, the physical lower bound is not just size divided by a headline link rate:
transfer_time_lower_bound =
first_byte_latency
+ bytes / sustained_link_bandwidth
That still omits queueing, page faults, DMA setup, source/destination allocation, topology, contention, coherency, decompression, synchronization, and tail behavior. A useful receipt reports first byte and full completion at p50, p95, and p99 for the relevant direction and object size.
The placement decision compares complete paths:
placement_benefit =
avoided_recompute_time
+ avoided_hot_tier_occupancy
+ queueing_relief
- transfer_time
- movement_energy
- miss_and_retry_cost
- correctness_and_reliability_risk
[PROPOSED MODEL] Some terms are measured in milliseconds or bytes, others need a cost or constraint model. The equation is a decision checklist, not dimensionally valid addition until every term is normalized to a common objective.
Keep, prefetch, stream, spill, compress, or recompute
Keep state in HBM when reuse is near, mutation is active, or restore cannot meet the deadline. Active KV and a video latent are default examples, subject to a real trace.
Prefetch when access order is predictable enough to start movement before demand. The prefetch needs a confidence estimate, completion deadline, capacity reservation, cancellation path, and miss fallback.
Stream when large read-only regions are consumed in order. Double buffering can let compute consume one window while the next arrives. The schedule fails if lookahead shrinks, page usefulness falls, or tail latency exceeds the compute window.
Spill and restore when an inactive object is costly to recompute and likely to return. This can free HBM but adds write and read traffic.
Compress when fewer bytes justify encode/decode work and any precision loss. Rematerialize when recompute is cheaper than storage plus restore. Replicate when fan-out or locality beats capacity cost. Evict when expected reuse value falls below occupancy cost.
The fallback must remain correct:
# [PROPOSED] Illustrative policy, not a production scheduler.
if obj.mutable and obj.next_use_ms < restore_p99_ms:
keep("gpu_hbm")
elif obj.read_mostly and schedule_confidence >= required_confidence:
prefetch(target="gpu_hbm", source=best_measured_lower_tier)
elif obj.recompute_ms < restore_p99_ms:
rematerialize()
else:
run_correct_fallback_and_record_miss()
A real scheduler also accounts for capacity pressure, concurrent transfers, topology, bandwidth sharing, energy, fan-out, reliability, versioning, and quality.
CXL placement is still software policy
CXL can make additional memory coherently addressable or shareable under supported system designs. That reduces some software friction. It does not remove physical distance.
For a stable agent prefix, CXL-attached capacity might avoid recomputing prefill if the prefix is reused and restore meets time-to-first-token. For a mutable Wan2.2 latent used every step, the same tier may be a poor default because the object is read and written too frequently. For cold model weights, it may help model load or staging but still fail steady-state layer deadlines.
The evaluation must record the exact CPU, root complex, switch, CXL device, NUMA placement, firmware, kernel, allocator, link state, concurrency, and error behavior. CXL enabled is not an experiment description.
Page-streaming needs useful pages
For flash-class storage, define page usefulness:
useful_fraction =
bytes_consumed_before_eviction / bytes_fetched
effective_useful_bandwidth =
physical_read_bandwidth * useful_fraction
[TOUCHDOWN DERIVATION] This ignores queue and compute overlap but exposes overfetch. If software reads 1 MiB and consumes 64 KiB before discarding the page, the physical interface can be busy while useful bandwidth is only a fraction of the headline result.
Page streaming becomes plausible when access is predictable, pages are mostly consumed, queue depth is sufficient, first-byte and tail latency fit the lookahead window, double buffers fit in the hot tier, and writes are rare. It fails for frequent fine-grained mutation, unpredictable branches, sparse low-use pages, or a missing correct fallback.
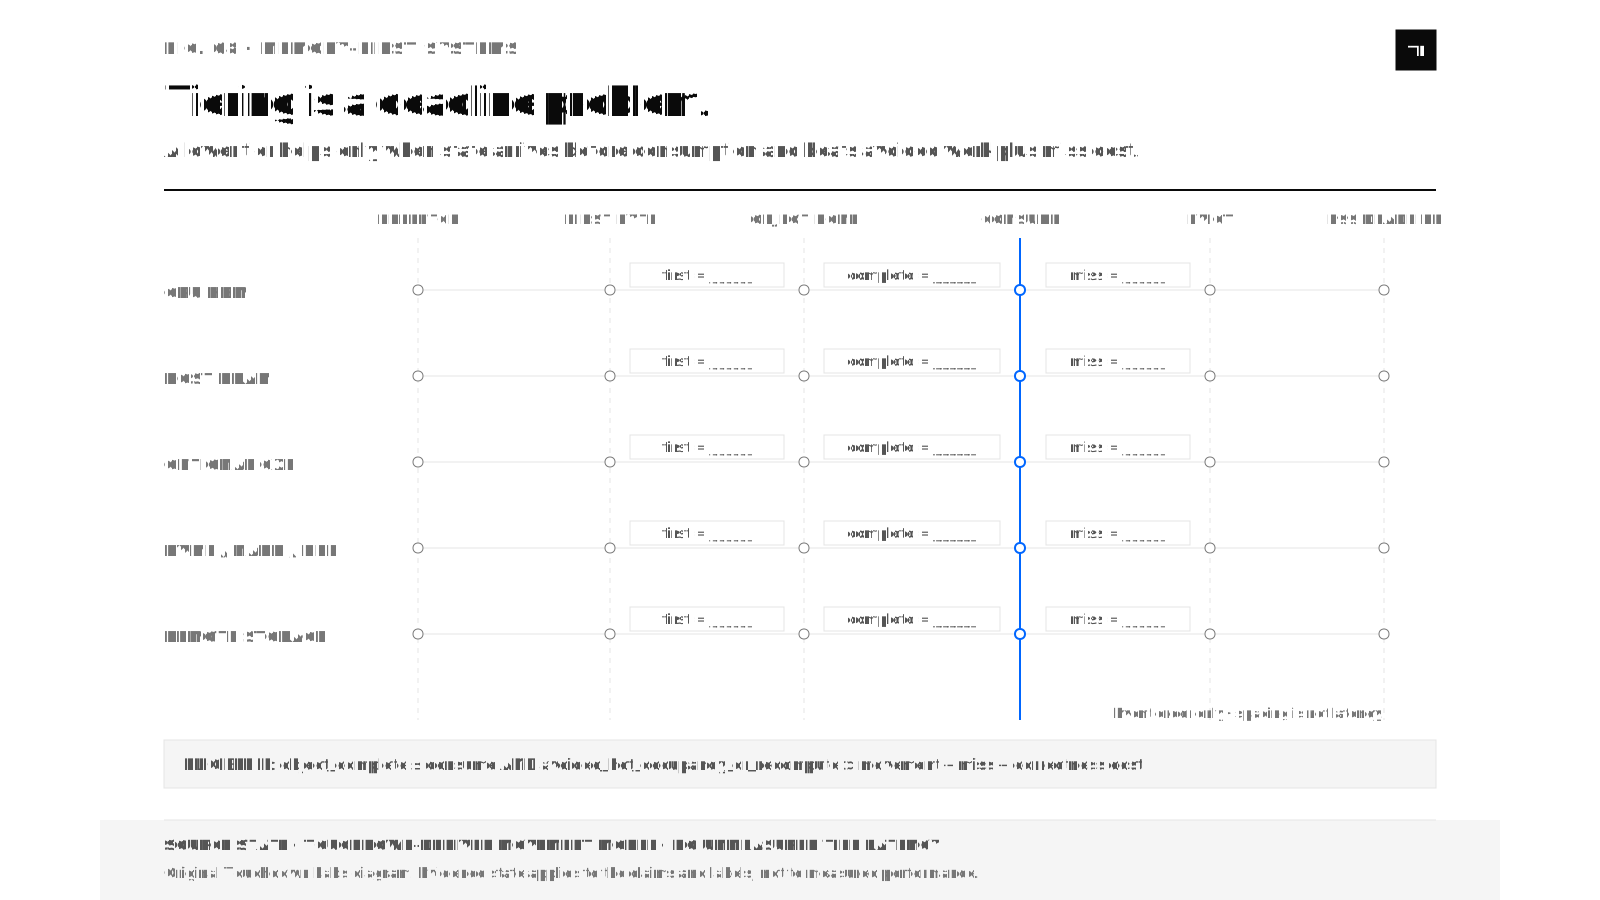
What do energy, heat, materials, yield, and supply do to the economics?
In plain English. Every useful byte begins in a manufactured device, consumes electrical work when it moves, adds heat that must leave the package, and occupies infrastructure that someone pays for. This section keeps five ledgers separate: electricity entering the system, IT work performed, heat transported, cooling work and water, and money allocated to an accepted task.
HBM is often described with an interface number and a stack capacity. A data center has to buy, power, cool, test, replace, schedule, and keep the whole system useful.
That means following three connected paths:
materials and qualified processes
-> dies, stack, package, board, server, rack
electrical events
-> heat, cooling, throttling, facility energy
usable capacity and throughput
-> accepted tasks, failures, margin, trust
Material science by function, not by buzzword
The exact bill of materials is vendor, generation, node, and package specific. The safe way to teach it is by function.
Silicon and device structures. The DRAM array begins on a semiconductor wafer with devices, isolation, contacts, and memory capacitors formed through repeated deposition, lithography, etch, implantation or doping, cleaning, annealing, and planarization steps. The logic base die has its own transistor and interconnect process. A high-performance logic process and a dense DRAM process optimize different things, which is one reason separate dies are useful.
DRAM capacitor. A capacitor needs two conductive electrodes separated by a dielectric. As cell footprint shrinks, the structure must preserve enough effective capacitance and low enough leakage to maintain a sensing margin. High-permittivity dielectric materials, three-dimensional capacitor geometry, electrode interfaces, defects, contamination, and process uniformity matter. It would be inaccurate to assign one dielectric or electrode stack to every HBM vendor without a named process source.
Transistor and contacts. The access device must switch the cell onto the bitline while limiting leakage when off. Threshold variation, mobility, junction leakage, contact resistance, temperature, disturbance, and aging influence retention and timing. Intel's XBM application makes backend-transistor integration part of its described search space, but it does not publish measured arrays that resolve those questions.
On-die interconnect. Local and global wires use conductors, barrier or liner structures, and insulating dielectrics. As dimensions narrow, resistance and reliability become harder. Capacitance between wires affects delay and energy. Copper remains important in semiconductor and package wiring, while tungsten, cobalt, ruthenium, and other materials appear in specific process roles and research. An Imec 16 nm-pitch ruthenium test structure is evidence about that structure, not proof of an HBM vendor's complete wiring stack. [RESEARCH TEST STRUCTURE]
TSV. A TSV needs an etched opening, an insulating liner where required, barrier/seed and conductive fill choices, contacts, and a wafer-thinning or reveal process. Copper is a common functional example, but the article does not treat one material sequence as universal. Mechanical stress from the via and thermal expansion can affect neighboring devices and keep-out zones.
Die bond. Microbumps can use solder and under-bump metallization to connect die pads. Direct or hybrid bonding can connect fine-pitch metal/dielectric surfaces under another process flow. Bond pitch, surface planarity, contamination, voids, alignment, thermal cycling, and current density affect yield and reliability.
Interposer, redistribution, and substrate. A silicon interposer can provide very dense wiring. Redistribution layers and bridges offer other routes. The organic substrate uses dielectric layers, copper traces, vias, solder connections, and reinforcement to connect the dense package to the board. Glass substrates are an industry development direction, not a universal shipping HBM assumption.
Thermal materials. Thermal interface material, heat spreaders, cold plates, solders or attach layers, and coolant or airflow form the heat-removal path. Thermal conductivity is not the only variable. Interface quality, thickness, pressure, pump/fan power, corrosion, reliability, serviceability, and the location of heat sources matter.
This functional view explains why raw materials is only the first supply layer. A data center cannot buy copper, silicon, and dielectric powder and obtain HBM. It needs ultra-pure materials, qualified recipes, process tools, masks, wafers, design IP, inspection, metrology, TSV and bonding capacity, substrates, assembly, test, firmware, controller validation, cooling, and field support.
From wafer to a qualified HBM package
A simplified dependency chain is:
memory and logic design
-> masks and qualified wafer processes
-> DRAM core dies and base logic dies
-> wafer probe and known-good-die screening
-> TSV, thinning, reveal, singulation, and preparation as applicable
-> die stacking and bonding
-> stack test, redundancy, and repair
-> accelerator plus memory package assembly
-> package test and reliability qualification
-> board, firmware, system, and cooling validation
-> production deployment and field RAS
SK hynix's public wafer-level package process overview is one source for the functional core/base-die, known-good-die, bump, stacking, and package sequence. It is not a universal vendor recipe. [OFFICIAL VENDOR EDUCATION]
Memory vendors, logic foundries, OSATs, substrate suppliers, equipment makers, materials companies, accelerator designers, board manufacturers, server companies, and cloud operators can each own different boundaries. Vertical integration changes the contractual map but does not eliminate the tasks.
Supply risk can enter at every point:
- Good DRAM wafers exist, but advanced packaging capacity is constrained.
- Stacks are available, but a logic die or accelerator limits packages.
- Packages exist, but substrates, boards, power delivery, or liquid cooling limit servers.
- Servers exist, but the software cannot use HBM efficiently.
- Capacity is installed, but reliability or acceptance failures reduce useful output.
That is why an HBM forecast cannot be translated directly into AI revenue without the middle path.
Touchdown's Computex 2026 physical-layer field guide shows the same hot, warm, and cold state problem at rack, power, cooling, and service boundaries. Here, the path is narrowed to HBM and its alternatives.
Where the electricity goes
At the cell and array level, energy appears in activation, sensing, restoration, precharge, read/write movement, and refresh. At the die and stack level, energy appears in internal buses, TSVs, clocks, I/O, ECC, BIST, and control. At the package and system level, it appears in PHYs, links, voltage conversion, board loss, accelerator compute, fans, pumps, and facility overhead.
A useful event model is:
memory_dynamic_energy_proxy =
sum(event_count_i * energy_per_event_i)
[MODELED] This is only as good as its counters and per-event model. A simulator may estimate activate, read, write, and refresh events. A real device may expose aggregate counters but not every internal action. Vendor per-bit numbers may use different traffic patterns and boundaries.
The direct measurement path is:
chip_energy = integral(chip_power_over_time)
That requires a power source with known sampling, calibration, and attribution. Board power includes more than memory. Device telemetry can be filtered or estimated. A rack power distribution unit includes host, networking, fans, and power conversion. The article must say which one it uses.
Facility overhead is often approximated with power usage effectiveness, using The Green Grid's public definition for the facility-to-IT boundary:
facility_energy_proxy = IT_energy * PUE
PUE is total facility energy divided by IT equipment energy over a defined boundary and time. It does not identify HBM's share of chip power. It changes with facility, load, weather, cooling mode, and accounting. This formula is useful only when the PUE source and interval match the workload estimate.
Water needs three separate ledgers. Technology-loop inventory tracks coolant fill, circulation, makeup, drain, leak, and recovery without calling circulation consumption. Site water uses the exact numerator reported by the source, such as withdrawal, discharge, consumption, or another explicitly defined usage metric at the data-center boundary. Source-energy water tracks off-site water associated with producing the electricity used by the facility. Combining them without names, intervals, and meter boundaries can double count or hide the larger term.
The Green Grid's WUE convention uses site water consumption divided by IT equipment energy over the reporting period. A different source may publish withdrawal or another water numerator, so the receipt must preserve the source's exact definition instead of relabeling it:
WUE_L_per_kWh = annual_site_water_L / annual_IT_energy_kWh
site_water_L_for_workload =
workload_IT_energy_kWh * matched_WUE_L_per_kWh
A workload accounting chain can be written as:
IT_energy_kWh =
measured_average_IT_kW * occupied_seconds / 3600
facility_energy_kWh =
IT_energy_kWh * matched_PUE
site_water_L =
IT_energy_kWh * matched_WUE_L_per_kWh
source_water_L =
facility_energy_kWh * matched_grid_water_intensity_L_per_kWh
Do not multiply a whole-facility energy reading by PUE again. Do not use a yearly average WUE as if it were an instantaneous meter. Do not infer water from liquid cooled: a closed equipment loop can reject heat through dry coolers, cooling towers, chillers, or a hybrid system, each with different water and power behavior. The Lawrence Berkeley National Laboratory review of data-center workload water use finds that workload water estimates can vary by more than four orders of magnitude across location, cooling, electricity, and efficiency assumptions. [RESEARCH SYNTHESIS] That is a warning to expose inputs, not permission to choose a convenient average.
This no-default calculator forces the boundary to stay visible:
from dataclasses import dataclass
@dataclass(frozen=True)
class FacilityReceipt:
measured_it_kw: float
occupied_seconds: float
pue: float
wue_l_per_it_kwh: float
grid_water_l_per_facility_kwh: float
electricity_usd_per_kwh: float
def facility_cost_and_water(r: FacilityReceipt) -> dict[str, float]:
it_kwh = r.measured_it_kw * r.occupied_seconds / 3600.0
facility_kwh = it_kwh * r.pue
return {
"it_kwh": it_kwh,
"facility_kwh": facility_kwh,
"site_water_l": it_kwh * r.wue_l_per_it_kwh,
"source_water_l": facility_kwh * r.grid_water_l_per_facility_kwh,
"electricity_usd": facility_kwh * r.electricity_usd_per_kwh,
}
The inputs must come from the named facility, utility, interval, meter boundary, and allocation method. A CFO also needs demand charges, capacity reservation, networking, storage, software, support, labor, financing, depreciation, rejected work, and stranded time. A CEO needs useful tasks delivered under the product SLO. A CTO needs the architecture and failure envelope. The same HBM platform can look efficient at the chip boundary and expensive at the accepted-task boundary.
Power, cooling, and money belong to one accepted-task receipt
The bad baseline is simple: read a GPU power number, multiply it by time, add a generic PUE, and call the result the cost of AI. That shortcut hides the parts that actually decide whether the infrastructure made money: how much verified work crossed the acceptance gate, how many retries were paid for, how much power capacity sat stranded, which state was recomputed, which links and storage tiers moved bytes, and what the facility spent carrying the resulting heat away.
A 600 W card, a 14.5 kW server, an eight-module accelerator baseboard, and a 120 kW rack cooling design are not four points on one comparable chart. They are different physical boundaries. A coolant flow rate is not a water-consumption rate. A rack design envelope is not a task-energy measurement. A faster token stream is not a cheaper coding task if the patch fails tests.
The decision boundary is:
minimum facility joules and dollars per verified successful task
subject to:
- output-quality parity
- TTFT, ITL/TPOT, and task-latency SLOs
- useful concurrency and throughput
- GPU, HBM, CPU, NIC, switch, and optic temperature limits
- power, flow, pressure, dew-point, and redundancy limits
- cache correctness and tenant isolation
- declared site-water constraints
- reliability and rollback requirements
The same run_id, operation_id, facility_interval_id, and accepted_output_id must join the application trace to GPU telemetry, rack power, cooling state, water accounting, and the final test or review result. Power, cooling, and water run beside the workload timeline. They are synchronized accounting boundaries, not fictional stages that begin only after the model finishes.
Interactive visual. The continuous machine on the left follows this same accepted-task boundary:
request -> runtime and state -> GPU, HBM, and fabric -> measured electrical power -> integrated energy -> heat transport -> cooling mode -> site and source-water ledgers -> allocated total cost -> verified success. Each subsection activates the corresponding physical boundary and evidence state without replacing the full article on the right. Power is a rate; energy accumulates over time; transported heat, cooling electricity, closed-loop circulation, site-water consumption, and cost remain separate ledgers until the accepted-output receipt joins them.
The three-layer decision
| Layer | Question | What must appear in the receipt |
|---|---|---|
| CEO / CFO | Did this system produce more accepted work from the same constrained power, capital, and engineering budget? | Verified successes, failures, retries, occupied time, capacity released, energy and total cost per success |
| CTO / serving engineer | Which software decision changed the physical work? | Prompt identity, cache hit or miss, prefill/decode phase, routing, batching, precision, placement, transfer path, fallback, p95/p99 |
| Kernel / hardware / facility engineer | Where did electricity go, where did heat move, and what limited sustained operation? | Kernel and collective trace, HBM and fabric traffic, power counters, temperatures, throttle state, coolant flow and pressure, CDU/fan/chiller state, meter coverage and uncertainty |
The executive decision is not “air or liquid?” It is “which complete architecture produces the required accepted work inside our power, cooling, latency, reliability, and cash constraints?”
Power is a rate. Energy is accumulated work.
Power describes the current operating rate:
power_W = joules_per_second
For a simple 60-second teaching example, a complete server averaging 10,000 W for the aligned interval would use:
10,000 W * 60 s = 600,000 J
600,000 J / 3,600,000 = 0.1667 kWh
That energy ultimately becomes heat inside the declared system boundary. Pumps, fans, a coolant distribution unit, chillers, or heat-rejection equipment can consume additional electricity outside the server meter. The example still says nothing about cost per useful result until the same interval records retries, shared utilization, prices, and how many outputs the verifier accepted.
Energy is power integrated over the same declared interval:
energy_J = integral(power_W(t), time)
energy_kWh = energy_J / 3,600,000
For sampled power, use the trapezoidal rule:
energy_J =
sum(((power_i_W + power_i+1_W) / 2)
* (timestamp_i+1_s - timestamp_i_s))
Prefer a cumulative hardware energy counter when its unit, timestamp, resolution, reset behavior, and wrap behavior are known. A task-level result is invalid when the counter resets, clock synchronization is unresolved, the sampling gap is material, or the facility interval does not contain the declared pre-task, task, post-task, and thermal-lag windows.
A published maximum is useful for electrical and cooling design. It is not a workload receipt:
vendor-rated maximum power * task duration
!= measured task energy
The equality holds only when the complete named boundary actually operated at that power for the full interval and the allocation method proves that the task owned it.
Lock the physical scope before comparing platforms
| Public platform boundary | Source-backed power or cooling fact | Correct use | What it does not prove |
|---|---|---|---|
| NVIDIA DGX B300 complete server | NVIDIA specifies 14.5 kW power consumption, 49,476 BTU/h maximum heat output, 1,500 CFM for the PSU configuration or 1,350 CFM for the busbar configuration at 70% PWM, and 10–30°C inlet air | Size power, airflow, containment, and facility capacity for the complete 10RU server | Energy for one coding task, fan energy for a workload, rack PUE, or accepted-task cost |
| NVIDIA GB200 NVL72 rack design | NVIDIA's OCP contribution specifies direct liquid cooling sized for 120 kW of rack cooling capacity; the DGX guide says CPUs and GPUs use cold plates while networking and storage remain air cooled | Explain a high-density hybrid or design-specific liquid path and the facility capacity it requires | That the rack continuously consumes 120 kW, that all heat enters liquid, or that 120 kW can be multiplied by one request's duration |
| AMD MI350P PCIe card boundary | AMD specifies passive air cooling, 450 W configurable and 600 W maximum TBP, a 12V-2x6 connector, and partner air-cooled systems with up to eight cards | Size the qualified slot, card power, PSU, cabling, server airflow, and board-only 3.6 to 4.8 kW eight-card envelope | Complete server or facility power, fan energy, inlet limit, workload energy, or universal eight-card compatibility |
| AMD MI355X UBB 2.0 accelerator-module boundary | AMD specifies PG-25, 43°C maximum inlet, 2.1 L/min recommended flow per OAM, and 1,400 W maximum TBP per module | Derive an eight-OAM module-only ceiling of 11.2 kW and a recommended circulation sum of 16.8 L/min | Complete server/rack power, pressure drop, pump power, CDU power, or 16.8 L/min of water consumption |
| NVIDIA Vera Rubin NVL72 rack direction | NVIDIA describes 100% liquid cooling with no system fans, up to 45°C rack inlet and roughly 55°C return in its reference narrative; the current MGX description says the actual rack fluid depends on the data center and may use deionized water or PG25 | Explain warm-water, fanless rack design and why dry cooling can become practical in suitable climates | Configuration-grade rack power, universal coolant chemistry, universal zero-water operation, or task-level savings |
| AMD Helios reference design | AMD describes a 72-MI455X double-wide Open Rack Wide design with a vertical power busbar and liquid-cooling manifold feeding compute and switch trays through quick disconnects | Show the AMD rack-scale liquid and power architecture direction | Final orderable SKU, rack power, flow, pressure drop, coolant chemistry, CDU power, or accepted-workload result |
| RTX PRO 6000 Blackwell | NVIDIA specifies 300 W maximum for Max-Q with active cooling; the server edition is configurable up to 600 W and is available in dual-slot air or single-slot liquid form factors | Separate workstation/card experimentation from complete server and rack infrastructure | Complete node power, OEM airflow or liquid conditions, facility energy, or cost per accepted task |
Sources: NVIDIA DGX B300 User Guide, NVIDIA DGX GB rack guide, NVIDIA GB200 NVL72 OCP design, AMD MI350P product page, AMD MI350P enterprise deployment article, AMD MI355X platform brief, NVIDIA 45°C liquid-cooling architecture, NVIDIA Vera Rubin POD and MGX architecture, AMD Helios, RTX PRO 6000 Max-Q, and RTX PRO 6000 Server Edition.
Follow the electrical path from grid to silicon
utility meter
-> transformer and switchgear
-> UPS or rack energy storage
-> facility distribution
-> rack PDU or power shelf
-> rectifier and DC busbar
-> board voltage regulators
-> GPU, HBM, CPU, DRAM, NIC, DPU, switch, retimer, storage, and fans
Each conversion can lose energy:
conversion_loss_J =
input_energy_J
- output_energy_J
- stored_energy_change_J
conversion_efficiency =
output_energy_J / input_energy_J
If only a vendor efficiency curve exists, mark the result modelled and preserve the exact equipment revision, input voltage, load fraction, temperature, and source. If the operating point is missing, leave the value unknown.
Do not add component telemetry to a parent meter that already contains it. A rack PDU total already includes the node's GPUs, CPUs, memory, NICs, storage, local fans, and conversion losses downstream of that meter. Those component readings explain composition; they are not extra energy.
reconciliation_residual_J =
measured_parent_J
- sum(mutually_exclusive_measured_children_J)
sum(task_allocations_J) + unallocated_J
= measured_parent_J +/- uncertainty
The residual remains visible. It is where missing meters, clock error, sensor accuracy, storage changes, and unobserved components show up.
Follow the runtime mechanism into the power trace
The same accelerator can draw similar average power while producing very different useful work.
C-001 coding-agent task
-> stable system, policy, tool, RAG, and repository prefix
-> cache identity validation
-> prefix hit, partial hit, restore, or miss
-> prefill for non-reused tokens
-> decode and MoE or dense model operations
-> KV append and possible collective traffic
-> tool call on CPU, filesystem, network, or sandbox
-> tool-result suffix prefill
-> more decode
-> patch, tests, review, and acceptance
A cache miss can repeat expensive prefill. A cache hit can avoid it. A route to a cooler GPU can destroy prefix locality and create more HBM and fabric traffic than it saves thermally. A lower core frequency can save GPU-device energy during memory-bound decode, but it can also extend runtime while HBM, NICs, CPUs, pumps, and static platform power continue to accumulate.
That is why the control objective is not minimum instantaneous watts:
choose:
frequency
power cap
route
batch
cache location
state placement
transfer path
cooling setpoint where exposed
to minimize:
facility_joules_per_verified_success
and total_cost_per_verified_success
while preserving:
quality
TTFT / ITL / p99
useful capacity
reliability
thermal and water limits
VoltanaLLM is useful research evidence for this mechanism. Its authors report up to 36.3% GPU energy savings relative to a static maximum-frequency baseline in their evaluated SGLang configurations while maintaining high SLO attainment. That is an author-reported GPU-device result for the paper's named setup. It is not a Touchdown reproduction, accepted-task result, complete-node result, rack result, facility result, or water result. The next step is not to copy its A100 clock table. It is to replay the control idea on each exact model, engine, kernel, topology, and power boundary. Source: VoltanaLLM.
Electricity becomes heat, but heat transport is not electrical energy
Within a declared control volume over a steady-state interval, nearly all IT electrical energy that is not exported as electrical or optical work or retained in stored state eventually appears as heat. During transients, stored thermal energy must remain an explicit term. The heat can leave through air, liquid, or both.
GPU logic + HBM + CPU + DRAM + NIC + switch + VRM + storage
-> die and package
-> thermal interface
-> heat sink or cold plate
-> chassis air or technology cooling loop
-> CDU or room cooling equipment
-> facility loop
-> dry cooler, chiller, cooling tower, or verified heat-reuse sink
For air cooling:
heat_transport_air_W =
air_density_kg_m3
* air_specific_heat_J_kgK
* airflow_m3_s
* (exhaust_C - inlet_C)
fan_wire_power_W =
pressure_rise_Pa * airflow_m3_s / fan_efficiency
For a single-phase liquid:
mass_flow_kg_s =
coolant_density_kg_m3 * volumetric_flow_m3_s
heat_transport_liquid_W =
mass_flow_kg_s
* coolant_specific_heat_J_kgK
* (return_C - supply_C)
pump_hydraulic_power_W =
differential_pressure_Pa * volumetric_flow_m3_s
pump_wire_power_W =
pump_hydraulic_power_W / wire_to_water_efficiency
For a phase-changing coolant:
heat_transport_W =
mass_flow_kg_s
* (enthalpy_out_J_kg - enthalpy_in_J_kg)
Do not use a constant specific_heat * delta_T approximation across boiling or condensation. Do not model PG-25 with pure-water properties. Record the property source and temperature.
The aligned heat balance is:
IT electrical power
+ pump and fan heat entering the observed control volume
=
liquid heat transport
+ air heat transport
+ exported useful heat
+ ambient loss
+ stored thermal energy increase
+ exported electrical or optical power
+ reconciliation residual
Heat carried by liquid is not GPU electrical energy. It is not cooling electrical energy. It is not automatically heat reused. These are different ledgers.
Cooling is a runtime state, not a product label
“Liquid cooled” is not a complete description. The facility can operate in different modes over one long video job or agent loop:
| Operating mode | Heat-rejection path | Main electrical loads | Direct site-water path |
|---|---|---|---|
| Dry or free cooling | Facility loop to dry cooler to ambient air | Pumps, dry-cooler fans, controls | No routine evaporation; service loss and optional adiabatic assistance remain separate |
| Adiabatic assist | Dry cooler plus spray or wetted media | Pumps and fans | Weather-dependent spray consumption |
| Mechanical chiller | Facility loop through evaporator, compressor, and condenser | Pumps, compressor, condenser fans or tower | Depends on air-cooled versus water-cooled condenser |
| Cooling tower | Condenser loop to evaporative tower | Pumps, tower fans, possible chiller | Makeup, evaporation, drift, blowdown, and leaks |
| Useful heat export | Warm facility loop crosses a meter into a verified sink | Pumps and possibly a heat pump | Water effect remains separately measured |
ASHRAE recommends matching cooling topology to AI rack densities around 60–120 kW/rack and above, using scalable manifolded liquid distribution, tracking PUE and water metrics, and considering warm-water heat recovery where a real sink exists. OCP guidance separates the technology cooling loop from the facility loop and emphasizes thermal ride-through, pump redundancy, and dry heat rejection where feasible. DOE's typical tower path carries heat from IT through room or liquid systems, chillers, condenser water, and finally evaporative rejection. Sources: ASHRAE AI Data Center Framework, OCP Advanced Cooling Facility reference design, and DOE cooling-water guidance.
Record every mode transition:
mode_start and mode_end
ambient dry-bulb and wet-bulb temperature
humidity and dew point
coolant supply and return temperature
flow and differential pressure
pump, fan, CDU, chiller, tower, and adiabatic state
thermal storage change and lag
redundancy, leak, throttle, and fault state
Warm-water liquid cooling can free facility power for compute, but the result depends on climate, final heat rejection, pump and fan work, redundancy, and the accepted workload. NVIDIA's Rubin reference narrative describes 45°C supply, roughly 55°C return, a closed loop, and the potential to use dry coolers in suitable climates. Treat its zero-water and dollar-savings examples as vendor scenarios tied to geography and design, not universal task measurements.
Water needs three ledgers
1. Technology-loop inventory and service loss
initial fill + makeup - drain - leak - recovered coolant
2. On-site withdrawal and consumption
potable + reclaimed + groundwater + surface water
- returned or discharged water
- positive storage change
3. Source-energy water
off-site water associated with generating the electricity used
The critical distinction:
closed_loop_circulation_L =
integral(flow_rate_L_s, time_s)
closed_loop_circulation_L
!=
site_water_consumption_L
For the AMD example:
8 OAMs * 2.1 L/min per OAM
= 16.8 L/min recommended circulation sum
not:
16.8 L/min of water consumed
For a cooling tower:
tower_makeup_L =
evaporation_L
+ drift_L
+ blowdown_L
+ leaks_L
+ inventory_change_L
- internal_recovery_L
For the site:
site_consumption_L =
potable_input_L
+ reclaimed_input_L
+ groundwater_input_L
+ surface_water_input_L
- returned_or_discharged_L
- positive_storage_delta_L
PUE and WUE remain facility metrics over aligned boundaries and intervals:
PUE_T =
total_facility_energy_T / IT_energy_T
WUE_T =
site_water_usage_L_T / IT_energy_kWh_T
site_water_usage_L_T preserves the numerator used by the named WUE source. The receipt must map that numerator explicitly to withdrawal, consumption, or another defined usage boundary; it cannot silently treat those terms as interchangeable.
Do not apply PUE when facility energy is already measured. Do not call the full PUE overhead cooling; it also includes electrical conversion, distribution, controls, lighting, and other non-IT loads. Do not present an annual WUE as an instantaneous task meter. A per-task result from PUE or WUE is an allocation model unless synchronized meters cover the same task and thermal-lag interval.
The full money path
Electricity matters. It is rarely the whole bill.
total_relevant_cost =
accelerator_and_memory_capital
+ host_CPU_and_DRAM_capital
+ networking_and_storage_capital
+ electrical_and_cooling_buildout
+ installation_and_financing
+ software_and_support
+ operations_and_maintenance
+ measured_energy_cost
+ allocated_peak_or_capacity_cost
+ spares_and_expected_failures
+ retries_and_rejected_work
+ human_rework
- residual_value
Use separate ledgers:
variable_energy_cost =
facility_energy_kWh * blended_energy_rate_USD_per_kWh
monthly_peak_cost =
billing_peak_kW * demand_or_capacity_rate_USD_per_kW
straight_line_annualized_capital_cost =
(purchase
+ electrical_buildout
+ cooling_buildout
+ network
+ storage
+ installation
+ financing
- residual_value)
/ useful_life_years
capital_recovery_factor =
discount_rate * (1 + discount_rate)^useful_life_years
/ ((1 + discount_rate)^useful_life_years - 1)
finance_grade_annualized_capital_cost =
net_present_capital_cost * capital_recovery_factor
allocated_capital_cost_per_success =
allocated_annualized_capital_cost
/ annual_verified_successes
The first expression is straight-line allocation, not finance-grade annualization. Use one accounting horizon and present-value convention across every cost term. Tariffs, financing, hardware prices, service contracts, discount rate, useful life, and residual value are site- and contract-specific. Keep every unsourced input visible as an assumption or range.
The business denominator is:
gross_cost_per_verified_success =
all_allocated_costs_for_all_attempts
/ verified_successes
Retries and rejected outputs stay in the numerator. Only verified successes enter the denominator. If verified_successes == 0, the result is null, not zero and not an impressive-looking infinity.
The capacity view is often more important than the energy line item:
verified_successes_per_constrained_kWh =
verified_successes / facility_energy_kWh
contribution_margin_per_constrained_kWh =
verified_successes_per_constrained_kWh
* contribution_margin_per_success
realizable_capacity_value_released =
min(additional_verified_successes, additional_demand)
* contribution_margin_per_success
A cache improvement, kernel optimization, or thermal-aware route is valuable when it releases enough constrained GPU, rack, or facility capacity to serve more accepted work without violating p99 or quality. Released technical capacity becomes realizable financial value only when demand and positive contribution margin exist. The real prize is not merely a lower electricity bill. It is more trustworthy product capacity from the same expensive power and hardware envelope.
One fully labeled money example
This is an illustrative sensitivity, not a Touchdown benchmark.
NVIDIA publishes a 14.5 kW power-consumption figure for one complete DGX B300. Suppose an operator uses that published system figure as a conservative one-hour planning envelope, assumes PUE = 1.10, and tests three explicitly assumed electricity rates.
IT energy proxy =
14.5 kW * 1 hour
= 14.5 kWh
facility energy proxy =
14.5 kWh * 1.10
= 15.95 kWh
| Assumed electricity rate | Energy-only cost for the hour | If 100 tasks are verified | If only 70 tasks are verified |
|---|---|---|---|
| $0.05/kWh | $0.7975 | $0.007975/success | $0.011393/success |
| $0.10/kWh | $1.5950 | $0.015950/success | $0.022786/success |
| $0.15/kWh | $2.3925 | $0.023925/success | $0.034179/success |
Every number after the 14.5 kW vendor specification is a Touchdown derivation from stated assumptions. This is energy-only. It excludes the server purchase, networking, storage, facility buildout, peak charges, support, labor, spares, failed attempts, and financing. It also assumes the system held that published figure for the full hour; a real task result must integrate measured power.
The table illustrates the denominator effect: identical facility energy looks 43% more expensive per verified success when 30 of 100 attempts fail the acceptance gate.
The controlled before/after experiment
Use four equal-duration energy controls:
E00 = loaded-service idle
E10 = compute-only control
E01 = transfer-only control
E11 = actual combined compute + transfer
Then preserve the interaction term:
delta_E_compute =
E10 - E00
delta_E_transfer =
E01 - E00
delta_E_combined =
E11 - E00
E_interaction =
E11 - E10 - E01 + E00
E_interaction captures overlap, synchronization, contention, DVFS, batching, queueing, fabric congestion, and thermal state. Do not report compute energy + transfer energy as the actual combined result without measuring or preserving that interaction.
Required experiment arms:
- Vendor default.
- Fixed-frequency sweep.
- Power-cap sweep.
- State-aware routing only.
- Phase-frequency control only.
- Joint frequency and state-aware routing.
- Joint frequency, routing, state placement, and fabric path.
- Joint compute control plus thermal-headroom control.
Freeze:
workload and arrival trace
repository / prompt / retrieval identity
model and artifact revision
engine, container, precision, and KV format
quality and acceptance rubric
concurrency and retry budget
topology and background load
coolant and ambient conditions
warmup, steady-state, and lag windows
Report:
attempts and verified successes
quality and test results
TTFT, ITL/TPOT, p50, p95, and p99
prefill, decode, tool, restore, and queue time
cache hit, miss, eviction, and bytes moved
GPU, node, rack, and facility joules by valid boundary
pump, fan, CDU, chiller, and tower energy
site and source-water liters
temperature, throttle, leak, and failure events
gross and incremental cost per verified success
useful capacity and successful tasks per kWh
A policy wins only when the accepted-task result improves without quality, latency, retry, capacity, thermal, or reliability regression.
The minimum facility receipt
FacilityBoundaryReceipt:
schema_version: touchdown.facility-boundary-receipt.v1
run_id: string
workload_id: C-001 | V-001
fixture_digest: string
accepted_output_ids: [string]
attempts: int
verified_successes: int
retries: int
failures: int
quality_parity: bool | null
slo_parity: bool | null
interval:
utc_start: string
utc_end: string
monotonic_start_ns: int
monotonic_end_ns: int
clock_domain: string
max_sync_error_ms: float
sample_period_ms: float
missing_sample_fraction: float
warmup_s: float
cooldown_s: float
thermal_lag_window_s: float
execution:
model_revision: string
engine_revision: string
precision: string
kv_format: string
topology_id: string
policy_decision_ids: [string]
fabric_event_ids: [string]
energy:
boundary_ids: [string]
parent_child_coverage: object
measurement_kind: measured | allocated | modelled | unknown
meter_ids: [string]
reconciliation_residual_J: float | null
thermal:
boundary_ids: [string]
coolant_and_property_source: string | null
supply_return_flow_pressure: object
air_side_remainder: float | null
throttle_and_fault_events: [object]
water:
boundary_ids: [string]
inventory_L: float | null
circulation_L: float | null
withdrawal_L: float | null
site_consumption_L: float | null
source_energy_water_L: float | null
finance:
electricity_rate_source: string | null
demand_rate_source: string | null
capital_allocation_method: string
allocated_energy_cost_USD: float | null
allocated_total_cost_USD: float | null
derived:
gross_J_per_verified_success: float | null
incremental_J_per_verified_success: float | null
successful_tasks_per_kWh: float | null
site_L_per_verified_success: float | null
total_cost_per_verified_success: float | null
uncertainty: object
Every populated field carries a source, timestamp, physical boundary, unit, measurement kind, and uncertainty. Unknown remains visible and never becomes zero.
Copy-paste: executive decision rule
Do not buy or reject a platform from TDP, peak bandwidth, or tokens per second.
Compare the same verified workload at the same quality and p99:
1. accepted tasks per hour;
2. gross and incremental facility joules per accepted task;
3. total cost per accepted task;
4. useful capacity released inside the constrained power envelope;
5. thermal, water, reliability, and rollback limits.
A vendor envelope sizes infrastructure. A synchronized accepted-task receipt makes the decision.
Copy-paste: measurement gate
A power or cooling claim is publishable only when it names:
- the exact platform and physical scope;
- included and excluded components;
- workload, model, engine, precision, concurrency, and topology;
- meter or sensor, sampling semantics, calibration, and clock sync;
- air/liquid loop, coolant, temperatures, flow, pressure, and rejection mode;
- attempts, retries, failures, and verified successes;
- formula, allocation method, uncertainty, and source revision.
Closed-loop flow is not water consumption.
Heat transport is not electrical energy.
GPU energy is not facility energy.
A faster output is not a cheaper task until it passes the acceptance gate.
What this means by role. The CEO sees whether infrastructure created more accepted product capacity. The CFO sees capital, energy, peak power, cooling, failures, and margin on one denominator. The CTO sees which routing, cache, precision, placement, and control decision changed the result. The software engineer can join the request and state path to the physical meters. The kernel and hardware engineers can separate logical bytes, measured traffic, electrical work, heat transport, and cooling overhead without double counting them.
Heat changes sustained behavior
With the facility accounting boundary now closed, return to the package and ask how HBM temperature changes the sustained service that the software actually receives.
Electrical energy becomes heat. The temperature rise depends on heat flux, material conductivities, interfaces, airflow or coolant, and thermal resistance.
HBM sits close to a high-power accelerator. The logic base die can add activity under the memory stack. Heat can increase leakage and reduce retention margin. Controllers or firmware can throttle clocks or traffic to stay inside safe limits. A peak bandwidth specification can remain true while sustained workload service falls under a thermal or power cap.
Cooling also consumes energy and infrastructure. A liquid-cooled rack needs pumps, distribution, heat exchangers, controls, leak management, water or coolant treatment, and maintenance. More efficient chip-level movement can still lose at the facility level if it requires a much harder cooling path or lowers packaging yield.
The correct receipt joins performance and thermal data on the same timeline:
timestamp
kernel / workload phase
HBM and link traffic
chip / board power source
memory and accelerator temperature
clock / throttle state
cooling operating point
accepted output
Kyber shows where the HBM package becomes a rack system
HBM ends at the accelerator package, but the workload does not. Once a model spans GPUs, memory placement couples to NVLink, NVSwitch, board routing, rack power, cooling, and the physical boundary of the scale-up domain.
NVIDIA now defines Kyber officially as its next-generation MGX NVL rack design. It is not a GPU generation, an HBM generation, or another name for every Rubin Ultra system. NVIDIA's current preliminary topology map is: NVIDIA Vera Rubin POD.
Vera Rubin Ultra Kyber NVL144:
one Kyber rack
144 GPUs in one NVLink scale-up domain
Vera Rubin Ultra NVL576:
eight separate 72-GPU MGX NVL racks
576 GPUs in one multirack domain
Feynman Kyber NVL1152:
eight 144-GPU Kyber racks
1,152 GPUs in one multirack domain
Those are different physical products. NVL576 is not one 576-GPU rack. NVL1152 is not one 1,152-GPU rack. Kyber first appears with Vera Rubin Ultra as a standalone NVL144 system, while eight Kyber racks later form the Feynman NVL1152 system. [OFFICIAL PRELIMINARY]
This matters to an HBM article because aggregate HBM capacity and bandwidth do not automatically become one useful memory pool. Tensor, expert, sequence, pipeline, and data parallelism decide which bytes remain local, which bytes cross NVLink, and which bytes cross a scale-out network. A rack can contain enormous HBM bandwidth while a workload waits on collectives, synchronization, host orchestration, storage, or a rejected output.
NVIDIA also connects Kyber to its 800 VDC power architecture. That establishes an official architecture direction around higher-voltage facility-to-rack distribution. It does not establish delivered Kyber power efficiency or accepted-workload economics.
Named independent reports from Tom's Hardware and Data Center Dynamics describe vertical-tray and orthogonal-PCB-midplane implementation details and report possible schedule risk tied to manufacturability. Both also report NVIDIA's response that its roadmap is intact. [THIRD-PARTY REPORT]
The reviewed NVIDIA primary sources do not publish the final Kyber PCB stackup, layer count, trace geometry, impedance distribution, board yield, failure Pareto, named supplier qualification, supplier allocation, customer schedule, or Wan2.2 result. Those fields remain [NOT PUBLIC]. Repeated secondary numbers do not become a production datasheet.
What must physically work in a Kyber-class system
The official architecture is enough to identify the engineering categories, even when private implementation values stay unknown.
Signal path. A serializer launches bits into package and board channels. Vias, connectors, copper traces, cable cartridges, and any direct-optical boundary add insertion loss, reflection, crosstalk, skew, and jitter. Equalization and clock recovery must recover the eye at the receiver across process, voltage, temperature, aging, and assembly variation. A clean schematic or simulated nominal channel is not qualification.
Power path. Facility power passes through switchgear, conversion, busbars, shelves, voltage regulators, package delivery, and on-die rails. Current transients create droop and noise. NVIDIA's current MGX description adds rack-level energy storage, dynamic power steering, and power smoothing. Its 800 VDC direction attempts to change the facility-to-rack conversion boundary. Those mechanisms must be evaluated with workload transients, protection, service safety, fault isolation, and conversion loss.
Thermal path. GPU logic, HBM stacks, NVSwitch silicon, optics or copper interfaces, voltage conversion, and DPUs produce heat at different locations. Heat crosses dies, underfill, package lids, cold plates, coolant, manifolds, CDUs, facility loops, and heat rejection equipment. Flow imbalance, fouling, bubbles, pump failure, leaks, and high inlet temperature can change sustained clocks or availability even when peak specifications remain unchanged.
Mechanical path. A dense rack must survive board fabrication, component placement, reflow, tray assembly, connector mating, shipping shock, installation, repeated service, and thermal cycling. Tighter channel and power constraints can reduce the manufacturing margin. The relevant yield is not only a bare PCB yield or a good GPU package. It is the probability that the assembled tray, fabric, cooling loop, power path, firmware, and rack pass qualification and remain serviceable.
Test and repair path. Manufacturing needs boundary scan, link training, BIST, lane margining, power and thermal test, leak checks, burn-in, fault injection, and traceable component identity. Operations need a way to isolate a bad GPU, switch, link, DPU, power shelf, sensor, or cooling component without turning an entire scale-up domain into unusable inventory. NVIDIA describes continued rack operation during NVLink switch maintenance for Vera Rubin. The exact Kyber degradation and repair behavior remains a future product question.
What software sees instead of one giant memory
The runtime sees ranks, devices, address spaces, allocations, communication groups, and failures. A placement compiler or scheduler must map each tensor or state object onto those boundaries:
weights and active KV
-> shard or replicate across GPU HBM
attention heads / sequence partitions / experts
-> assign to ranks in a topology-aware group
all-reduce / all-gather / reduce-scatter / all-to-all
-> choose collective algorithm and route over the scale-up fabric
checkpoint / reusable KV / dataset / tool state
-> place in host memory, CMX or storage only under an explicit policy
rank, switch, link, or rack failure
-> degrade, remap, retry, or reject under a named correctness rule
For Wan2.2 Ulysses sequence parallelism, the all-to-all exchange changes how attention state is distributed before and after attention. A 144-GPU domain creates more possible partitions, but it also enlarges the participant set and the consequences of imbalance or failure. For an MoE model, expert placement and token routing create a different all-to-all. For a coding agent, a small model or low-concurrency service may gain nothing from a giant domain and can pay more for idle capacity and operational complexity.
What the Kyber receipt must contain
named platform and evidence state
GPU packages per rack and racks per scale-up domain
HBM capacity and bandwidth at per-GPU and aggregate scopes
rank map and physical topology capture
collective message-size histogram and p50 / p95 / p99
link training, retry, error, and degraded-mode counters
board, tray, rack, and facility power with timestamps
temperature, coolant, flow, throttle, and leak events
planned and unplanned maintenance time
software, firmware, compiler, engine, and model revisions
accepted-task throughput, quality, latency, retry, and cost
Until those fields exist for a delivered Kyber system, the honest result is an architecture and diligence model, not a workload benchmark.
The decision rule remains workload-first:
HBM-local kernel time
+ exposed collective wait
+ synchronization and host time
+ VAE, storage, and review time
+ retries and rejected outputs
= occupied rack time per accepted result
The operator should compare cost_per_accepted_task or rack_seconds_per_accepted_clip, not only peak HBM or NVLink bandwidth.
Yield, repair, and failures reach the customer
Manufacturing yield determines how many good units emerge from a process. Test coverage determines how many bad units are caught before shipment. Repair determines which defects can be recovered. Field RAS determines how errors are detected and contained after deployment.
A lower package yield can raise effective cost and constrain supply. More redundancy can recover units but consumes area and may complicate routing. Aggressive repair can improve usable capacity while still leaving performance nonuniformity or untested failure modes. Strong ECC can correct a defined error pattern but cannot repair every controller, link, or package fault.
At runtime, an uncorrectable error can kill a request or a worker. A correctable-error storm can reduce performance. A link retry can add tail latency. A stale cache entry can return a logically wrong result even when every bit is physically correct. Reliability therefore crosses physics and software.
Turn it into business value without inventing prices
The complete system cost is broader than the accelerator invoice:
usable_system_cost =
accelerator_and_memory_package
+ host_CPU_and_memory
+ board_and_network
+ storage
+ power_delivery_and_cooling
+ expected_failures_and_spares
+ software_and_operations
The useful capacity side is:
accepted_output_capacity =
tasks_per_hour
* acceptance_rate
* availability
And the business boundary returns to:
cost_per_accepted_task =
total_relevant_cost / accepted_tasks
No public dollar appears without a dated source or labeled assumption. Instead, run sensitivity:
- If extra HBM raises batch or concurrency, how many additional accepted tasks fit before p99 breaks?
- If host or CXL offload frees HBM, how much restore latency and link contention enters?
- If streaming weights from flash avoids a larger package, how often does first-byte or page overfetch stall compute?
- If custom base logic removes traffic, how much non-recurring engineering, qualification, thermal, and yield risk is added?
- If a sparse kernel reduces attention work, does quality remain acceptable and do index/gather/collective costs stay below the savings?
A scenario tool should preserve evidence state in its inputs:
# [TOUCHDOWN DERIVATION] Structure only. No default prices or power.
inputs = {
"accepted_tasks": {"value": measured_tasks, "state": "measured"},
"gpu_seconds": {"value": measured_gpu_s, "state": "measured"},
"gpu_rate": {"value": contract_rate, "state": "assumption"},
"IT_energy_kWh": {"value": metered_energy, "state": "measured"},
"PUE": {"value": facility_PUE, "state": "measured_or_assumed"},
"transfer_p99_ms": {"value": restore_p99, "state": "measured"},
}
The output is a range with sensitivity, not a precise answer built on hidden defaults.
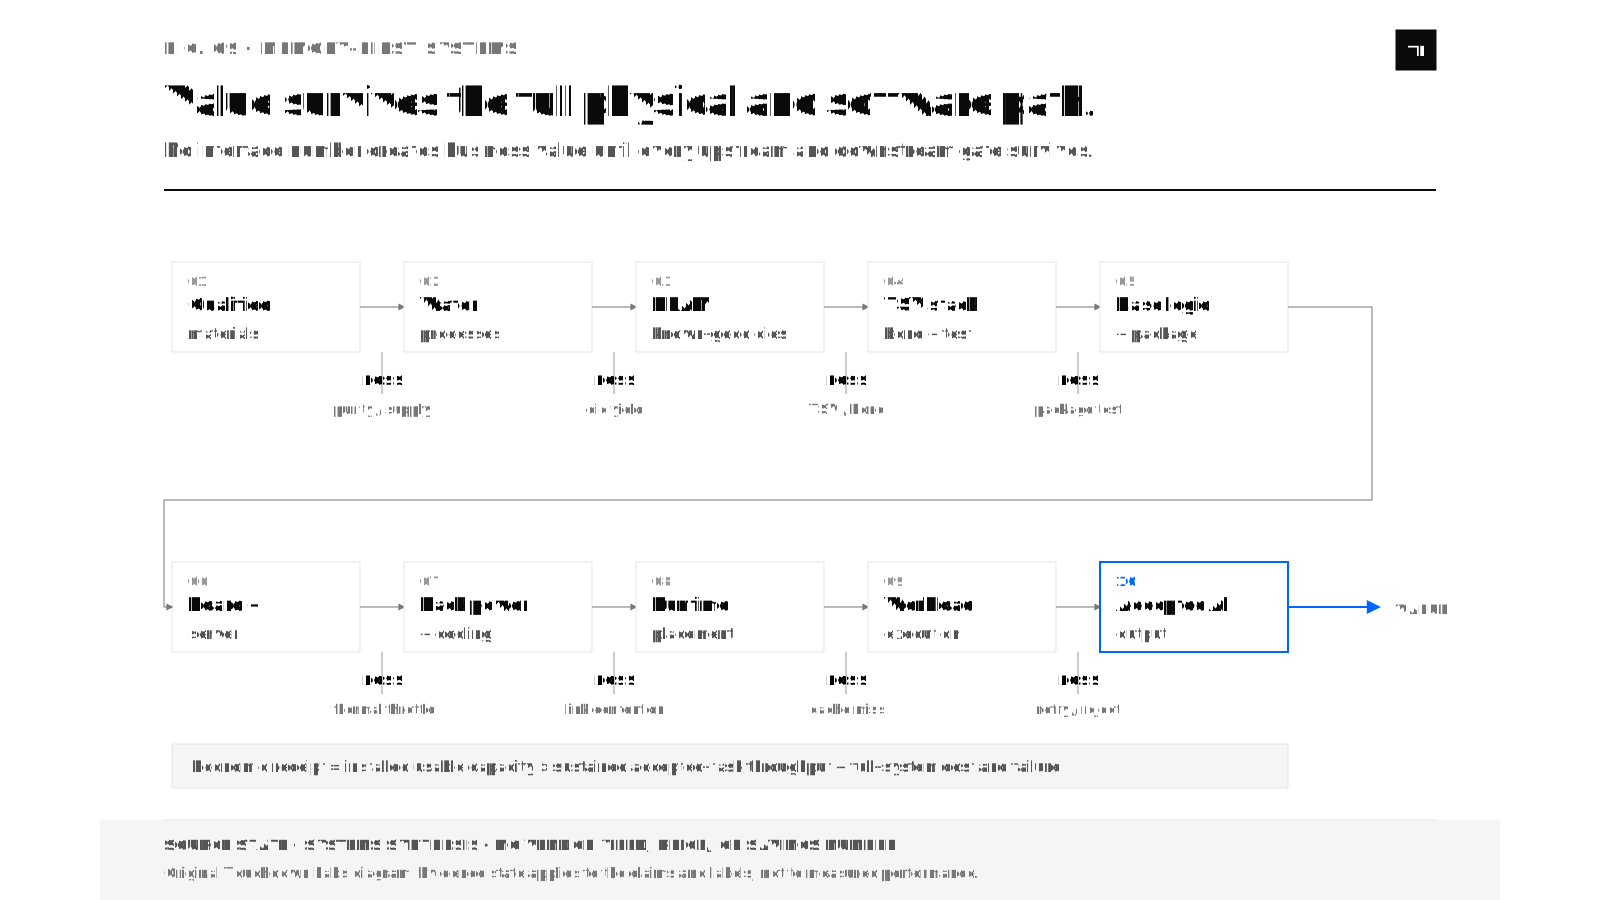
What this means by role. The investor identifies which supply constraint is durable and which is substitutable. The CEO ties installed capacity to accepted output. The CFO separates package capex, energy, failure, and engineering cost. The CTO requires a workload replay before committing to a new tier. The hardware team shows test, repair, PDN, and thermal evidence. The software team shows placement, retry, and acceptance receipts.
What do the hardware lottery and Carmack actually change?
In plain English. Hardware makes some algorithms easy and others awkward. Software then evolves around the machines that are available. The practical question is not whether hardware determines every idea. It is whether a repeated, predictable workload pattern is important enough to justify a different software primitive, controller, memory placement, or physical design.
The evidence so far points in two directions at once.
HBM is a phenomenal commercial answer for hot AI state. The software and hardware stack around dense tensor operations is deeply optimized. At the same time, the two workloads contain state and operations that do not all look like dense GEMM.
The right response is not to reject the current stack. It is to ask which ideas were selected because the stack makes them cheap, and which memory schedules become possible when access is predictable.
Sara Hooker: available systems shape successful ideas
Sara Hooker's paper The Hardware Lottery describes a selection effect: research ideas are more likely to succeed and spread when available hardware and software make them easy to run.
The feedback loop is straightforward:
available hardware and libraries
-> reliable, cheap implementations of favored operations
-> more experiments and deployment
-> more models designed around those operations
-> more investment in the same hardware path
This is not an argument that matrix multiplication is wrong. Dense matrix multiplication is extraordinarily useful. Accelerators, compilers, kernels, quantization schemes, and model architectures have made it efficient at enormous scale.
The question is where the fit is incomplete.
Wan2.2 adds normalization, positional operations, attention selection, sparse indexes, guidance, scheduler updates, VAE decode, communication, and repeated state movement. A coding agent adds prefix reuse, active KV growth, CPU tools, storage reads, test execution, retries, and durable state. Optimizing only the dense operation can leave a movement, synchronization, or workflow bottleneck untouched.
Ali's worklog is useful here because the reported end-to-end result combines algorithm, kernels, precision, step count, fusion, and scheduling. It does not prove hardware should abandon GEMM. It shows why an end-to-end workload can improve through several layers at once and why each layer needs its own receipt.
The hardware-lottery lesson is practical: expose and measure the operations and state paths that the current stack handles poorly. Then compare a tuned commercial baseline before asking for new hardware.
John Carmack: predictable reads create a scheduling opportunity
John Carmack's public post argues that inference weight access can be deterministic enough to schedule large pages ahead of use and keep a smaller active window in faster memory. We paraphrase the primary post because ordinary web extraction is incomplete. [PRIMARY SOCIAL / AUTHOR ARGUMENT] It is a proposal, not a benchmark.
The strongest version of the idea is not flash is as fast as HBM. It is:
known access order
+ high useful bytes per fetched page
+ enough lookahead
+ parallel page reads
+ bounded first-byte and tail latency
+ double-buffer capacity
+ correct miss fallback
= a chance to hide slower, denser storage behind compute
Imagine that a layer consumes weight pages in a known order. Buffer A holds the pages currently feeding compute. Buffer B receives the next pages. When compute finishes A, the buffers swap. If transfer of B always completes before the swap and most fetched bytes are used, a large read-mostly tier can reduce how much state must remain in HBM.
The schedule breaks when a branch changes the access order, the page contains little useful data, queue contention stretches p99, writes become frequent, the hot window does not fit, or compute is too fast to hide transfer.
It also does not automatically apply to every AI state. Active KV is append-only and repeatedly read. A diffusion latent is mutable every step. Sparse attention can gather irregular regions. Coding-agent tools branch based on external results. Safety-critical state needs bounded worst-case behavior and fault containment.
Sandisk's HBF proposal gives the idea a vendor architecture direction. Its capacity, bandwidth, and Llama figures remain vendor targets or internal simulation. The SK hynix/Sandisk announcement establishes a standards workstream. Kioxia's separate module establishes a prototype. None is a shipping HBF workload result.
Unconventional AI is pursuing a first-principles, physics-led hardware and software co-design direction that treats parameter memory and working memory as separate design problems. We admire the attempt to connect algorithms, circuits, devices, and manufacturing, and leave the comparison there.
The shared lesson is not build a new memory. It is turn the access hypothesis into a trace, a schedule, a correct fallback, and a comparison against tuned HBM.
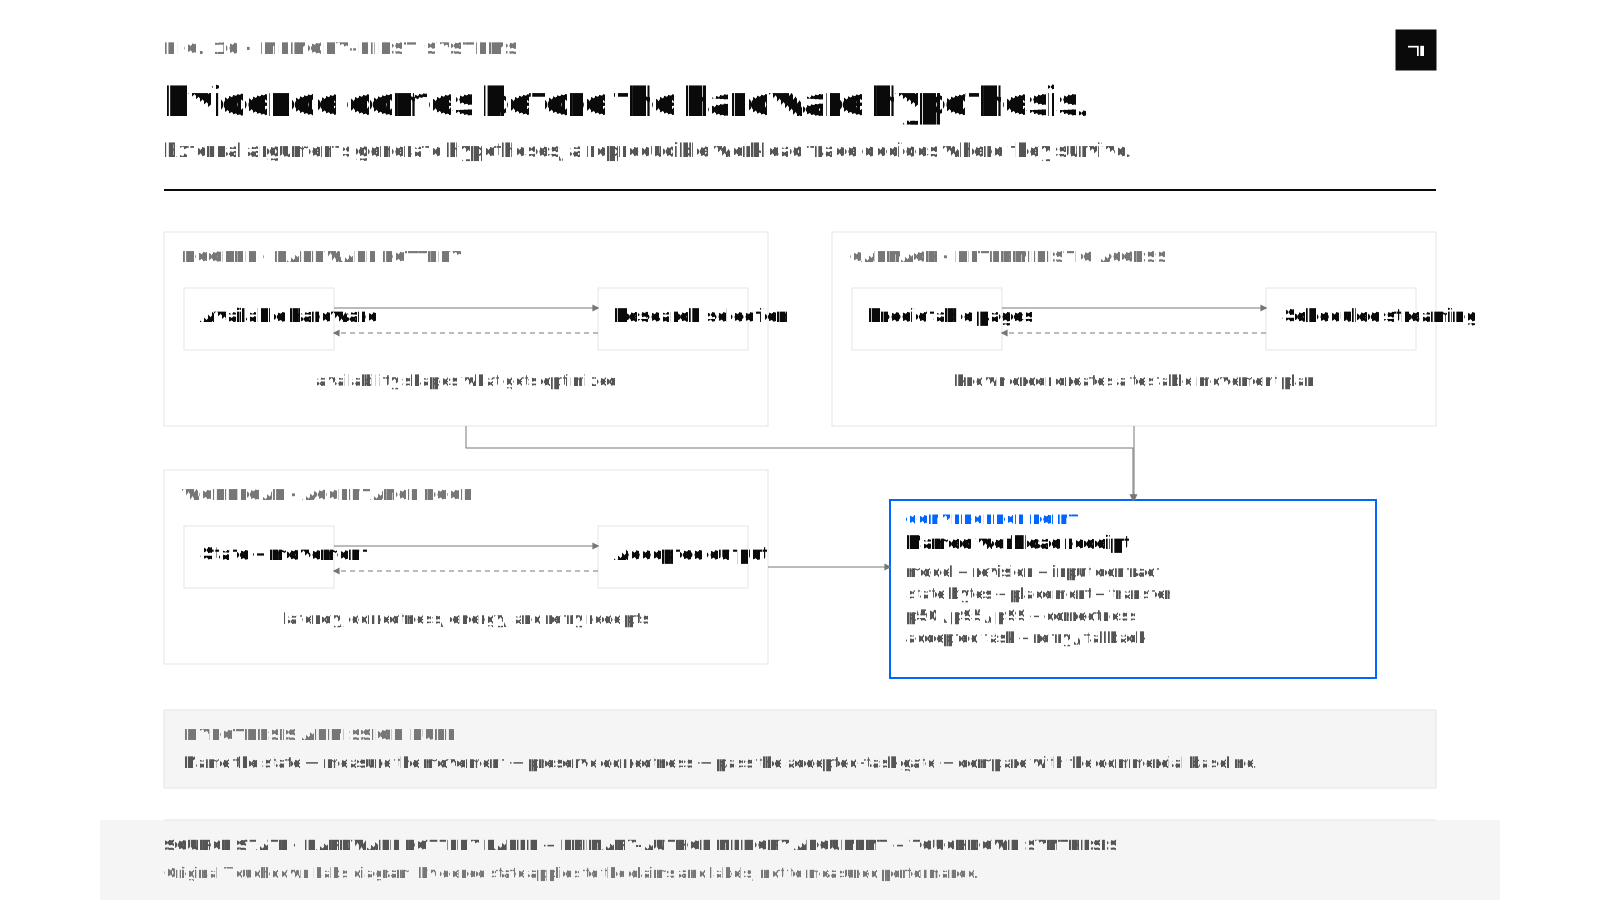
What is the narrow Touchdown hypothesis?
In plain English. This is a research hypothesis, not a shipping memory product. First measure a real accepted workload. Then exhaust competent software and available memory options. Only a repeated bottleneck that survives those tests earns a small, typed hardware or controller experiment.
Touchdown starts with HBM as the commercial baseline. Our hypothesis is that software should describe state precisely enough to compare placement, movement, retention, repair, and fallback across commercial tiers now and physical candidates later.
A public state contract can be small:
# [PROPOSED] Illustrative public contract
state_object:
identity: named_tensor_or_workflow_object
shape_dtype_bytes: measured_or_derived
access: {pattern: named, mutability: named, predictability: measured}
reuse: {distance_distribution: measured, fanout: measured}
timing: {first_byte_p99_ms: named, completion_p99_ms: named}
correctness: {error_budget: exact_or_bounded, recompute_ms: measured}
movement: {sources: [named], targets: [named], granularity_bytes: named}
fallback: named_correct_path
evidence: {source: immutable_trace, version: immutable_id}
The contract does not make physical memories interchangeable. It gives a compiler or runtime enough information to test primitives such as place, prefetch, stream, gather, compress, rematerialize, checkpoint, evict, migrate, replicate, refresh, repair, scrub, and fallback.
Each primitive needs preconditions, a target-specific lowering, observable counters, a failure rule, and a correct fallback. stream could lower to CUDA/NIXL movement from host memory, an NVMe read, a future HBF controller, or a custom base-die function. Those are different implementations with different physics, not loose hardware Lego.
The direction is supply-chain-first. Each physical lowering must name the commercial parts, interfaces, packaging, test, repair, qualification path, and merchant fallback that exist before it earns a custom controller or memory program. The software contract can be composable. The manufacturing stack remains constrained by real materials, tools, suppliers, yields, and volumes.
HBM remains the tournament baseline. A candidate must beat tuned HBM plus caching, batching, fusion, compression, recomputation, and commercial offload for one named state role. It does not need to replace HBM universally.
The admission gates are intentionally hard:
| Gate | Evidence required |
|---|---|
| G0: real joined trace | Join a real request, runtime events, state objects, accepted output, and business outcome without inventing physical bytes. |
| G1: durable bottleneck | Show that the bounded movement or retention bottleneck recurs under controlled repetition and relevant variation. |
| G2: tuned commercial baseline | Show that the opportunity survives competent HBM, DDR/LPDDR, NUMA/CXL, caching, offload, batching, kernel, and runtime tuning with parity. |
| G3: portable recipe value | Show that a versioned recipe creates value across more than one supported backend under equivalent output contracts. |
| G4: simulator plus physical anchor | Show that a calibrated simulator agrees closely enough with an FPGA or RISC-V controller prototype to justify physical continuation, with fallback, fault injection, and resource/timing receipts. |
| G5: joint-IC and manufacturing case | Show value across three workloads with named memory, logic, package, and manufacturing partners, qualification risks, kill criteria, and a merchant fallback. |
The existing public compiler work is fixture-backed where its tests pass. It is not a G4 physical anchor, custom HBM, a tape-out, or a manufacturing commitment.
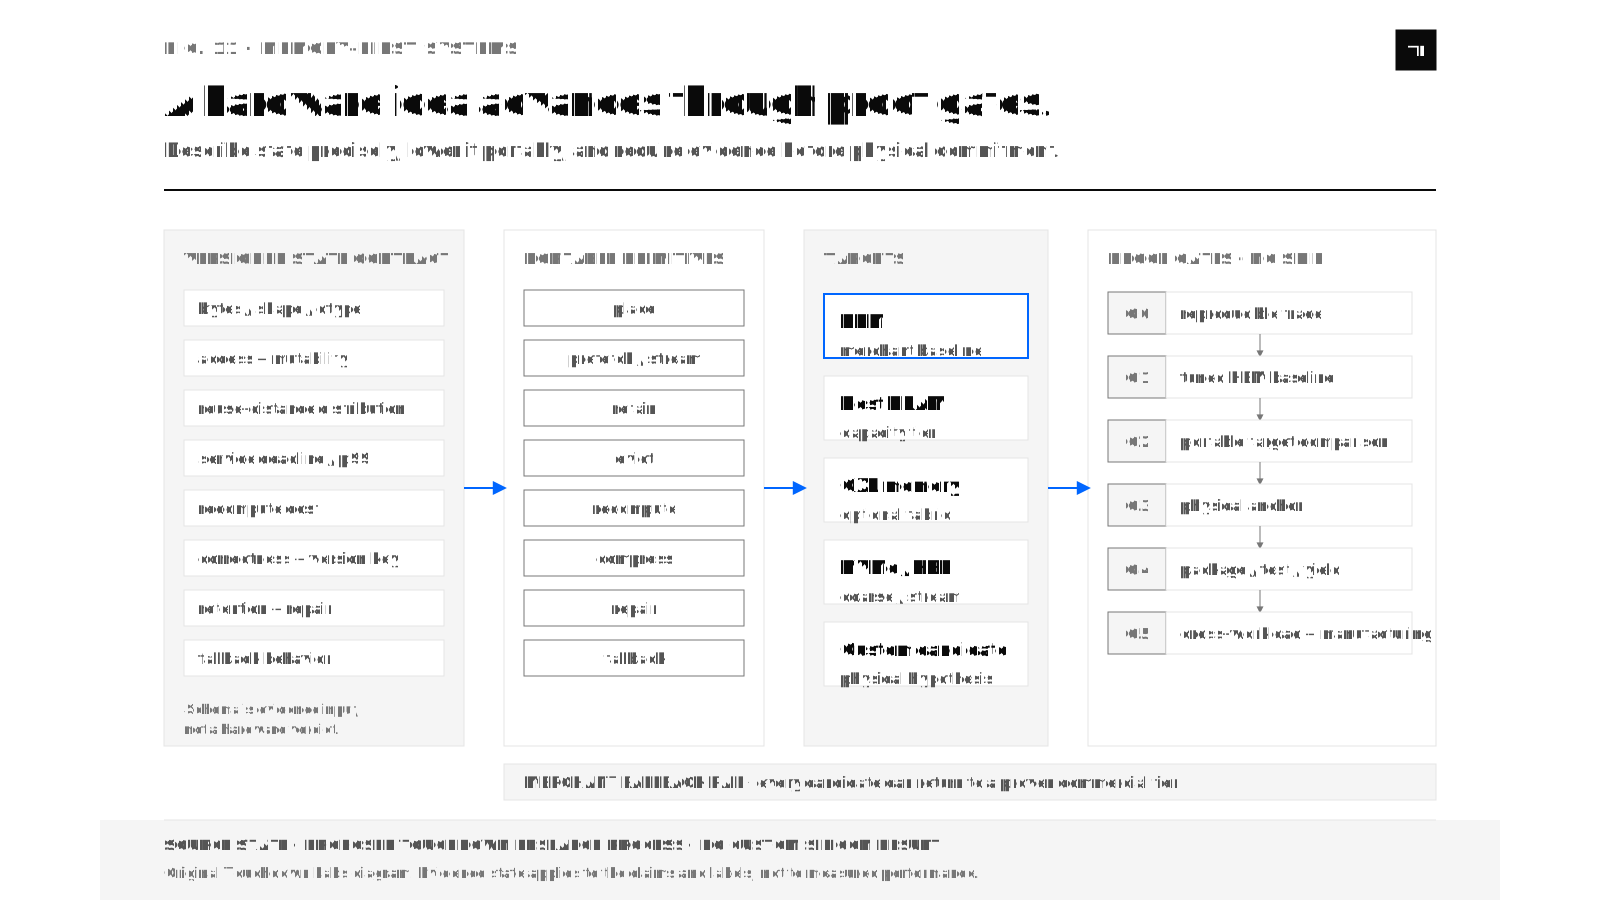
Updated July 27, 2026 · investor-to-engineer guide
CXMT’s HBM path starts with DRAM manufacturing, then adds stacking, packaging, qualification, and workload proof.
CXMT already makes conventional DRAM. HBM stacks thin DRAM dies beside an AI accelerator so far more data can move at once. This fourteen-step chapter separates shipping products, reported plans, patents, engineering requirements, supplier coverage, qualification, and the receipts still needed to prove a working HBM system.
What evidence would prove or disprove this architecture?
In plain English. A diagram, installed package, vendor specification, or successful import is not enough. The proof has to join one workload identity, pinned source, selected runtime and kernel, real hardware, measured movement and energy, the final output, and the verifier that accepted or rejected it. Missing fields remain unknown.
The hypothesis weakens if state descriptors fail on held-out workloads, transfer overhead erases capacity gains, compression or recomputation wins at lower complexity, or a tuned HBM-only baseline remains better on accepted-task cost, latency, energy, and reliability. It also fails if tail misses, stale state, thermal limits, test coverage, yield, repair, supplier access, or qualification make the physical path unsafe or uneconomic.
The next public receipt should use one schema and harness for both workloads:
pinned Wan2.2 trace on a named GPU
+ coding-agent KV/tool trace on a named model and GPU
+ tuned HBM-only baseline
+ tuned host-offload baseline
+ CXL or NVMe lane only when the named hardware exists
+ placement bytes, p50/p95/p99, capacity, energy source, acceptance result
+ versions, raw artifacts, negative cases, and correct fallback
A simulator remains modeled. An absent CXL device remains NOT FOUND, not a synthetic win.
| Reader | Decision | Receipt before spending |
|---|---|---|
| CEO | Which workflow outcome is memory-limited? | Accepted-task baseline and failure ledger |
| CFO | Do savings exceed movement, engineering, energy, and supply cost? | Range model tied to measured acceptance and throughput |
| Investor | Is advantage in software, controller, package, device, supply, or workload data? | Evidence gate, ownership, dependencies, time to proof |
| CTO | Which reversible test comes first? | Trace, tuned baseline, migration and rollback |
| Software/kernel engineer | Which object and operation create the traffic? | Source, allocation, counters, timeline, parity |
| Memory/package engineer | Can it be powered, cooled, tested, repaired, yielded, and supplied? | PDN, thermal, DFT/repair, process and supply diligence |
The complete explanation stays public. The companion repository can carry schemas, calculators, synthetic fixtures, and source-linked examples. A paid release earns its price only when it adds runnable, pinned labs, traces, notebooks, failure cases, and maintained updates.
Frequently asked questions
What is HBM and why is it used for AI?
HBM is stacked DRAM connected to an accelerator through a very wide, short package interface. Its channel parallelism and proximity provide high local bandwidth for weights, KV cache, activations, latents, and communication buffers. Value still depends on useful traffic, capacity, power, heat, yield, and software.
How is HBM different from ordinary DRAM?
HBM uses DRAM cells, but organizes, stacks, and packages them differently from common DDR DIMMs. Vertical TSV connections, many channels, base/interface logic, and dense accelerator-side routing create a wider local path. The cell still needs sensing, restore, refresh, test, and repair.
What are TSVs and what does the HBM base die do?
TSVs are vertical conductors through thinned silicon. They connect dies in the stack. The base/interface die connects stack traffic to the package and can contain PHY, control, test, repair, RAS, or vendor-specific logic. Its exact partition is not universal.
Why is useful HBM bandwidth lower than peak bandwidth?
Peak bandwidth is an interface ceiling. Useful bandwidth loses to scattered access, insufficient concurrency, row conflicts, refresh, turnarounds, cache/TLB behavior, repeated materialization, synchronization, communication, power, or another bottleneck. Measure the named workload at the named boundary.
Is HBM always faster than GDDR7, DDR5, or LPDDR5X?
No universal comparison is valid. HBM favors aggregate local width, GDDR favors high per-pin board-level graphics bandwidth, DDR favors host capacity and serviceability, and LPDDR favors power/capacity-density integration. Device, interface width, package, controller, access pattern, and workload decide.
Can CXL memory replace HBM?
CXL can expand or pool coherent memory capacity, but it does not turn farther memory into HBM. It can hold workload-defined warm state when measured transfer and access meet the deadline. Hot mutable state usually remains a poor default candidate.
Can NVMe or HBF hold model weights?
Predictable, read-mostly pages may be streamable from flash-class capacity when lookahead, page usefulness, queue depth, buffering, and tail latency work. Active mutable state and random fine-grained access remain poor default fits. HBF is not yet shipping workload proof.
What is Intel XBM?
Intel XBM is cross-batch memory in US 2026/0191095 A1. The application describes backend-transistor DRAM, fine subchannels, TSV organization, test/repair, base-die options, serialized UCIe-facing links, and package variants.
Is Intel XBM a shipping product?
No. Intel XBM is a published patent application, not a confirmed shipping product. The filing does not prove working silicon, measured bandwidth, latency, energy, thermals, retention, yield, cost, software, schedule, qualification, or availability.
What is custom HBM or SPHBM4?
Custom HBM expands the logic and control that can be tailored around an HBM stack, especially at the base/interface die. Standard Package High Bandwidth Memory (SPHBM4) is JEDEC JESD330-4, an HBM4-stack direction with a different buffer/interface die for standard-package integration. A standard or vendor roadmap does not prove access, economics, or workload benefit.
How large is an LLM KV cache?
Logical size is 2 * layers * kv_heads * head_dim * bytes_per_element * sum(tokens_i across live sequences). For equal-length sequences, this becomes the familiar per-sequence token count times concurrency. Actual residency also includes paging, block rounding, fragmentation, metadata, sharing, replication, sharding, and quantization. Use the named model configuration and runtime allocation trace.
Why does Wan2.2 stress memory differently from a coding agent?
Wan2.2 repeatedly updates a large latent and runs conditional and unconditional denoising across many transformer blocks and steps. A coding agent grows KV, reuses prefixes, leaves the GPU for CPU tools and tests, branches, and retries. Their state lifetimes differ.
What is NVIDIA Kyber and how does it relate to HBM?
Kyber is NVIDIA's official next-generation MGX NVL rack design, not a GPU or HBM generation. One Kyber rack is planned as Vera Rubin Ultra NVL144, and eight Kyber racks later form Feynman NVL1152. HBM supplies local accelerator memory; Kyber changes the rack and scale-up boundary across which distributed workloads may move data. No public Wan2.2-on-Kyber benchmark was verified.
What does the hardware lottery mean for AI accelerators?
It means ideas that fit available hardware and software are easier to test, scale, and adopt. It does not mean GEMM is wrong. It tells engineers to measure operations and state paths that the current stack handles less well before proposing new hardware.
What would prove composable memory-movement primitives are useful?
They need a reproducible trace, durable bottleneck, tuned commercial baseline with parity, portable value across supported backends, a calibrated model plus bounded physical anchor, and repeated cross-workload evidence with a credible manufacturing plan and merchant fallback.
Secondary analyst research that helped us find the right questions. SemiAnalysis helped frame the history and economics of the memory wall, the HBM roadmap, Vera Rubin co-design, and the HBM4, custom-HBM, cooling, and packaging questions raised at ECTC 2026. SemiVision helped surface the AI memory-supply problem, the three HBM battlegrounds, 3D-stacked SRAM, and the question of whether ZAM could complement or replace HBM. These are secondary analyst synthesis, not the authority for product specifications or Touchdown measurements. Some links are paid. We do not reproduce their prose, tables, images, forecasts, or proprietary data. Primary vendor documents, standards, papers, patents, public code, and named receipts govern every public factual claim in this article.
Primary sources and evidence notes
The source list preserves evidence state. Vendor metrics apply only to the named artifact and date.
- [FOUNDATIONAL MEMORY EDUCATION] Micron, Introduction to Memory, Samsung HBM overview, and SK hynix/TSMC logic-base-die announcement. DRAM cell, array, stacked-memory, TSV, and base-die teaching path.
- [OFFICIAL CUDA / PYTORCH DOCUMENTATION] NVIDIA CUDA Programming Guide, CUDA Best Practices Guide, and PyTorch CUDA semantics. Device/global memory, transactions, coalescing, and allocator-reservation boundaries.
- [PACKAGE / MATERIAL / FACILITY SOURCES] SK hynix wafer-level package process, Imec 16 nm-pitch ruthenium test structure, and The Green Grid PUE glossary. Functional packaging, explicitly bounded interconnect research, and facility-energy terminology.
- [PATENT APPLICATION] USPTO, US 2026/0191095 A1 and application 19/001,921 legal record. XBM architecture and legal status.
- [STANDARD, PUBLIC ANNOUNCEMENT] JEDEC HBM4 public announcement and SPHBM4 public page. No standard text or tables reproduced.
- [SHIPPING VENDOR ARTIFACT] Samsung HBM4 shipping announcement. Shipment, base-die, and named vendor metrics.
- [SHIPPING VENDOR ARTIFACT] Micron HBM4 production announcement and HBM4 product page. Named part and vendor metrics.
- [VENDOR PRODUCT ARTIFACT] Micron HBM3E product brief. Named HBM3E product family and vendor-scoped specifications.
- [VENDOR DESIGN SURFACE] Marvell custom-HBM compute architecture. Custom design claims remain vendor-scoped.
- [VENDOR PRODUCT] Micron LPDDR5X, LPDDR5X/DDR5 technical brief, Micron DDR5, Micron GDDR7, and Samsung GDDR7.
- [STANDARD, PUBLIC OVERVIEW] CXL Consortium overview. We did not process the restricted CXL 4.0 evaluation-specification download.
- [VENDOR PRODUCT ARTIFACT] Samsung MD210 CMM-D. Named CXL memory product state, not a workload result.
- [STANDARD ARCHIVE] NVM Express specification archives. NVMe lineage and block interface.
- [VENDOR ROADMAP / SIMULATION] Sandisk HBF fact sheet. Proposed HBF direction and vendor internal simulation.
- [STANDARDIZATION WORKSTREAM] SK hynix and Sandisk HBF announcement.
- [PHYSICAL PROTOTYPE] Kioxia high-bandwidth flash module announcement. Separate from Sandisk HBF.
- [PREPRINT] Ma and Patterson, arXiv:2601.05047. HBF and inference-memory framing.
- [OFFICIAL SOURCE] Wan2.2 pinned repository, including
wan_t2v_A14B.py,model.py, andtext2video.py. - [OFFICIAL PROJECT DESIGN / PAPER] DeepSpeed-Ulysses and arXiv:2309.14509. Sequence-parallel all-to-all mechanism; not a Wan2.2-on-Kyber result.
- [OFFICIAL MODEL CONFIGURATION]
Qwen/Qwen2.5-Coder-32B-Instructconfig at revision381fc969f78efac66bc87ff7ddeadb7e73c218a7. Source for the 64-layer, 8-KV-head, BF16 logical KV derivation; no runtime result. - [VENDOR BENCHMARK] Baseten, Wan2.2 video generation in less than 60 seconds. Exact vendor workload and reported 2.6 and 3.2 times results.
- [AUTHOR WORKLOG] Ali's Wan2.2 optimization article. Composite and individual results are not reproduced here.
- [ACCEPTED PAPER / SOURCE] Visual Sparse Attention, arXiv:2505.13389 and FastVideo. The arXiv record lists NeurIPS 2025 acceptance; measurements remain author-reported for the stated setup.
- [PAPER] Sara Hooker, The Hardware Lottery, arXiv:2009.06489.
- [PRIMARY SOCIAL] John Carmack's deterministic-access post. Paraphrased because ordinary extraction is incomplete.
- [OFFICIAL VENDOR DOCUMENTATION] NVIDIA Dynamo KVBM guide and vLLM KV offload guide. Reviewed at documented latest v1.2.1.
- [OFFICIAL PROJECT DOCUMENTATION, REVIEWED 2026-07-10] LMCache quickstart and dynamic connector documentation. Version-sensitive MP and dynamic connector guidance.
- [OFFICIAL PROJECT SOURCE, REVIEWED 2026-07-10] NousResearch Hermes Agent
run_agent.py. Public tool-calling and conversation-loop example, not a hosted-agent performance receipt. - [OFFICIAL PRODUCT DOCUMENTATION, REVIEWED 2026-07-11] Claude Code features and CLI reference. Context-loading, skills, subagents, structured output, tool, turn, and budget controls; not provider-hardware evidence.
- [OFFICIAL PROJECT DOCUMENTATION, REVIEWED 2026-07-11] OpenAI Codex CLI reference and Codex app-server protocol. Noninteractive JSONL execution and compaction events; not provider-hardware evidence.
- [OFFICIAL PROJECT DOCUMENTATION, REVIEWED 2026-07-11] OpenClaw memory documentation. Durable memory files, injection limits, memory flush, and compaction; distinct from runtime KV placement.
- [OFFICIAL MODEL ARTIFACTS, REVIEWED 2026-07-11] Z.ai GLM-5 repository, GLM-5.2-FP8, FP8 configuration, and NVIDIA GLM-5.2-NVFP4. Artifact-level parameter counts, context configuration, quantization scope, and launch commands; no Kyber accepted-patch result.
- [OFFICIAL CLOUD ARCHITECTURE DOCUMENTATION] Azure RAG information retrieval and hybrid search. Retrieval, ranking, and hybrid-search mechanics; not a Touchdown workload benchmark.
- [OFFICIAL PROJECT DOCUMENTATION, VERSION-SENSITIVE] SGLang server arguments. HiCache and LMCache control surfaces; a configured flag is not movement proof.
- [OFFICIAL VENDOR DOCUMENTATION, REVIEWED 2026-07-10] Dynamo disaggregated serving, vLLM examples, and Dynamo LMCache integration. Prefill/decode roles, NIXL transfer path, connectors, and current compatibility boundary.
- [OFFICIAL VENDOR DIRECTION] NVIDIA BlueField-4 STX and CMX context-memory platform. Architecture and vendor claims, not a Touchdown benchmark.
- [OFFICIAL CURRENT PRODUCT] NVIDIA H100, NVIDIA H200, NVIDIA GB200 NVL72, and NVIDIA GB300 NVL72. Product-scoped capacity, bandwidth, interconnect, and power figures.
- [OFFICIAL CURRENT PRODUCT] AMD Instinct MI350P, MI350P product brochure, and AMD enterprise deployment article. Product-scoped compute, 144 GB HBM3E, 4 TB/s, PCIe, power, cooling, physical, RAS, virtualization, software, enterprise-use, and up-to-eight-card partner-system boundaries; no Touchdown workload result.
- [OFFICIAL CURRENT PRODUCT] AMD Instinct MI355X and MI350 Series platform. Product-scoped HBM3E, bandwidth, Infinity Fabric, and TBP figures.
- [OFFICIAL CURRENT LAUNCH AND PRODUCTION REFERENCE DESIGN] AMD MI400 launch and AMD Helios launch. These July 23 sources establish the launched MI455X, published launch specifications, and AMD's Helios production-reference-design state. The end-Q3 shipment start and Q4 ramp remain forward-looking. They do not establish a Touchdown workload run or one directly sold AMD rack SKU.
- [HISTORICAL PRELAUNCH DIRECTION / CURRENT ROADMAP] AMD's 2025 Helios rack design, AMD's 2025 MI400 and Helios direction, and AMD CES 2026 MI500 preview. The first two preserve prelaunch history; MI500 remains a future roadmap.
- [TOUCHDOWN EVIDENCE REGISTRIES, INTERNAL DRAFT]
2026-07-10-amd-instinct-platform-engineering-ssot.md,2026-07-10-nvidia-accelerator-platform-engineering-ssot.md, and2026-07-10-amd-nvidia-platform-ssot-index.md. These internal registries preserve source state, scope, unknowns, and update history; they do not replace the linked primary vendor artifacts. - [FACILITY WATER SOURCES] The Green Grid WUE paper and Lawrence Berkeley National Laboratory workload water review. Accounting definitions and research synthesis, not a default liters-per-task factor.
- [PAPER, MODELED] Tu et al., RANA, ISCA 2018. Synthesized RTL, cycle-accurate simulation, and modeled energy for the stated CNN setup.
- [COMPANY TECHNICAL DIRECTION] Unconventional AI memory essay. Source for the adjacent-work acknowledgment.
- [OFFICIAL PRELIMINARY] NVIDIA Vera Rubin POD and Kyber topology and NVIDIA 800 VDC architecture. Official rack hierarchy and power direction, not a delivered workload result.
- [THIRD-PARTY REPORT] Tom's Hardware and Data Center Dynamics. Reported midplane and schedule concerns plus NVIDIA's reported response. Exact PCB, yield, supplier, qualification, schedule, and customer receipts remain not public.
- [STANDARD] UCIe specifications. Public generation and rate scope.
Additive implementation appendix: long-context decode datapaths, Blackwell qualification, and accepted-task resource receipts
In plain English. The main article explains the complete system. This appendix shows how to turn several important ideas into code and measurement packets: long-context attention, block-parallel softmax, low-precision Blackwell experiments, tool-window state, checkpointing, power, cooling, water, and cost per accepted patch.
Freeze notice. Everything above this line began as the canonical public-manuscript draft supplied on July 11, 2026. This appendix remains additive. The July 22 production pass installed three source-reviewed Touchdown figures. The July 23 update added the current AMD launch receipt, corrected the publication date, and preserved the earlier technical record. Neither pass replaced, deleted, reordered, compressed, or silently corrected the technical paragraphs, tables, equations, evidence labels, or source notes. Any later technical conflict must be recorded as a dated correction note rather than rewritten out of history.
Why long-context decode needs its own physical explanation
In plain English. During language-model decode, each new token uses attention state from earlier tokens. As the context grows, the model repeatedly reads a larger history while producing one next position. That makes data movement, placement, and tail latency different from the highly parallel first pass over the prompt.
The article has already separated prefill from decode. The next missing step is to show why long-context decode attention can stop looking like the large dense matrix work that accelerators handle best.
During prefill, many prompt positions are available together. Large projections and attention tiles can create substantial matrix-matrix work. During low-batch decode, one or a few new query positions attend over a large existing cache. The runtime repeatedly reads prior state, updates a running normalization, and reduces value vectors into one new output.
A simplified single-head decode step is:
scores_i = dot(q, k_i) * scale
probability_i =
exp(scores_i)
/ sum_j(exp(scores_j))
output =
sum_i(probability_i * v_i)
The mathematical expression is compact. The physical work is not:
read one new q
-> stream or gather many cached k vectors
-> calculate score fragments
-> maintain a numerically stable maximum and normalization sum
-> decide which v vectors must be read
-> accumulate the weighted output
-> write one result
At long context and low batch size, the query can be reused while the KV cache dominates bytes. This is a memory, reduction, and state-dependency problem even though dot products and multiply-accumulate operations remain inside it.
The KVStream post as an evidence-bounded design signal
[AUTHOR-REPORTED HACKATHON RESULT] Aarav Wattal reports that the KVStream team built a serial HLS/RTL streaming-attention tile, validated it against NumPy, passed RTL cosimulation, and synthesized it in Vivado at 200 MHz during an Anthropic, Etched, Cognition, and Mercor hackathon. The post reports:
serial measured tile projection:
approximately 1.3 times an H100 bandwidth baseline
modeled block-parallel plus Skip-Softmax:
approximately 5.9 times with a streaming policy
modeled two-pass upper bound:
approximately 7.7 times on peaked attention
These statements belong to the named 4K-context, attention-only projection and the team's stated model assumptions. They are not a GLM-5.2 benchmark, an end-to-end agent result, a B200 or GB200 result, a fabricated ASIC result, a complete power result, or independent reproduction.
The useful architectural claim is narrower:
Long-context decode attention can justify a datapath built around streamed KV access, local online-softmax state, block-level parallel reduction, and conditional suppression of value-path work.
That claim now becomes a Touchdown experiment lane.
Online softmax is a recurrence
In plain English. Softmax turns attention scores into normalized weights. An online version processes the score stream in pieces while carrying a small running summary: the largest score seen so far and the scaled sum needed for normalization. That avoids storing the full score matrix, but later pieces still depend on the summary produced by earlier pieces.
A stable streaming softmax can process scores without first materializing the complete score vector.
For scores processed in order, maintain:
m_i:
running maximum through position i
l_i:
running normalized denominator through position i
o_i:
running unnormalized weighted-value accumulator
For a new score s_i and value vector v_i:
m_new = max(m_old, s_i)
old_scale = exp(m_old - m_new)
new_scale = exp(s_i - m_new)
l_new =
old_scale * l_old
+ new_scale
o_new =
old_scale * o_old
+ new_scale * v_i
At the end:
output = o_final / l_final
This avoids a full score materialization, but it creates a dependency:
state_i
depends on
state_i-1
A serial datapath must wait for the running maximum, denominator, and output state. KV bandwidth alone does not remove that recurrence.
Reference implementation
The following reference is intentionally simple. It is a correctness oracle, not an optimized kernel:
from __future__ import annotations
import math
from collections.abc import Sequence
def online_attention(
scores: Sequence[float],
values: Sequence[Sequence[float]],
) -> list[float]:
if not scores or len(scores) != len(values):
raise ValueError("scores and values must be non-empty and aligned")
width = len(values[0])
if any(len(vector) != width for vector in values):
raise ValueError("all value vectors must have equal width")
if any(math.isnan(score) or score == math.inf for score in scores):
raise ValueError("scores may be finite or -inf for a masked position")
running_max = -math.inf
running_sum = 0.0
accumulator = [0.0] * width
for score, value in zip(scores, values):
if score == -math.inf:
continue
new_max = max(running_max, score)
old_scale = math.exp(running_max - new_max)
new_scale = math.exp(score - new_max)
running_sum = old_scale * running_sum + new_scale
accumulator = [
old_scale * old + new_scale * current
for old, current in zip(accumulator, value)
]
running_max = new_max
# Explicit reference semantics for a fully masked row. A production kernel
# must match its framework/backend contract rather than inheriting this choice.
if running_sum == 0.0:
return [0.0] * width
return [component / running_sum for component in accumulator]
Required tests:
compare against full softmax attention
random values
extreme score ranges
single element
all-equal scores
masked positions with -inf
all-masked row returns the declared zero vector
NaN and positive-infinity inputs fail visibly
peaked distributions
mixed positive and negative scores
FP32 reference
target dtype error envelope
Breaking the recurrence across blocks
In plain English. Independent blocks can compute partial softmax summaries, but the system must merge them with mathematically correct rescaling. Parallelism is useful only if the merge preserves the same answer within the declared numeric tolerance.
Divide the KV sequence into blocks. Each block independently computes a summary:
block maximum:
m_b
block denominator relative to m_b:
l_b = sum_i_in_block(exp(s_i - m_b))
block weighted-value accumulator:
o_b = sum_i_in_block(exp(s_i - m_b) * v_i)
Two block summaries can be merged exactly in real arithmetic:
m = max(m_a, m_b)
l =
exp(m_a - m) * l_a
+ exp(m_b - m) * l_b
o =
exp(m_a - m) * o_a
+ exp(m_b - m) * o_b
This creates a reduction tree:
KV blocks process in parallel
-> each emits m_b, l_b, o_b
-> hierarchical reducer merges block summaries
-> final normalization produces output
The recurrence has not disappeared. It moved from every KV position to a much smaller tree over block summaries.
Merge code
from __future__ import annotations
import math
from dataclasses import dataclass
@dataclass(frozen=True)
class SoftmaxBlock:
maximum: float
denominator: float
weighted_value: tuple[float, ...]
def merge_blocks(left: SoftmaxBlock, right: SoftmaxBlock) -> SoftmaxBlock:
if len(left.weighted_value) != len(right.weighted_value):
raise ValueError("block widths must match")
maximum = max(left.maximum, right.maximum)
left_scale = math.exp(left.maximum - maximum)
right_scale = math.exp(right.maximum - maximum)
denominator = (
left_scale * left.denominator
+ right_scale * right.denominator
)
weighted_value = tuple(
left_scale * a + right_scale * b
for a, b in zip(left.weighted_value, right.weighted_value)
)
return SoftmaxBlock(
maximum=maximum,
denominator=denominator,
weighted_value=weighted_value,
)
The hardware design must still answer:
How many KV blocks execute concurrently?
Where does q remain resident?
Where do K and V stream from?
How large is each block?
How are exp and reduction units provisioned?
How wide is the block-summary network?
How much local SRAM is needed?
How does the design handle causal masking and page boundaries?
How does it handle GQA, MLA, DSA, quantized KV, and sparsity metadata?
How does numerical error change with tree order?
Skip-Softmax-style value-path gating
In plain English. A value-path gate asks whether some work can be skipped or approximated without changing the accepted result beyond its tolerance. The optimization is not valid because it runs faster. It is valid only when the quality gate, error bound, and workload receipt still pass.
A block can have a score maximum far below the global maximum. Its exponential contribution can become very small after rescaling.
A hardware policy may first bound the block's unnormalized exponential mass:
unnormalized_mass_bound_b
=
number_of_items_b
* exp(block_max_b - current_global_max)
That expression does not by itself bound weighted-value or final-output error. To make an output claim, the experiment also needs a declared norm, component range, or other conservative bound for every value vector in the skipped block. If delta_b bounds the block's normalized probability mass and V_max bounds the chosen norm of its values, then a conservative bound for a kept-output that is renormalized after omission is:
output_error_bound <= 2 * delta_b * V_max
The exact factor depends on the approximation and norm. The implementation must derive the bound it actually enforces. If the denominator, value bound, numeric state, or mask semantics are unavailable, the safe fallback is to read and compute the block.
Only when the declared mass and value bounds remain below the accepted error budget may the design avoid some work:
skip or reduce:
V reads
exponential evaluations
probability-value MACs
This is not automatically exact. The experiment must name:
threshold
probability-mass bound
value-vector norm or range bound
derived output-error bound
dtype
accumulation order
error envelope
quality gate
fallback
For exact inference, gating must be proven not to alter the required output contract. For approximate inference, the accepted quality budget must be explicit.
Required labels:
measured serial RTL result
modeled block-parallel result
modeled gated result
ideal upper bound
fabricated-silicon result
end-to-end accepted-task result
Never merge those categories into one speedup.
How this maps to GLM-5.2
In plain English. GLM-5.2 adds sparse expert routing to the attention and decode path. Total model capacity, active experts per token, numeric format, KV state, expert placement, and communication are separate decisions. A single label such as
FP8 modeldoes not settle all of them.
Do not assume that GLM-5.2 uses a conventional dense K/V layout.
The pinned model, engine, and backend can use architecture-specific state including:
compressed latent KV
RoPE-related state
indexer state
indexer-K state
multiple cache groups
paged blocks
backend-specific scales and metadata
The exact GLM-5.2 decode experiment must begin by extracting the runtime cache geometry.
GLM52CacheGeometryReceipt:
schema_version: touchdown.glm52-cache-geometry.v1
run_id: string
model:
artifact_id: string
revision: string
architecture: string
runtime:
engine: sglang | vllm
revision: string
backend: string
container_digest: string
groups:
- group_id: string
semantic_role: string
dtype: string
block_size_tokens: int
bytes_per_block: int
scale_bytes_per_block: int | null
metadata_bytes_per_block: int | null
allocated_blocks: int
used_blocks: int
shared_blocks: int
device_resident_blocks: int
lower_tier_blocks: int
evidence:
startup_log: string
allocator_dump: string
profiler_trace: string | null
Only after this receipt exists may the design ask whether a KVStream-like tile can consume the actual state efficiently.
Blackwell lane: B200 before GB200 rack claims
In plain English. Prove the operation on one B200-class accelerator before using a GB200 rack label. A rack adds CPUs, multiple GPUs, scale-up fabric, networking, power, and cooling boundaries that a single-device run does not measure.
The qualification order is mandatory:
1. One B200 GPU, synthetic attention fixture
2. One B200 GPU, pinned GLM-5.2 operation
3. Eight B200 GPUs, TP8 / EP configuration
4. One GB200 superchip or bounded tray allocation
5. Bounded GB200 NVL72 worker group
6. Shared rack under realistic concurrency
At every step record:
exact GPU UUIDs
driver
CUDA
firmware
engine
model revision
quantization
KV dtype
parallelism
topology
background load
cooling boundary
power boundary
accepted output
No rack-level specification becomes per-request performance.
FP8 versus NVFP4 experiment
In plain English. Lower-precision formats can reduce weight capacity and traffic, but they can also change accuracy, kernel selection, scaling metadata, and hardware compatibility. Compare them on the same model, workload, quality gate, device scope, and software revision.
The comparison has four independent precision decisions:
weight storage
operator input activations
accumulation
KV/cache representation
Required experiment arms:
A:
GLM-5.2 FP8 artifact
runtime-resolved activation and accumulation path
runtime-resolved KV dtype
B:
NVIDIA GLM-5.2 NVFP4 artifact
NVFP4 only for documented eligible expert linear operations
shared expert and other modules preserved at their actual dtype
runtime-resolved KV dtype
C:
same as A with explicit FP8 E4M3 KV where supported
D:
same as B with explicit FP8 E4M3 KV where supported
Freeze:
repository revision
prompt and tools
retrieval spans
accepted-patch rubric
concurrency
parallelism
engine revision
hardware group
thermal starting state
retry budget
Report:
checkpoint bytes
runtime allocated bytes
KV bytes
free HBM
largest free block
TTFT
inter-token latency
committed output rate
tool wall time
end-to-end task time
GPU and rack joules
temperature and throttle state
accepted patch
Real tool-calling timeline
In plain English. The GPU does not run continuously during an agent task. The model may pause while a CPU searches files, edits code, runs tests, waits for storage, or returns tool output. The receipt must show those gaps instead of charging every delay to HBM or GPU kernels.
The same task must remain alive across GPU and CPU phases:
TURN-01
prefix validation
prefill
reasoning decode
read_file tool call
TOOL-01
CPU / storage reads repository file
GPU worker may serve other requests
current request KV remains, moves, or is released by policy
TURN-02
append tool result
suffix prefill
decode
apply_patch tool call
TOOL-02
patch writes
lint and tests
log capture
TURN-03
append test result
valid prefix reuse or safe miss
repair decode if needed
final answer
ACCEPTANCE
diff review
test verification
accepted or rejected patch
Required phase instrumentation:
from contextlib import contextmanager
import time
import torch
@contextmanager
def trace_phase(name: str, event_writer):
start_ns = time.monotonic_ns()
torch.cuda.nvtx.range_push(name)
event_writer({
"event_type": "phase_start",
"phase": name,
"monotonic_ns": start_ns,
})
try:
yield
finally:
end_ns = time.monotonic_ns()
torch.cuda.nvtx.range_pop()
event_writer({
"event_type": "phase_end",
"phase": name,
"monotonic_ns": end_ns,
})
The tool runner must never put raw secrets into the resource receipt. Store digests, counts, classifications, and approved excerpts only.
Checkpointing is a state-ownership experiment
In plain English. A checkpoint decides which state must survive interruption and who can restore it correctly. Saving everything is expensive. Saving too little can force recomputation or lose the exact context needed to continue safely.
The Doubleword checkpoint reverse engineering is architecture-specific to an RTX 4090 and driver 590.48.01. It proves that, in that fixture:
checkpoint:
GPU allocations and driver state moved into anonymous host memory
NVIDIA VMAs and file descriptors disappeared
the process disappeared from nvidia-smi
restore:
CUDA resources were recreated
fresh allocations were refilled
device state survived
It also reports that, for an 8,578 MiB fixture:
baseline full cycle:
approximately 4.5 seconds
direct pipe protocol:
approximately 3.9 seconds
transparent huge pages:
approximately 1.6 seconds
preallocated staging and asynchronous unmap:
approximately 1.2 seconds
Those measurements do not transfer automatically to Blackwell, Grace ARM, TP8, NCCL, SGLang, vLLM, or GLM-5.2.
The portable lesson is:
Checkpoint time can be dominated by host virtual-memory allocation, page faulting, and zeroing rather than the nominal accelerator link alone.
Blackwell checkpoint gates
Begin every row at NOT_RUN.
| Gate | B200 | GB200 |
|---|---|---|
| Single-process counter survives | NOT_RUN | NOT_RUN |
| GPU allocation disappears | NOT_RUN | NOT_RUN |
| Small one-GPU inference restores | NOT_RUN | NOT_RUN |
| CUDA graphs restore | NOT_RUN | NOT_RUN |
| HTTP service remains valid | NOT_RUN | NOT_RUN |
| Prefix cache is correct | NOT_RUN | NOT_RUN |
| KV state is correct | NOT_RUN | NOT_RUN |
| TP8 ranks quiesce together | NOT_RUN | NOT_RUN |
| NCCL state restores or rebuilds safely | NOT_RUN | NOT_RUN |
| CUDA IPC state restores or rebuilds safely | NOT_RUN | NOT_RUN |
| GLM-5.2 FP8 accepted patch | NOT_RUN | NOT_RUN |
| GLM-5.2 NVFP4 accepted patch | NOT_RUN | NOT_RUN |
| Restore p99 meets SLO | NOT_RUN | NOT_RUN |
| Total facility energy improves | NOT_RUN | NOT_RUN |
| Cost per accepted patch improves | NOT_RUN | NOT_RUN |
Allowed values:
PASS
FAIL
BLOCKED
NOT_OBSERVABLE
NOT_APPLICABLE
NOT_RUN
Quiescing a distributed worker
In plain English. To capture consistent distributed state, workers must reach a point where no hidden operation is still changing the data being saved. That controlled pause is quiescence.
A safe distributed checkpoint starts above CUDA:
stop new admissions
-> mark worker DRAINING
-> finish or cancel active requests
-> finish tool-result prefills
-> finish or abort collectives under runtime rules
-> flush event and allocator receipts
-> distributed barrier
-> prove every rank has zero active requests and collectives
-> lock CUDA processes
-> checkpoint in a documented order
from __future__ import annotations
from dataclasses import dataclass
from enum import Enum
class RankState(str, Enum):
SERVING = "serving"
DRAINING = "draining"
QUIESCED = "quiesced"
CHECKPOINTED = "checkpointed"
FAILED = "failed"
@dataclass(frozen=True)
class RankReceipt:
rank: int
pid: int
active_requests: int
active_collectives: int
state: RankState
def group_is_quiesced(receipts: list[RankReceipt]) -> bool:
return bool(receipts) and all(
receipt.active_requests == 0
and receipt.active_collectives == 0
and receipt.state is RankState.QUIESCED
for receipt in receipts
)
Never checkpoint one rank in the middle of a collective while peers continue.
Full checkpoint versus selective reconstruction
In plain English. A full checkpoint stores more state and can simplify recovery. Selective reconstruction stores less and rebuilds some state later. The right choice depends on restore time, determinism, correctness, storage traffic, and the deadline for resuming useful work.
Compare four modes:
| Mode | Weights | KV/prefix | CUDA context/graphs | Host/application state |
|---|---|---|---|---|
| Full CUDA image | Copy | Copy | Copy where supported | Retain |
| Selective session image | Reload from host/storage | Preserve only required sessions | Copy bounded control state | Retain |
| Runtime-native rebuild | Reload | Restore through engine/cache layer or recompute | Recreate | Retain receipts and identities |
| Cold restart | Reload | Miss/recompute | Recreate | Reconstruct from durable workflow state |
The preferred design is not known in advance.
A full GLM-5.2 worker can contain hundreds of gigabytes of weights and runtime state. Copying all of it may lose to reloading from a staged host or storage path. Conversely, reconstructing graphs and runtime state can dominate a smaller image. Measure the complete transition.
State-aware tool-window policy
In plain English. Agent context should not grow without a rule. Preserve evidence that still changes the decision, summarize or move older material when provenance survives, and reject any compaction that causes the verifier or policy checks to fail.
A tool call creates a next-use prediction problem.
Inputs:
expected tool duration distribution
current GPU pressure
other queued requests
request KV bytes
shared-prefix references
weight residency ownership
checkpoint bytes
measured checkpoint and restore p99
next-turn deadline
host-memory pressure
cooling and power state
Scheduling actions and state-lifecycle actions are separate. Serving another request does not say whether this request's KV stayed in HBM, moved, or was checkpointed.
scheduling:
HOLD_CAPACITY
SERVE_OTHER_REQUESTS
state lifecycle:
KEEP_WARM
RELEASE_REQUEST_KV
OFFLOAD_REQUEST_KV
SELECTIVE_CHECKPOINT
FULL_CHECKPOINT
supervisor-only failure or rollback outcome:
TERMINATE_AND_REBUILD
TERMINATE_AND_REBUILD is deliberately not a StateAction below. A local tool-window helper must
not destroy an active session because a cost heuristic prefers it. Termination requires a separate
supervisor decision with explicit authorization, a receipt describing which state will be lost or
reconstructed, and a verifier-backed recovery path.
from dataclasses import dataclass
from enum import Enum
class SchedulingAction(str, Enum):
HOLD_CAPACITY = "hold_capacity"
SERVE_OTHER_REQUESTS = "serve_other_requests"
class StateAction(str, Enum):
KEEP_WARM = "keep_warm"
RELEASE_REQUEST_KV = "release_request_kv"
OFFLOAD_REQUEST_KV = "offload_request_kv"
SELECTIVE_CHECKPOINT = "selective_checkpoint"
FULL_CHECKPOINT = "full_checkpoint"
@dataclass(frozen=True)
class ToolWindow:
predicted_ms: float
next_turn_slack_ms: float
restore_p99_ms: float
full_checkpoint_restore_p99_ms: float
gpu_pressure: float
checkpoint_cost_usd: float
keep_warm_cost_usd: float
active_session_requires_exact_kv: bool
selective_checkpoint_preserves_exact_kv: bool
queued_request_count: int
@dataclass(frozen=True)
class ToolWindowDecision:
scheduling: SchedulingAction
state: StateAction
def choose_state_action(window: ToolWindow) -> StateAction:
# Exact-KV correctness is checked before cost or utilization.
if window.active_session_requires_exact_kv:
if (
window.selective_checkpoint_preserves_exact_kv
and window.restore_p99_ms < window.next_turn_slack_ms
):
return StateAction.SELECTIVE_CHECKPOINT
if window.full_checkpoint_restore_p99_ms < window.next_turn_slack_ms:
return StateAction.FULL_CHECKPOINT
return StateAction.KEEP_WARM
if (
window.gpu_pressure >= 0.9
and window.restore_p99_ms < window.next_turn_slack_ms
):
return StateAction.OFFLOAD_REQUEST_KV
if (
window.checkpoint_cost_usd < window.keep_warm_cost_usd
and window.restore_p99_ms < window.next_turn_slack_ms
):
return StateAction.SELECTIVE_CHECKPOINT
return StateAction.KEEP_WARM
def choose_tool_window_decision(window: ToolWindow) -> ToolWindowDecision:
scheduling = (
SchedulingAction.SERVE_OTHER_REQUESTS
if window.queued_request_count > 0 and window.predicted_ms > 0
else SchedulingAction.HOLD_CAPACITY
)
return ToolWindowDecision(
scheduling=scheduling,
state=choose_state_action(window),
)
This is a teaching policy, not a production optimum. A real implementation still needs measured queueing, checkpoint and restore distributions, cache identity, failure handling, power state, and a verifier-backed rollback rule.
Power measurement boundaries
In plain English. Power is an instantaneous rate. Energy is power integrated over a named time interval. A task receipt must align the workload start and stop with the device, server, or facility meter instead of treating a rated maximum as measured task energy.
Collect at least:
GPU device telemetry
complete server input meter
rack PDU
cooling equipment boundary when available
facility meter interval when available
Never add children to a parent meter that already includes them.
PowerBoundary:
boundary_id: string
parent_boundary_id: string | null
includes:
- gpu
- cpu
- host_memory
- nvlink_switch
- nic
- storage
- fans
- pumps
- conversion_losses
measurement_kind: measured | allocated | modeled | unknown
meter_id: string | null
sampling_interval_ms: float | null
Energy integration:
from __future__ import annotations
from dataclasses import dataclass
@dataclass(frozen=True)
class PowerSample:
monotonic_ns: int
power_w: float
def integrate_joules(samples: list[PowerSample]) -> float | None:
ordered = sorted(samples, key=lambda sample: sample.monotonic_ns)
if len(ordered) < 2:
return None
total = 0.0
for left, right in zip(ordered, ordered[1:]):
if right.monotonic_ns <= left.monotonic_ns:
raise ValueError("timestamps must increase")
elapsed_s = (
right.monotonic_ns - left.monotonic_ns
) / 1_000_000_000
total += (
(left.power_w + right.power_w)
/ 2.0
* elapsed_s
)
return total
Unknown or invalid intervals return null, not zero.
Cooling lag and heat balance
In plain English. Electrical work becomes heat quickly, but sensors, coolant, and facility equipment respond on different time scales. The accounting window must include that lag without pretending coolant flow is electrical energy or water consumption.
Electrical power changes before temperature and coolant return temperature.
The aligned timeline must include:
kernel or tool phase
GPU power
server/rack power
GPU and memory temperatures
clock/throttle state
coolant supply temperature
coolant return temperature
flow
differential pressure
pump/CDU power
ambient condition
For a single-phase coolant:
heat_transport_W =
mass_flow_kg_s
* specific_heat_J_kgK
* delta_T_K
This is the heat transported across that loop boundary. It is not automatically task electrical power.
Required lag windows:
pre-task baseline
task electrical interval
post-task thermal response
return-to-baseline or declared truncation
Water remains an allocation ledger
In plain English. Water circulating in a closed cooling loop is not the same as water consumed at the site. Site withdrawal, discharge, consumption, and water associated with electricity generation need separate boundaries and records.
Record separately:
closed-loop circulation
technology-loop makeup and loss
site withdrawal
site consumption
source-energy water
embodied manufacturing water
Never convert a coolant flow rate into water consumption.
WaterReceipt:
run_id: string
facility_interval_id: string
circulation_L: float | null
technology_loop_makeup_L: float | null
site_withdrawal_L: float | null
site_consumption_L: float | null
source_energy_water_L: float | null
embodied_water_estimate_L: float | null
allocation_method: string
evidence_state: measured | allocated | modeled | unknown
Accepted-patch economics
In plain English. A cheap model call is not a cheap coding result if retries, tool time, GPU idle time, failed tests, and human repair erase the savings. The denominator is an accepted patch, not a token.
The final denominator is the verified code change.
total_cost_per_accepted_patch =
(
model_and_accelerator_cost
+ CPU_and_tool_cost
+ memory_storage_network_cost
+ checkpoint_restore_cost
+ facility_energy_cost
+ allocated_cooling_and_water_cost
+ retry_and_failure_cost
+ human_review_cost
+ allocated_capital_and_support
)
/ accepted_patches
All attempted runs stay in the numerator. Only accepted patches enter the denominator.
Required comparison matrix:
| Artifact | Cache | Tool result | Lifecycle | Acceptance |
|---|---|---|---|---|
| FP8 | hit | first pass | warm | measured |
| FP8 | miss | retry | warm | measured |
| FP8 | hit | long tool | selective checkpoint | measured |
| FP8 | hit | long tool | full checkpoint | measured |
| NVFP4 | hit | first pass | warm | measured |
| NVFP4 | miss | retry | warm | measured |
| NVFP4 | hit | long tool | selective checkpoint | measured |
| NVFP4 | hit | long tool | full checkpoint | measured |
Every cell begins unpopulated.
Visual additions
In plain English. The visual system follows the same task identity through software, hardware, movement, facility, and cost. Animation explains a transition; it does not upgrade an architectural illustration into a measured run.
Append these scenes to the continuous left-side machine:
-
Decode is not one GEMM
- one query vector
- many KV blocks
- online maximum, denominator, and output accumulator
-
Serial recurrence
- each score updates the previous state
- KV bandwidth and recurrence highlighted separately
-
Block-parallel summaries
- independent block summaries
- reduction tree
- exact merge equations
-
Gated value path
- block contribution bound
- skipped V reads and MACs labeled modeled or measured
-
GLM-5.2 actual cache groups
- populated from runtime receipt
- generic K/V graphics prohibited when the backend uses another representation
-
B200 worker topology
- exact eight-GPU group
- HBM pools
- NVLink/NVSwitch path
- host memory and process ranks
-
GB200 rack slice
- Grace CPU
- Blackwell GPUs
- LPDDR and HBM
- NVLink-C2C and NVSwitch
- liquid loop and rack meter boundaries
-
Tool-call window
- request pauses
- sandbox works
- worker serves, offloads, checkpoints, or waits
-
Checkpoint host boundary
- page allocation
- zeroing
- copy out
- context teardown
- host residency
- restore
-
Electrical and thermal lag
- GPU power responds first
- junction temperature follows
- coolant return follows
- facility response follows
-
Accepted-patch ledger
- tokens
- KV
- GPU and server joules
- cooling
- water allocation
- tool and human work
- acceptance
Additive proof gates
In plain English. Every deeper claim needs a stronger receipt. Source code can prove that a path exists. A trace can prove that it ran. Counters can prove measured activity at a named boundary. Only the verifier can prove that the final task was accepted.
This appendix becomes publishable only when:
the frozen manuscript remains byte-for-byte unchanged above the marker
the exact GLM-5.2 artifact and engine are pinned
actual cache geometry is captured
FP8 and NVFP4 mixed-precision scopes are explicit
tool calls are joined to model phases
B200 measurements are separated from GB200 measurements
checkpoint claims carry platform and driver receipts
power boundaries do not double count
cooling lag is included
water circulation is not labeled consumption
all author-reported KVStream numbers retain their evidence label
accepted-patch results close the trace
unknown remains unknown
Final additive doctrine
In plain English. Keep the real task, technical path, physical boundary, evidence state, and accepted result connected. A useful explanation can become simpler to navigate without deleting the detail required to verify it.
Long-context decode can be limited by streamed state, reduction recurrence, and value-path work, not merely dense matrix throughput.
A custom datapath earns attention only after it is compared with a tuned Blackwell software baseline on the same model state, quality contract, and accepted task.
B200 and GB200 are not interchangeable measurement scopes.
FP8, NVFP4, accumulation precision, and KV precision are separate choices.
Checkpointing does not save energy merely because GPU allocations disappear.
Coolant flow is not water consumption.
Tokens are not the final product.
The trace ends only when the patch passes.